Contextual Hashing with Decoupled Localization for Efficient Video Corpus Moment Retrieval
Related Experiment Videos

Abstract:
The aim of Video Corpus Moment Retrieval (VCMR) is to locate temporal moments within a large video corpus on the basis of textual queries; however, it faces challenges in balancing retrieval efficiency and localization accuracy. Existing approaches typically rely on high-dimensional continuous embeddings for retrieval and computationally intensive coupled interaction networks for localization, thereby resulting in severe bottlenecks. To resolve this challenge, we propose a novel framework named Contextual Hashing with Decoupled Localization (CHDL). First, to address the efficiency issue, we introduce a temporal contextual hashing mechanism. This module projects high-dimensional video-text features into compact binary codes while preventing feature collapse through entropy maximization, thereby enabling ultra-fast retrieval through hardwarefriendly bit-wise Hamming distance computation. Second, we propose a decoupled multi-scale moment locator, that structurally decouples cross-modal semantic interactions from downstream temporal boundary prediction. By operating exclusively on one-dimensional relevance signals derived from a token-adaptive dynamic relevance model and using pyramidal dilated convolutions, this lightweight locator achieves precise temporal localization with minimal computational overhead. Furthermore, to ensure robust feature discriminability, we design a representation alignment objective that is based on dual-granularity mutual information maximization. This objective enforces alignment at both the global query-video level and the local token-frame level, thereby facilitating high-quality cross-modal interaction. The results of extensive experiments on the TVR and DiDeMo-FIG datasets demonstrate that CHDL achieves not only superior performance in localization accuracy but also a significant reduction in retrieval latency.
Related Concept Videos
 01:12
Retrieval
Recall involves accessing information without cues, such as during an essay test, where individuals must retrieve facts and concepts from memory unaided. Another example is remembering the name of a colleague...
 01:12
Chunking
The principle behind chunking is...
 01:05
Collisions in Multiple Dimensions: Introduction
 01:00
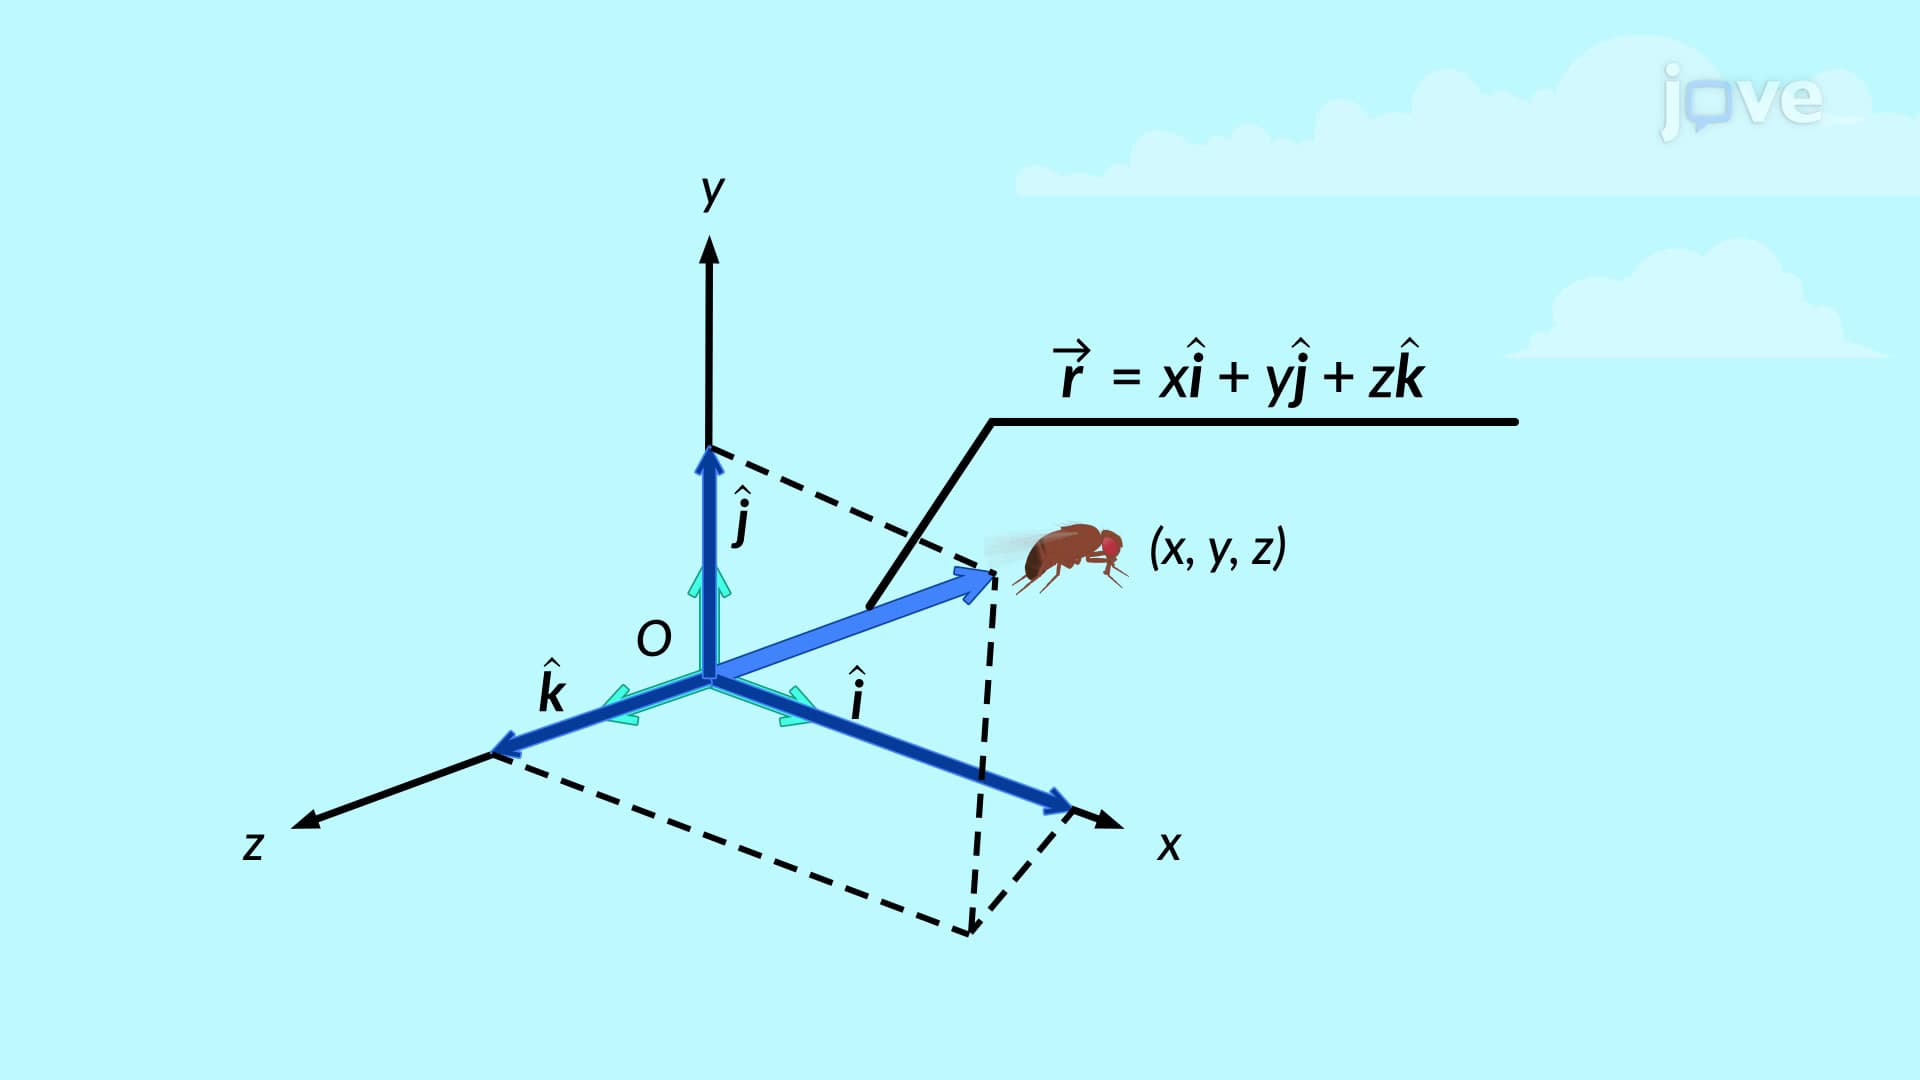
Position and Displacement Vectors
Further, several important kinds of...
01:00Position and Displacement Vectors
Further, several important kinds of...
 01:25
Relative Motion Analysis using Rotating Axes
However, to express the relative position of point B relative to point A, an additional frame of reference, denoted as x'y', is necessary. This additional frame not only translates but also rotates relative to the fixed frame, making it instrumental in...