pycircdb: integrated circRNA database annotation for computational workflows
Related Experiment Video
Updated: Nov 2, 2026
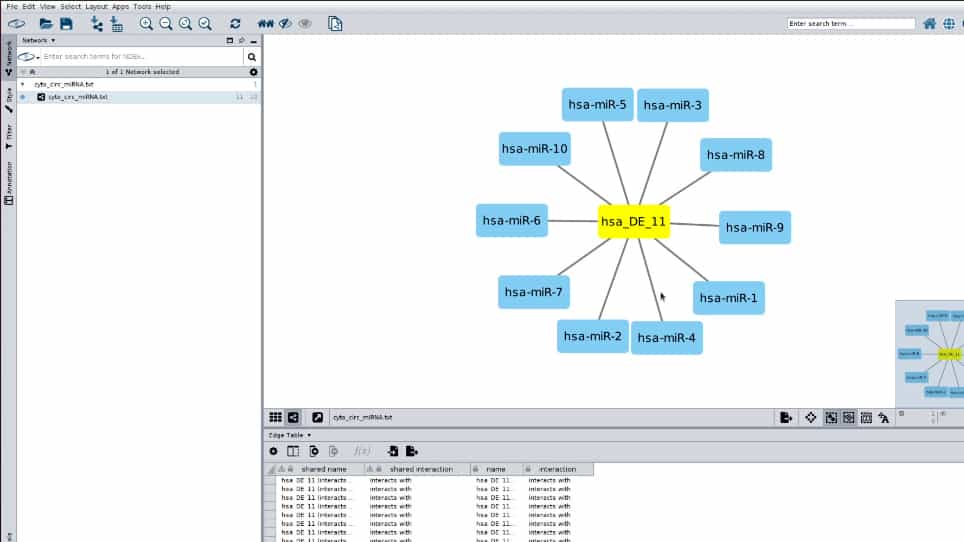
In Silico Identification and Characterization of circRNAs During Host-Pathogen Interactions
Published on: October 21, 2022
Barry Digby1, Stephen P Finn2, Pilib Ó Broin1
1School of Mathematical and Statistical Sciences and Institute for Health Discovery and Innovation, University of Galway, Galway, H91 TK33, Ireland.

Motivation:
Currently, multiple databases exist for the annotation of circular RNAs, providing descriptions of their genomic features, FASTA sequences, predicted microRNA targets and RNA-binding protein interactions. Despite the availability of these resources, annotation remains cumbersome. Conflicting identifiers and genomic coordinates for circular RNAs across databases pose a challenge to reproducibility for users. Furthermore, current databases primarily provide access via web-based graphical user interfaces, bulk downloads and limited programmatic access, rendering their use in computational workflows challenging.
Results:
We present pycircdb, a Python command-line interface tool that accepts genomic coordinates of human circular RNAs as input, facilitating rapid queries of multiple curated circRNA databases for reproducible annotation. Each pycircdb database has been normalized to a common 0-based representation and cross-mapped between the hg19 and hg38 assemblies, accepting as input circular RNA coordinates from 0-based and 1-based sources using a tolerant matching strategy. pycircdb utilizes Apache Hamilton in conjunction with Parquet files, providing a modular, parallelized workflow with minimal disk space requirements.
Availability And Implementation:
pycircdb is available for download via PyPI https://pypi.org/project/pycircdb under the GPL-3.0 license with source code and documentation available at https://github.com/BarryDigby/pycircdb and https://pycircdb.readthedocs.io/en/latest, respectively.