Related Experiment Video
Updated: Jul 18, 2026
09:12

The Resident-intruder Paradigm: A Standardized Test for Aggression, Violence and Social Stress
Published on: July 4, 2013
Prediction of violent versus nonviolent recidivism from prior violent and nonviolent criminality
Journal of Abnormal Psychology
|June 1, 1982

Abstract
No abstract available in PubMed .
More Related Videos
Related Concept Videos
 02:01
Group Design
The most basic experimental design involves two groups: the experimental group and the control group. The two groups are designed to be the same except for one difference— experimental manipulation. The experimental group gets the experimental manipulation—that is, the treatment or variable being tested—and the control group does not. Since experimental manipulation is the only difference between the experimental and control groups, we can be sure that any differences between the two are due to...
 02:24
Predicting Reaction Outcomes
Kinetics describes the rate and path by which a reaction occurs. In contrast, thermodynamics deals with state functions and describes the properties, behavior, and components of a system. It is not concerned with the path taken by the process and cannot address the rate at which a reaction occurs. Although it does provide information about what can happen during a reaction process, it does not describe the detailed steps of what appears on an atomic or a molecular level. On the other hand,...
 01:08
Determination of Expected Frequency
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
 01:11
Residuals and Least-Squares Property
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:19
Variation
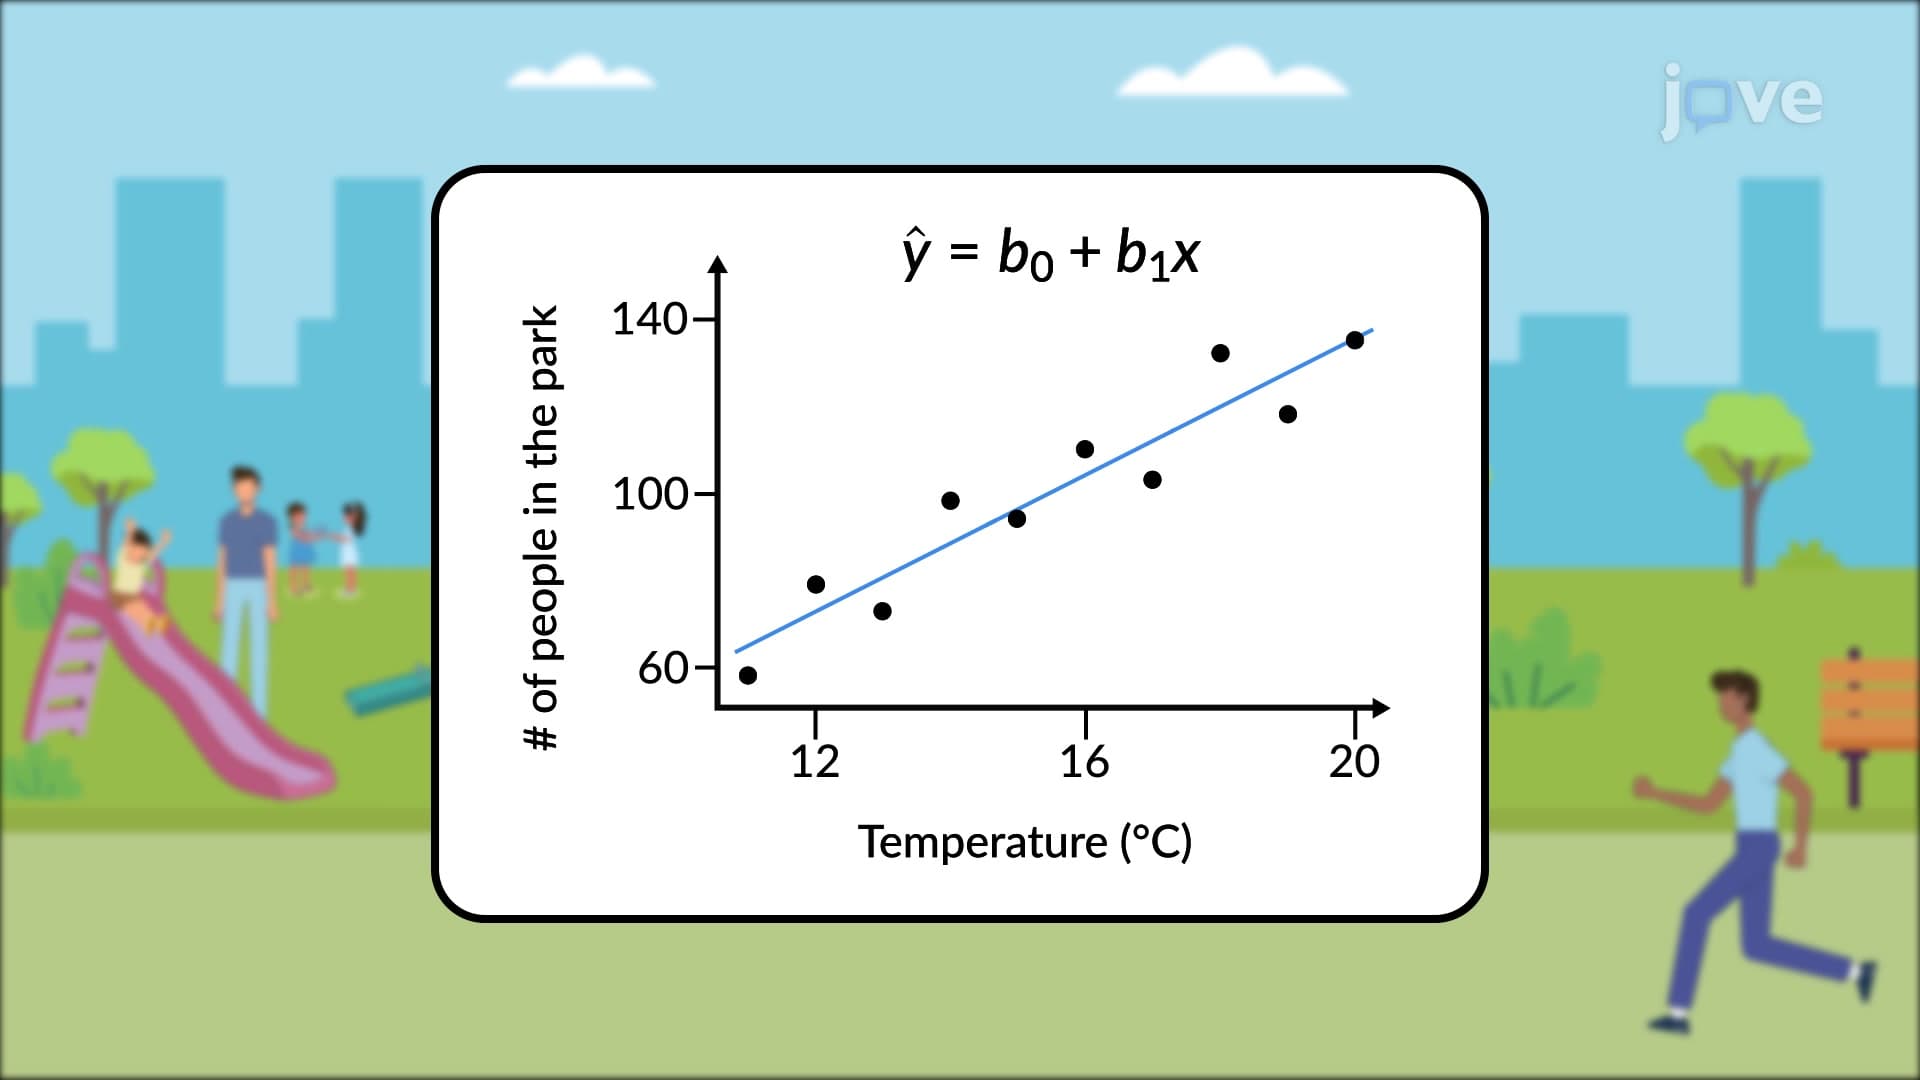
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:03
Prediction Intervals
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...