

利用蛋白质语言模型进行精确的多重序列对齐
Claire D McWhite1, Isabel Armour-Garb2,3, Mona Singh1,3
1Lewis-Sigler Institute for Integrative Genomics, Princeton University, Princeton, New Jersey 08544, USA; cmcwhite@princeton.edu mona@cs.princeton.edu.
Genome research
|July 6, 2023

概括
本研究引入了一种使用蛋白质语言模型的新多重序列对齐 (MSA) 方法. 它通过分析氨基酸嵌入,绕过传统的对齐步骤来实现对具有低序列身份的蛋白质更高的准确性.
科学领域:
- 生物信息学是一种生物信息学.
- 计算生物学 计算生物学
- 结构生物学 结构生物学
背景情况:
- 多个序列对齐 (MSA) 对于理解蛋白质序列和功能至关重要.
- 传统的MSA方法与表现出低序列标识 (暮色区) 的蛋白质进行斗争.
- 蛋白质语言模型通过生成能够捕捉氨基酸性质的上下文嵌入来提供一种新的方法.
研究的目的:
- 开发一种新的多重序列对齐 (MSA) 方法,利用蛋白质语言模型.
- 为了提高低序列身份的蛋白质的对齐精度.
- 为了规避传统MSA算法的局限性.
主要方法:
- 来自蛋白质语言模型的氨基酸上下文嵌入的聚类和排序.
- 开发一种基于蛋白质组的语义一致性的新型MSA方法.
- 避免使用传统的MSA组件,如导向树,对齐对齐,差距处罚和替换矩阵.
主要成果:
- 新的MSA方法对具有较低氨基酸相似度的结构相似蛋白质表现出更高的准确性.
- 这种方法有效地利用了来自上下文嵌入的信息.
- 基于语义一致性的蛋白质组的成功对齐.
结论:
- 蛋白质语言模型为MSA提供了一个强大的新信息来源.
- 拟议的方法为对齐具有挑战性的蛋白质集提供了更准确的替代方案.
- 这种方法预计将成为未来MSA算法的基本组成部分.

相关概念视频
 02:26
Conservation of Protein Domains Over Different Proteins
10.9K
Protein domains are small structurally independent units that are part of a single amino acid chain. Although these domains are often structurally independent, they may rely on synergistic effects to perform their functions as part of a larger protein. Protein domains may be conserved within the same organism, as well as across different organisms.
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to...
10.9K
02:26Conservation of Protein Domains
3.1K
3.1K
 02:07
Improving Translational Accuracy
11.7K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
11.7K
 02:51
Multi-species Conserved Sequences
4.0K
Next-generation sequencing technologies have created large genomic databases of a variety of animals and plants. Ever since the human genome project was completed, scientists studied the genome of primates, mammals, and other phylogenetically distant living beings. Such large-scale studies have provided new insights into the evolutionary relationship between organisms.
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved...
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved...
4.0K
 02:28
Leaky Scanning
5.2K
During most eukaryotic translation processes, the small 40S ribosome subunit scans an mRNA from its 5' end until it encounters the first start AUG codon. The large 60S ribosomal subunit then joins the smaller one to initiate protein synthesis. The location of the translation initiation is largely determined by the nucleotides near the start codon as there may be multiple translation initiation sites present on the mRNA. Marilyn Kozak discovered that the sequence RCCAUGG (where R...
5.2K
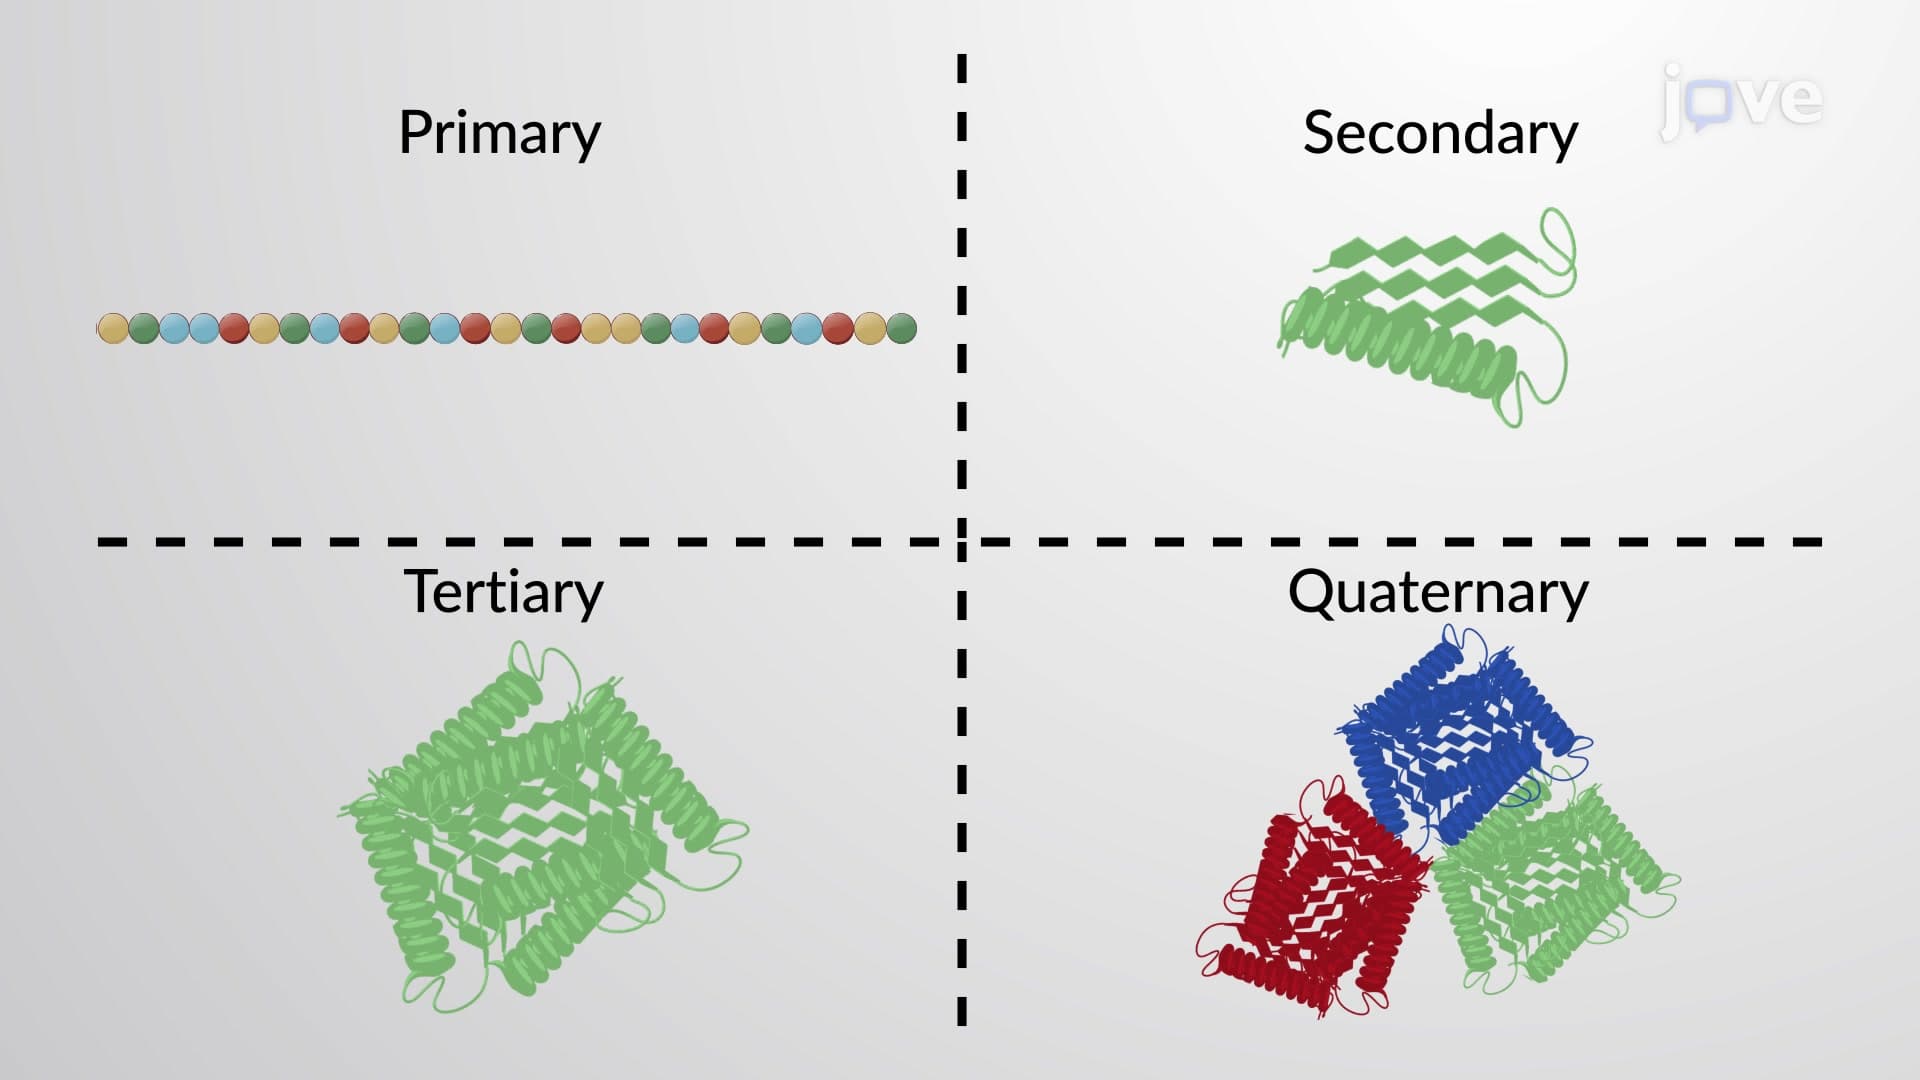 02:15
Protein and Protein Structure
79.8K
Proteins are one of the most abundant organic molecules in living systems and have the most diverse range of functions of all macromolecules. Proteins may be structural, regulatory, contractile, or protective. They may serve in transport, storage, or membranes; or they may be toxins or enzymes. Their structures, like their functions, vary greatly. They are all, however, amino acid polymers arranged in a linear sequence.
A protein's shape is critical to its function. For example, an enzyme...
A protein's shape is critical to its function. For example, an enzyme...
79.8K