
用机器学习模型预测和解释:社会科学作为试金石
Oliver Buchholz1, Thomas Grote1
1University of Tübingen, Cluster of Excellence: "Machine Learning: New Perspectives for Science", Ethics and Philosophy Lab, Maria von Linden Str. 6, D-72076 Tübingen, Germany.
Studies in history and philosophy of science
|November 4, 2024

概括
机器学习 (ML) 模型在自然科学方面表现有希望,但在社会科学方面却扎不前. 本研究提出了一种综合性方法,将解释和ML模型结合起来,以提高社会科学研究中的预测成功率.
科学领域:
- 社会科学 社会科学 社会科学
- 计算社会科学 计算社会科学
- 预测建模预测建模
背景情况:
- 机器学习 (ML) 模型在自然科学中的预测任务中取得了重大成功.
- 然而,它们在社会科学中的应用和好处,特别是在预测生命轨迹方面,仍然不那么明显,传统的指标往往不成功.
研究的目的:
- 调查社会科学预测中的ML模型性能差距背后的原因.
- 突出预测作为社会科学的关键目标,以及解释.
- 提出一种新的建模方法,以提高社会科学中ML模型的有效性.
主要方法:
- 对两个社会科学案例研究与自然科学范式进行比较分析.
- 在社会科学背景下,识别阻碍纯ML预测的特定约束.
- 开发一个整合性建模框架.
主要成果:
- 该研究确定了阻碍社会科学中纯ML预测成功的关键约束因素.
- 它强调了预测作为社会科学的科学目标的重要性,与解释相比.
- 拟议的综合性方法提供了一个潜在的解决方案,以弥合业绩差距.
结论:
- 将解释性模型与预测性ML模型相结合,对于推进社会科学研究至关重要.
- 这种混合方法可以克服复杂社会系统中纯粹的ML预测的局限性.
- 未来的研究应该专注于实施和验证这些综合战略.
相关概念视频
 01:18
Steps in Outbreak Investigation
107
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
107
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
29
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
29
 01:22
Statistical Package for the Social Sciences (SPSS)
270
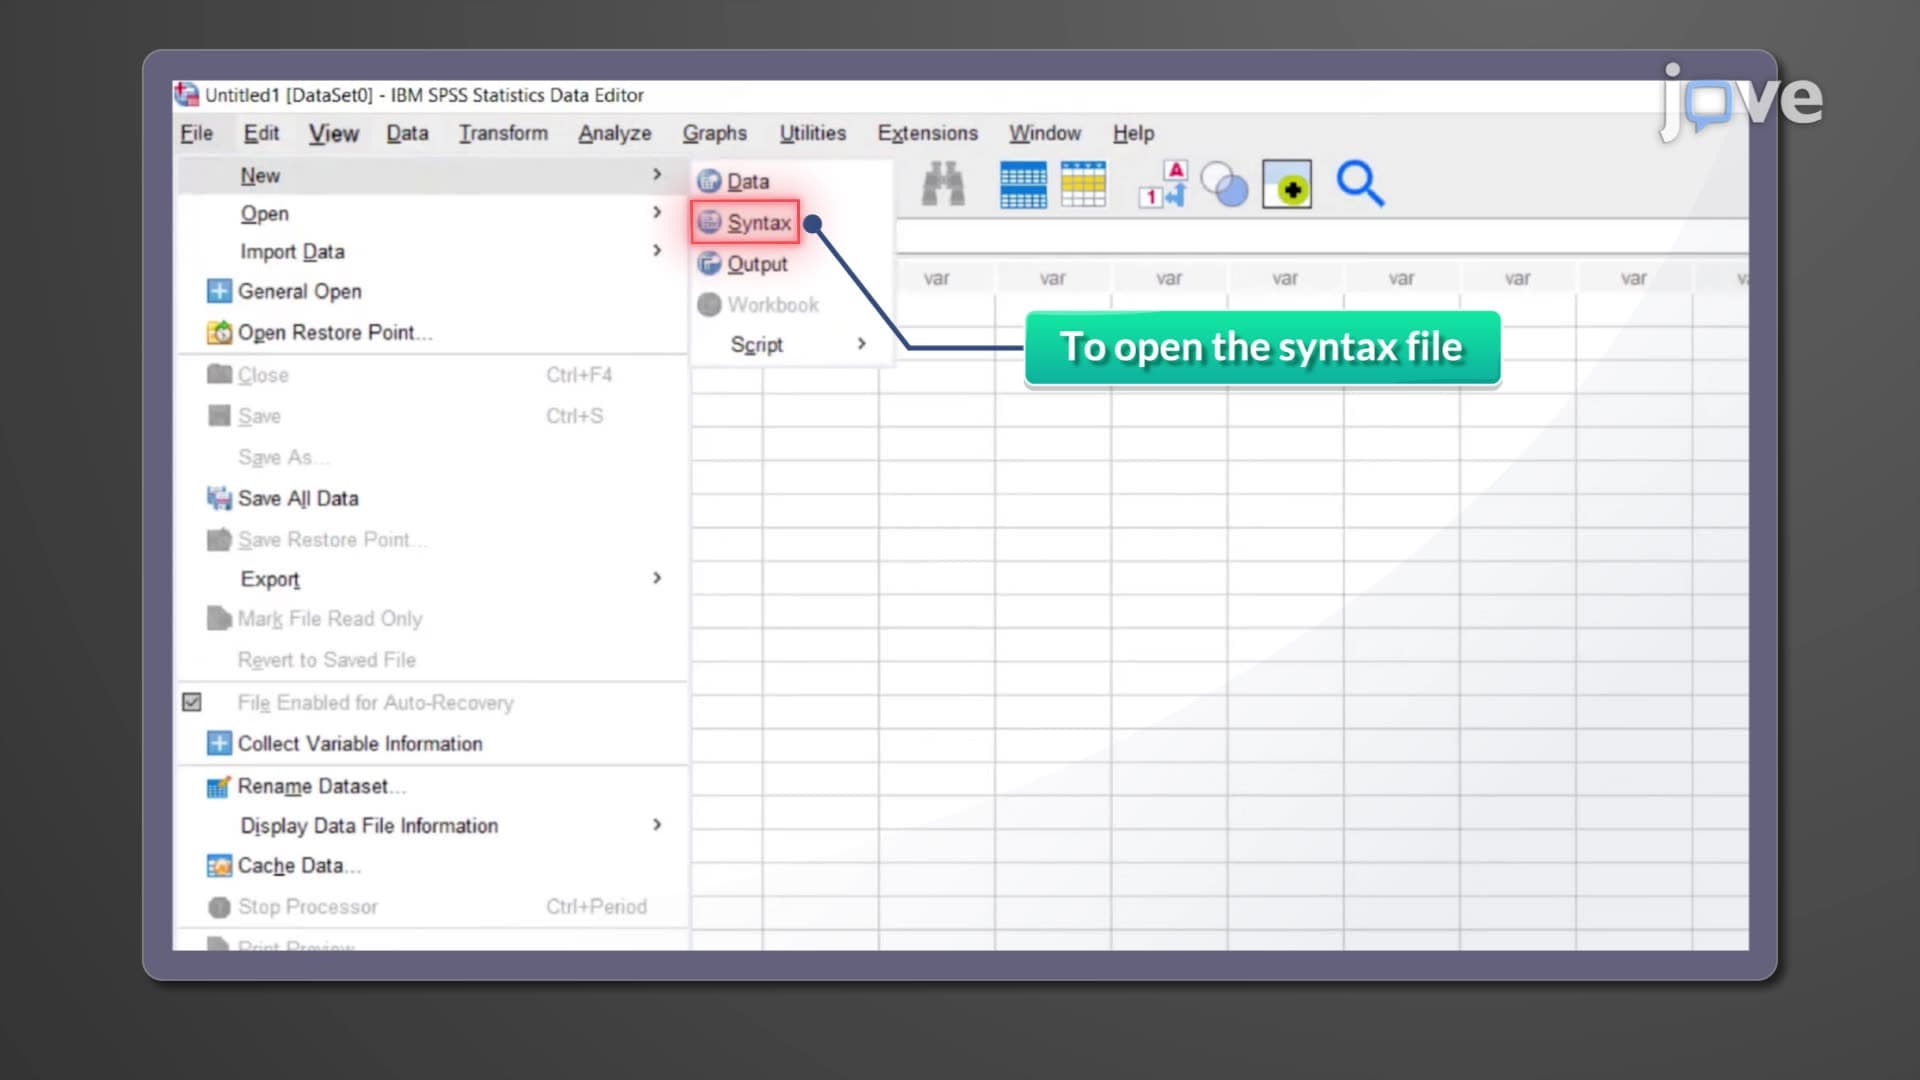
The Statistical Package for the Social Sciences, or SPSS, is a data management and analysis software suite. Developed by SPSS Inc. in 1968 and acquired by IBM in 2009, this tool was initially designed for social science data analysis, evolving to serve a wider range of disciplines. It was later renamed to Statistical Product and Service Solutions.
SPSS streamlines the process from data preparation to analysis and reporting. It is characterized by its user-friendly interface, which conceals...
SPSS streamlines the process from data preparation to analysis and reporting. It is characterized by its user-friendly interface, which conceals...
270
 01:25
Multiple Regression
2.9K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
2.9K
 01:03
Prediction Intervals
2.2K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.2K
 01:19
Variation
6.7K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.7K