
Earnings of college graduates, 1993
1Office of Employment Projections, Bureau of Labor Statistics, USA.
Monthly Labor Review
|November 4, 1995

Abstract
No abstract available in PubMed .
More Related Videos
 09:55
Bridging the Technology Divide in the COVID-19 Era: Using Virtual Outreach to Expose Middle and High School Students to Imaging Technology
Published on: September 28, 2022
 10:17
Improving Student Outcomes with an Adaptable Molecular Cloning Course-Based Undergraduate Research Experience
Published on: November 15, 2024
Related Concept Videos
 02:20
Correlations
Correlation means that there is a relationship between two or more variables (such as ice cream consumption and crime), but this relationship does not necessarily imply cause and effect. When two variables are correlated, it simply means that as one variable changes, so does the other. We can measure correlation by calculating a statistic known as a correlation coefficient. A correlation coefficient is a number from -1 to +1 that indicates the strength and direction of the relationship between...
 01:29
Reliability and Validity
Reliability and validity are two important considerations that must be made with any type of data collection. Reliability refers to the ability to consistently produce a given result. In the context of psychological research, this would mean that any instruments or tools used to collect data do so in consistent, reproducible ways.
 02:16
Measures of Central Tendency
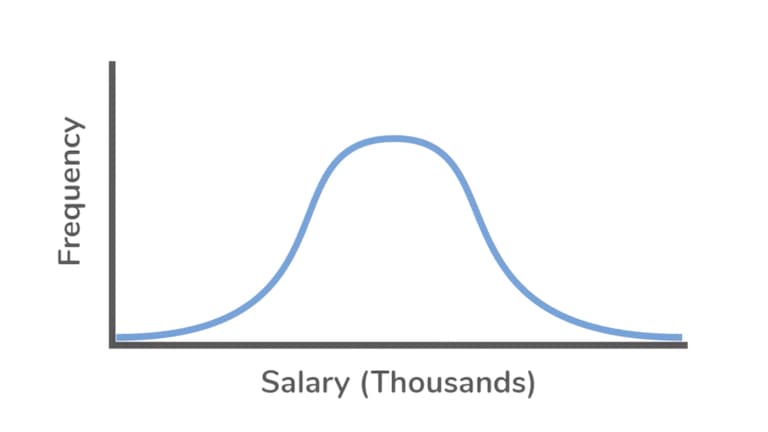
The "center" of a data set is also a way of describing location. The two most widely used measures of the "center" of the data are the mean (average) and the median. The words "mean" and "average" are often used interchangeably. The substitution of one word for the other is common practice. The technical term is "arithmetic mean" and "average" is technically a center location. However, in practice among non-statisticians, "average" is commonly accepted for "arithmetic mean."
 01:31
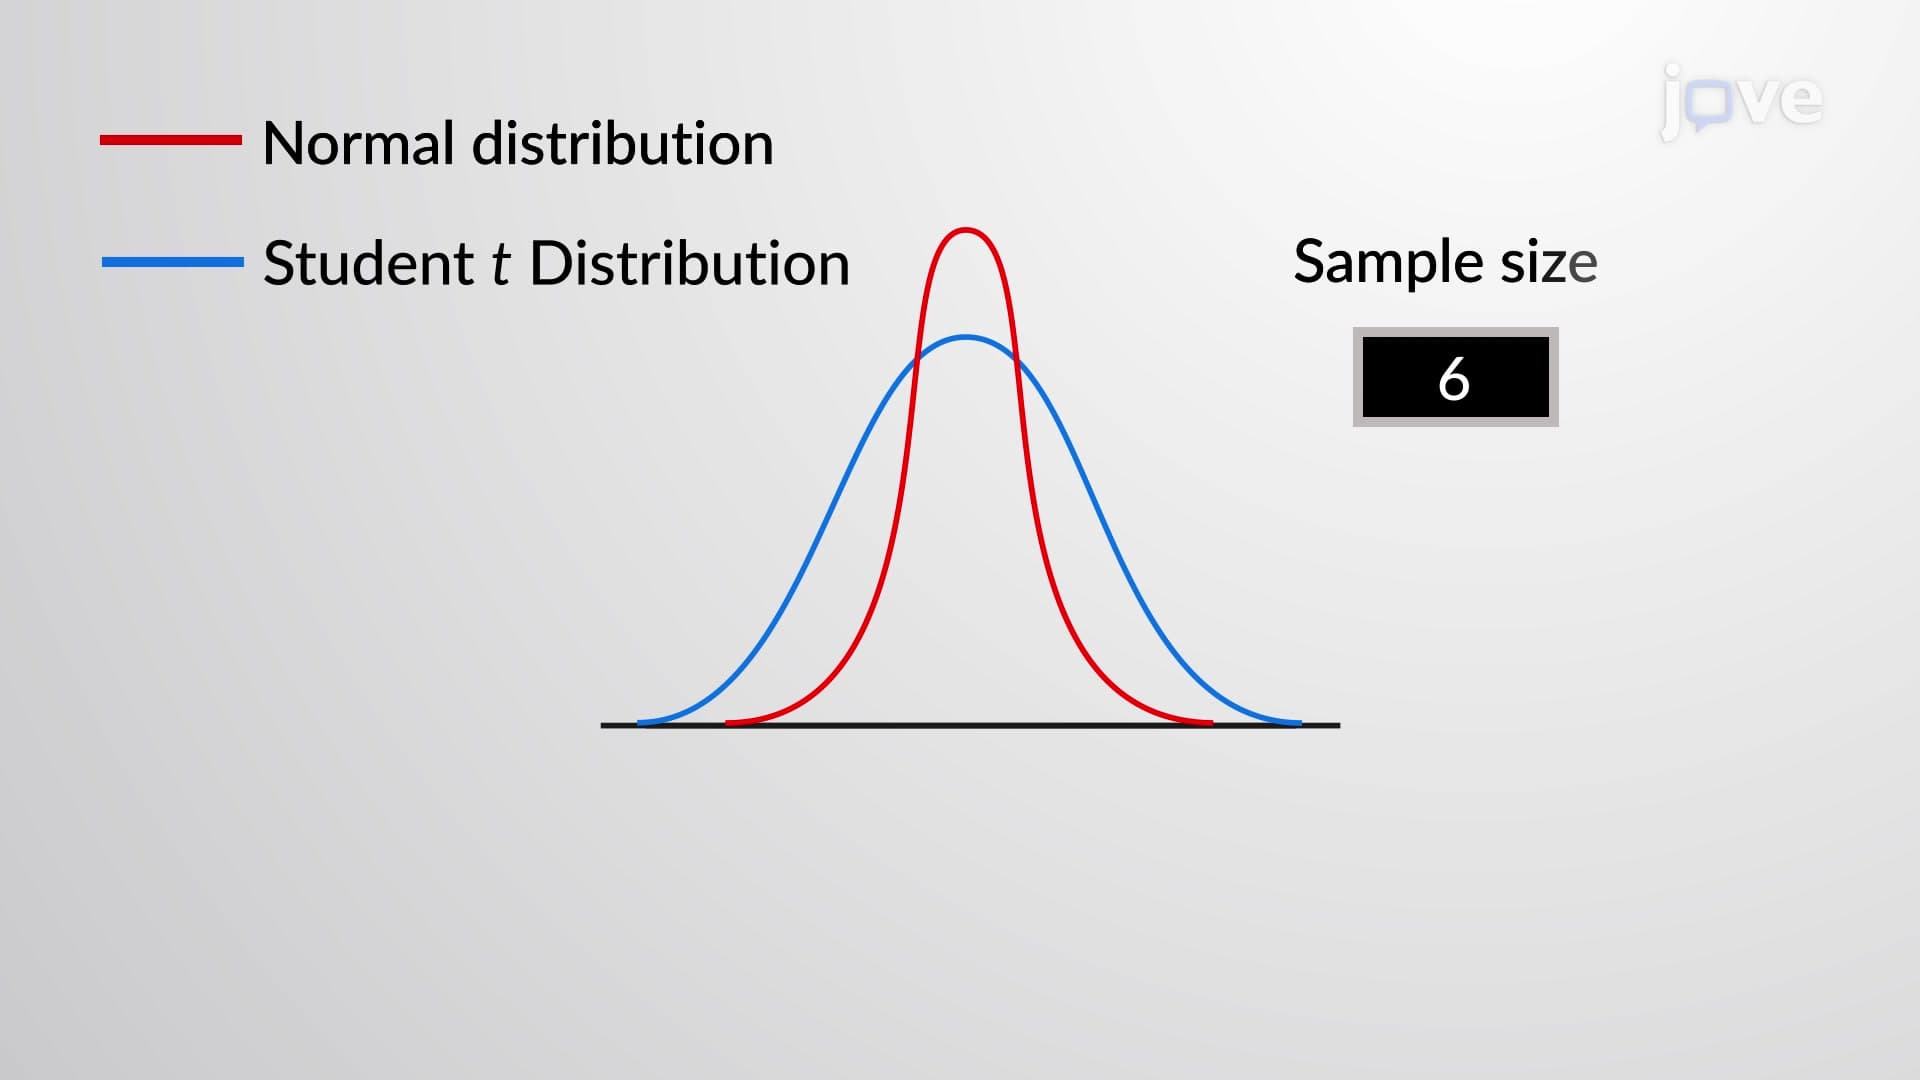
Student t Distribution
The population standard deviation is rarely known in many day-to-day examples of statistics. When the sample sizes are large, it is easy to estimate the population standard deviation using a confidence interval, which provides results close enough to the original value. However, statisticians ran into problems when the sample size was small. A small sample size caused inaccuracies in the confidence interval.
The Student t distribution was developed by William S. Goset (1876–1937) of the...
The Student t distribution was developed by William S. Goset (1876–1937) of the...
 01:08
Outliers and Influential Points
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the vertical...
 01:18
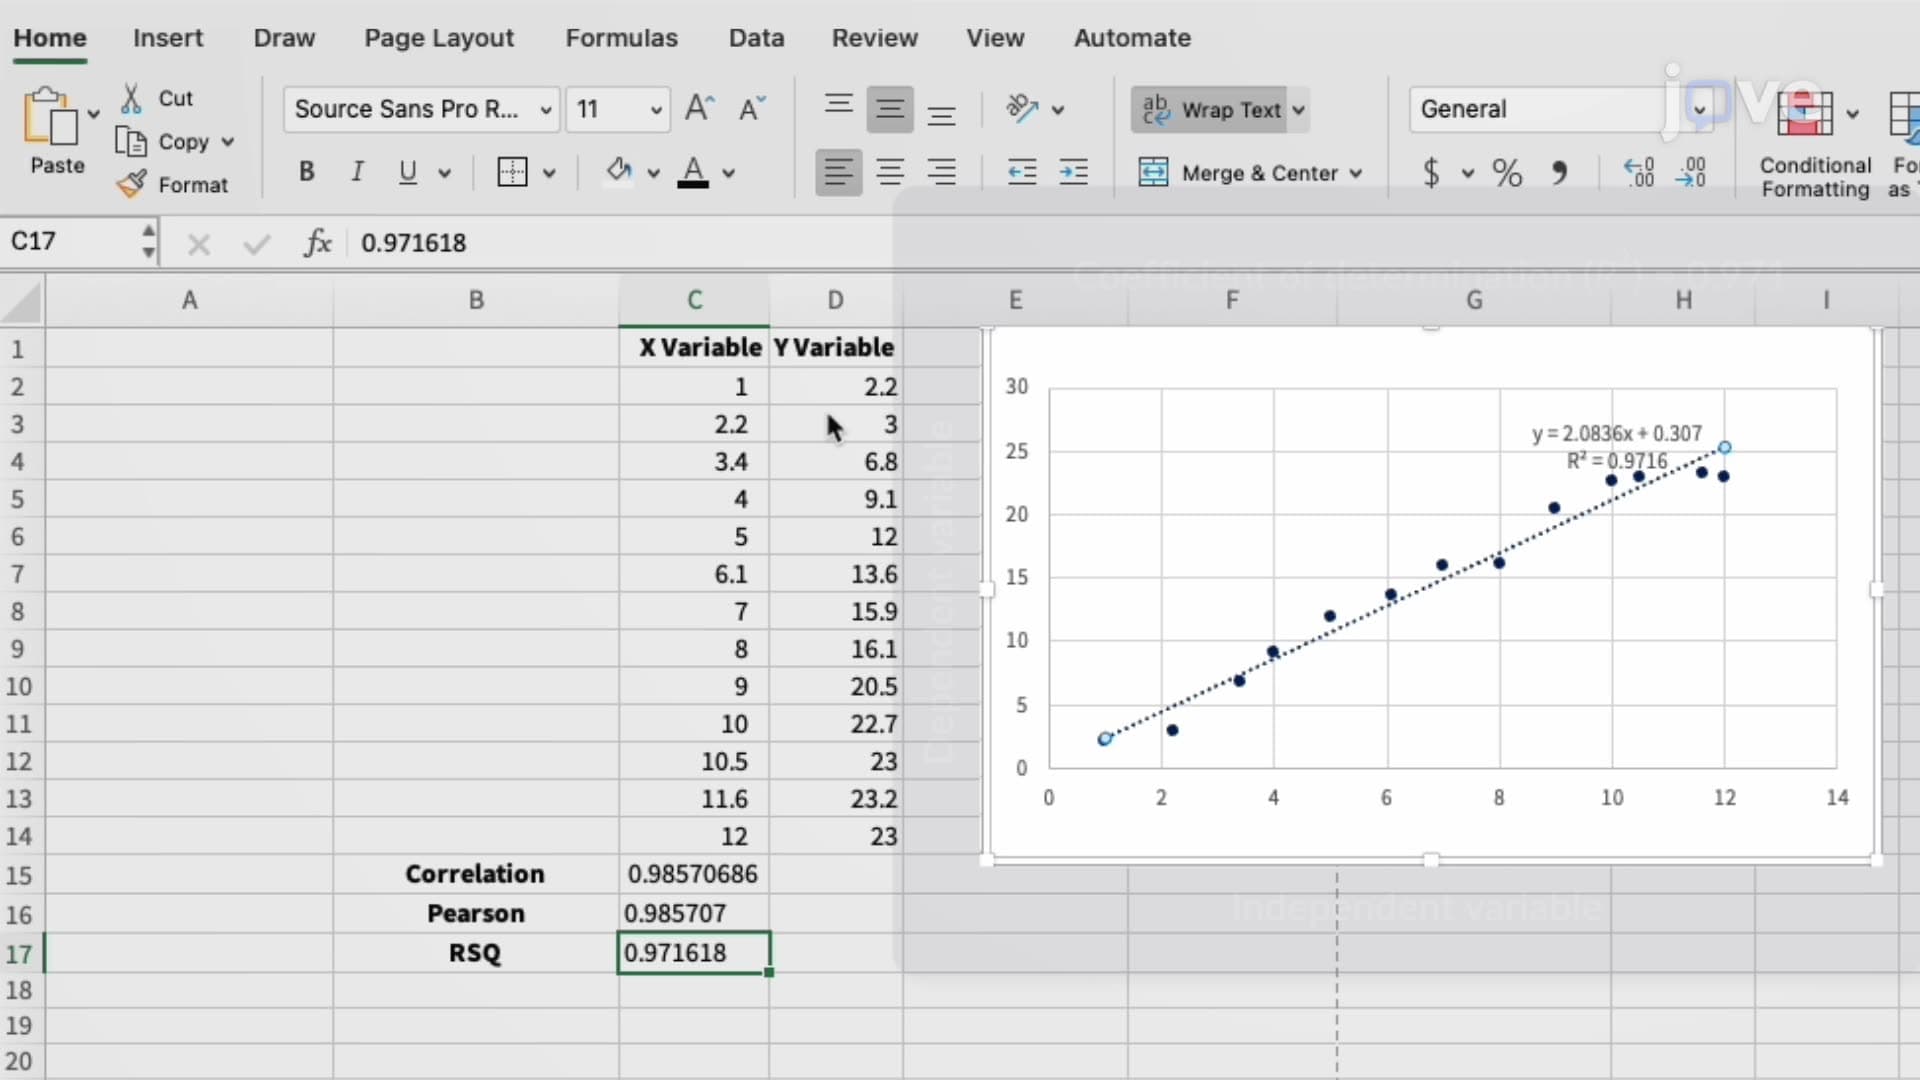
Microsoft Excel: Pearson's Correlation
Microsoft Excel is a powerful tool for statistical analysis, including calculating Pearson's correlation coefficient, which measures the strength and direction of a linear relationship between two continuous variables. Pearson's correlation coefficient, often denoted as "r," ranges from -1 to 1. A value close to 1 indicates a strong positive correlation, meaning as one variable increases, the other does too. A value close to -1 indicates a strong negative correlation, implying that as one...