Frequency of meaning use for ambiguous and unambiguous words
Related Experiment Video
Updated: Oct 19, 2026
Measuring the Subjective Value of Risky and Ambiguous Options using Experimental Economics and Functional MRI Methods
Published on: September 19, 2012
1University of Illinois at Urbana-Champaign, USA. griffin@psych.stanford.edu

Abstract:
When using verbal stimuli, researchers usually equate words on frequency of use. However, for some ambiguous words (e.g., ball as a round object or a formal dance), frequency counts fail to distinguish how often a particular meaning is used. This study evaluates the use of ratings to estimate meaning frequency. Analyses show that ratings correlate highly with word frequency counts when orthographic and meaning frequencies should converge, are not unduly influenced by semantic factors, and may provide a better measure of relative meaning dominance than the word association task does. Furthermore, the ratings allow researchers to equate or manipulate frequency of meaning use for ambiguous and unambiguous words. Ratings for 211 words are reported.
Related Concept Videos
 00:59
Uncertainty: Overview
 01:16
Unusual Results
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value = μ + 2σ
Minimum unusual value...
 01:08
Determination of Expected Frequency
 01:07
What is a Mode?
There can be more than one mode in a data set if multiple values have the same highest frequency. For instance, suppose that the Statistics exam scores of 20 students are: 50; 53; 59; 59; 63; 63; 72; 72; 72; 72; 72; 76; 78; 81; 83; 84; 84; 84; 90; 93. Here, the mode is 72, as it occurs most frequently, five times.
A data set with two modes is called bimodal. For example,...
 01:09
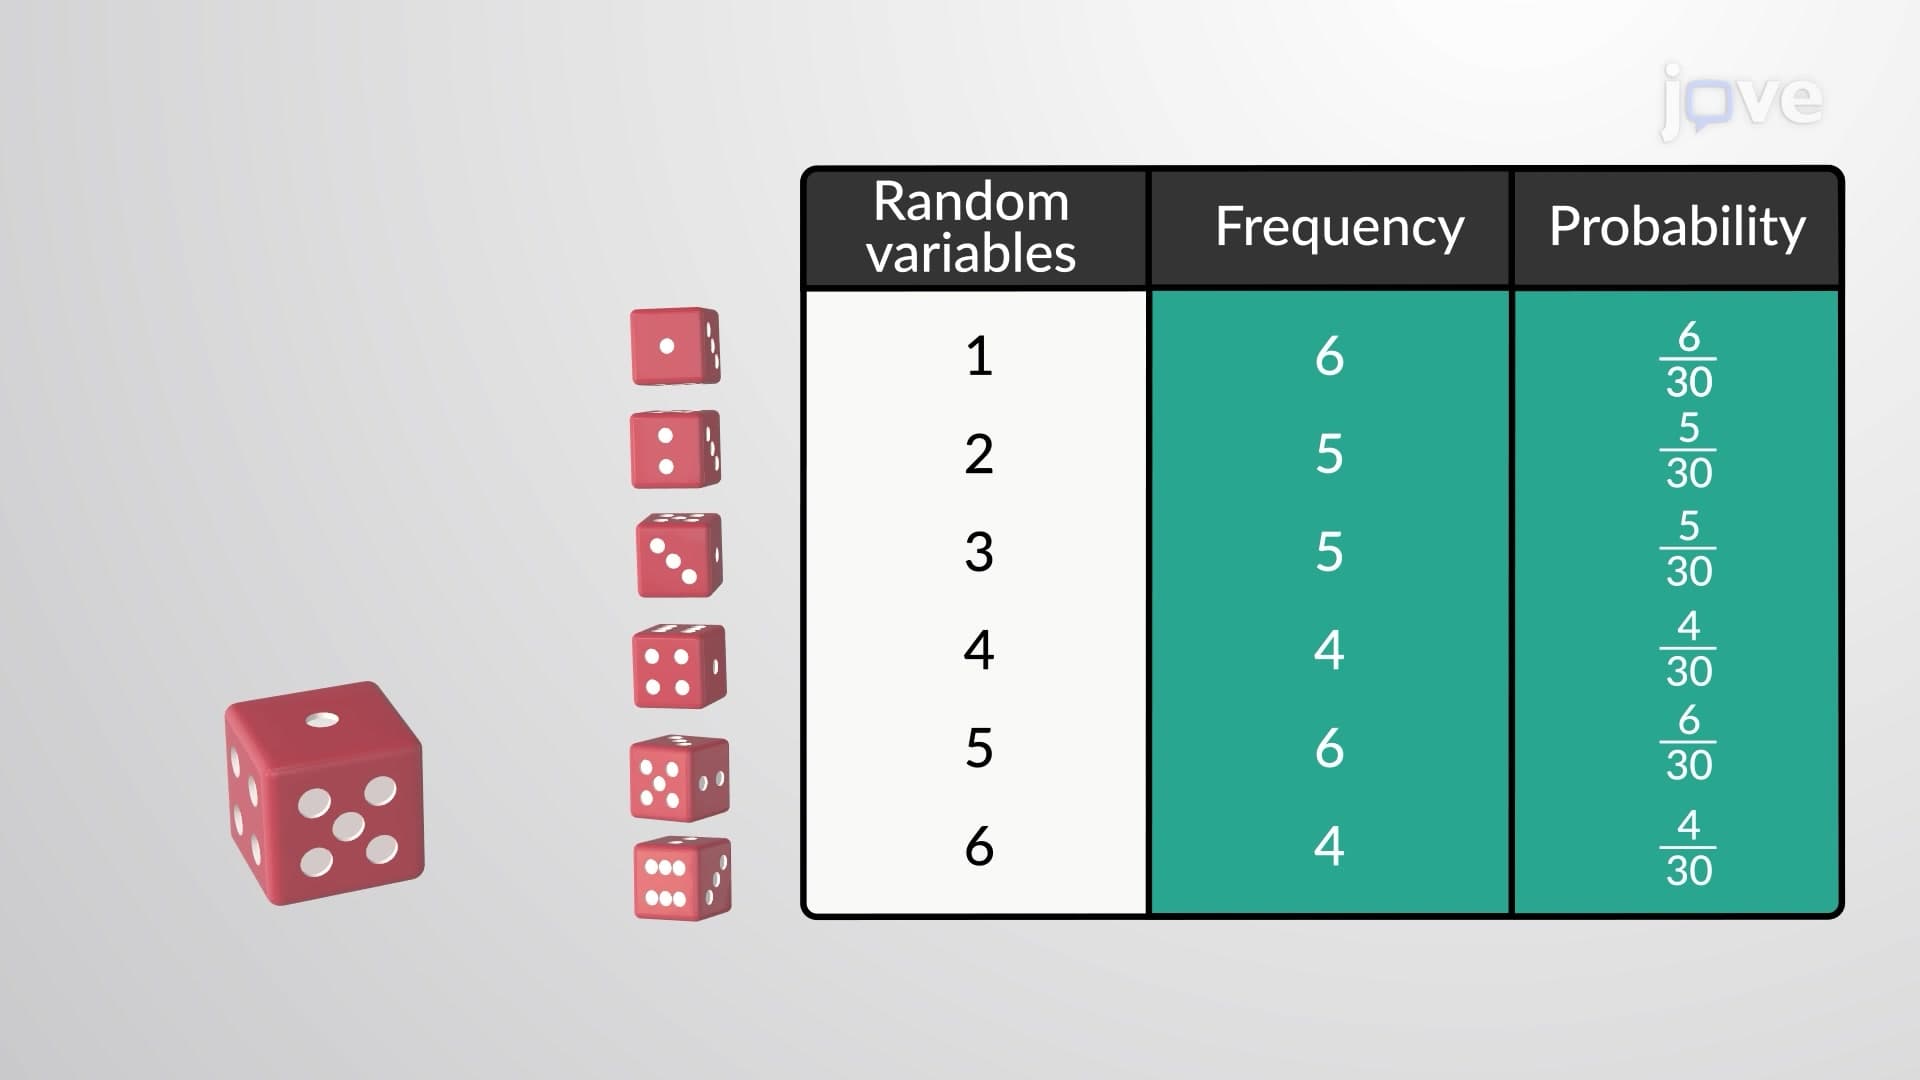
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 00:56
Nominal Level of Measurement
The data that cannot be measured but can be grouped into categories fall under the nominal level of measurement. Data that is measured using a nominal scale is...