Related Experiment Video
Updated: Aug 14, 2026


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Probability binning comparison: a metric for quantitating univariate distribution differences
M Roederer1, A Treister, W Moore
1Vaccine Research Center, NIH, Bethesda, Maryland 20892-3015, USA. Roederer@drmr.com

Background:
Comparing distributions of data is an important goal in many applications. For example, determining whether two samples (e.g., a control and test sample) are statistically significantly different is useful to detect a response, or to provide feedback regarding instrument stability by detecting when collected data varies significantly over time.
Methods:
We apply a variant of the chi-squared statistic to comparing univariate distributions. In this variant, a control distribution is divided such that an equal number of events fall into each of the divisions, or bins. This approach is thereby a mini-max algorithm, in that it minimizes the maximum expected variance for the control distribution. The control-derived bins are then applied to test sample distributions, and a normalized chi-squared value is computed. We term this algorithm Probability Binning.
Results:
Using a Monte-Carlo simulation, we determined the distribution of chi-squared values obtained by comparing sets of events derived from the same distribution. Based on this distribution, we derive a conversion of any given chi-squared value into a metric that is analogous to a t-score, i.e., it can be used to estimate the probability that a test distribution is different from a control distribution. We demonstrate that this metric scales with the difference between two distributions, and can be used to rank samples according to similarity to a control. Finally, we demonstrate the applicability of this metric to ranking immunophenotyping distributions to suggest that it indeed can be used to objectively determine the relative distance of distributions compared to a single control.
Conclusion:
Probability Binning, as shown here, provides a useful metric for determining the probability that two or more flow cytometric data distributions are different. This metric can also be used to rank distributions to identify which are most similar or dissimilar. In addition, the algorithm can be used to quantitate contamination of even highly-overlapping populations. Finally, as demonstrated in an accompanying paper, Probability Binning can be used to gate on events that represent significantly different subsets from a control sample. Published 2001 Wiley-Liss, Inc.

Related Concept Videos
 01:05
Histogram
A histogram graph consists of contiguous (adjoining) boxes. The heights of the bars correspond to frequency values. The graph will have the same shape with respective labels. The...
 01:17
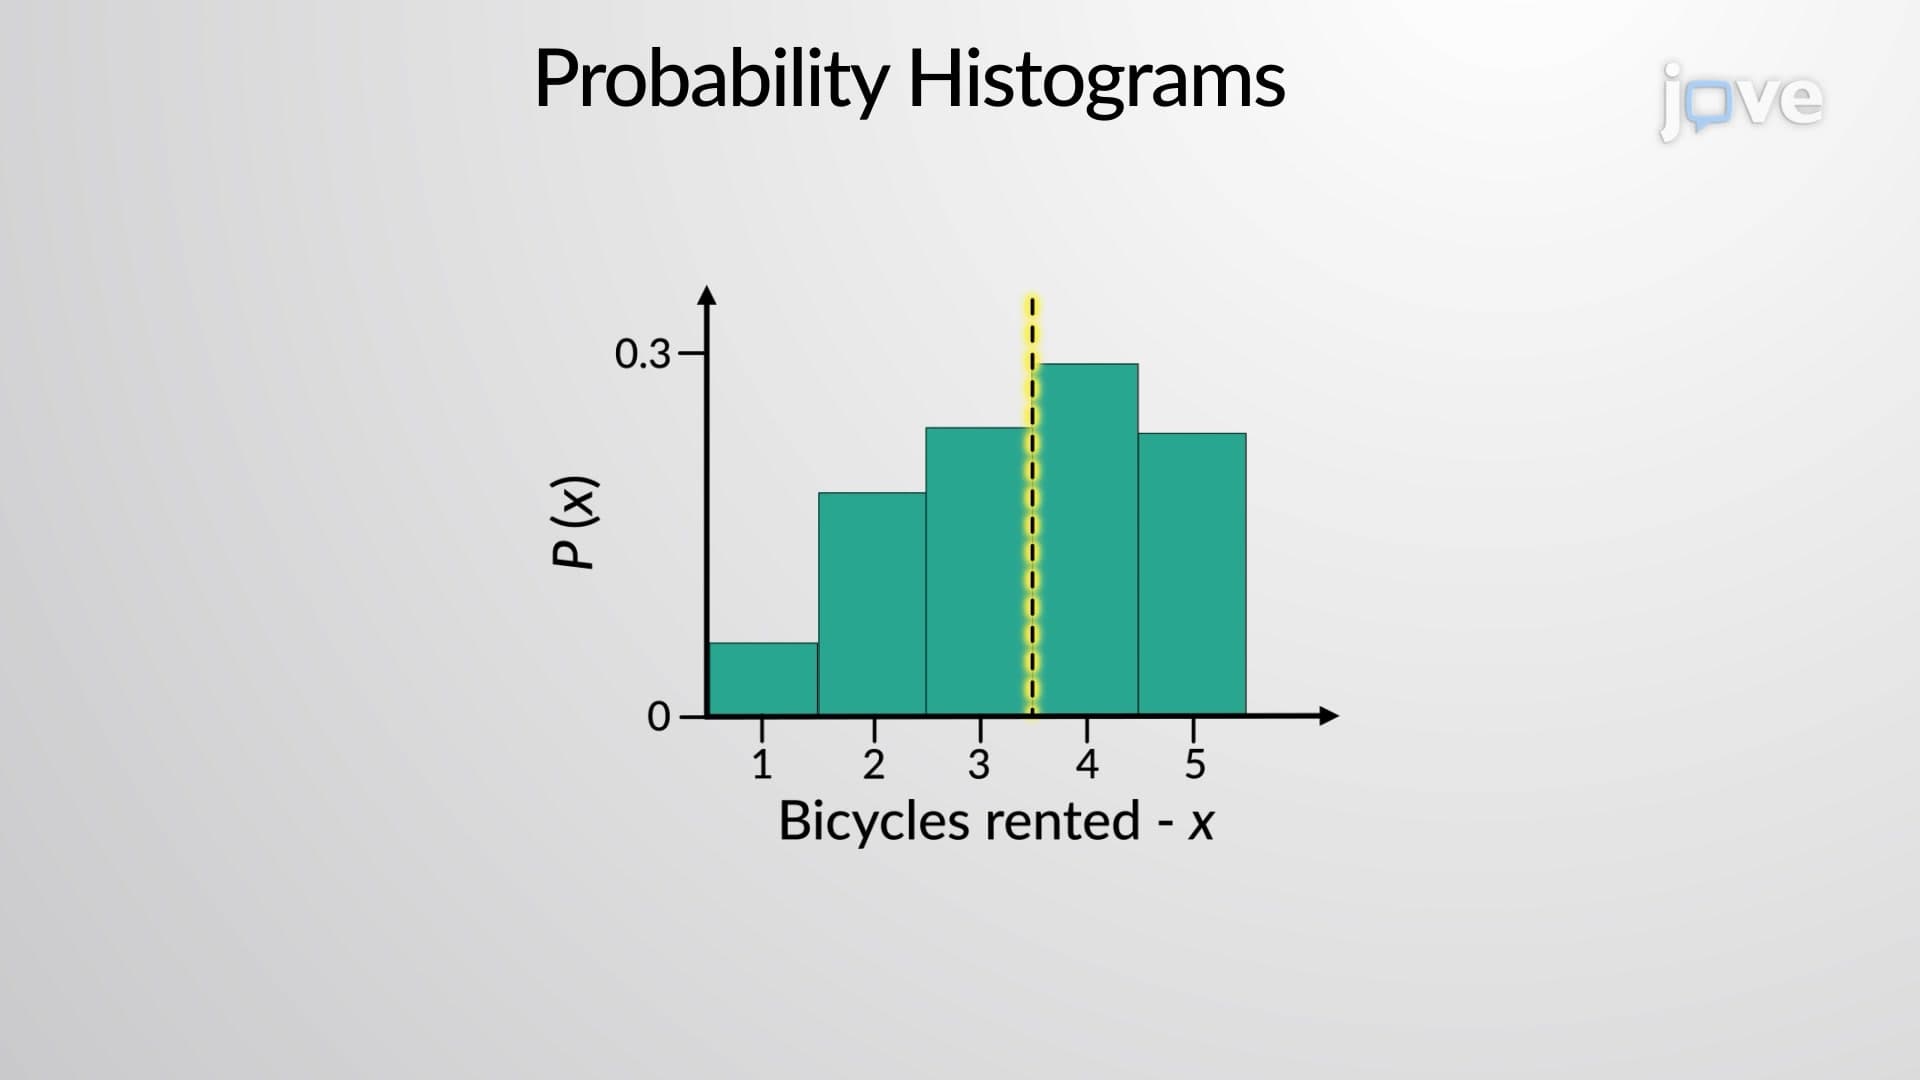
Probability Histograms
 01:15
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:10
Bonferroni Test
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 00:57
Behrens–Fisher Test
This test is...