Related Experiment Video
Updated: Aug 21, 2026

Using the Race Model Inequality to Quantify Behavioral Multisensory Integration Effects
Published on: May 10, 2019
Statistical modelling of the differences between successive R-R intervals
Sumithra J Mandrekar1, Haikady N Nagaraja, Gary G Berntson
1The Ohio State University, Columbus, OH 43210, USA. mandrekar.sumithra@mayo.edu

Abstract:
Understanding the behaviour of R-R interval data and its successive differences is critical to the dynamics of cardiac control. Several time domain measures that quantify R-R interval variability have important clinical significance in terms of risk stratification and evaluating the effectiveness of treatment procedures. The present approach at examining the distributions of successive beat-to-beat differences of R-R interval data from different populations and under different conditions (baseline and reaction times) provides a valuable insight into their previously unexplored distributional properties. In particular, our analysis reveals that the successive differences have non-normal statistical distributions (a contradiction to the commonly used assumption of normality), and the absolute successive R-R interval differences approximately follows a Weibull distribution. As an illustration of the utility of this approach, we explore the statistical properties of the time domain measure: root mean square successive difference, study the association between the Weibull scale parameter estimate and respiratory sinus arrhythmia, and propose improvements in artifact detection algorithms.
Related Concept Videos
 01:22
Interpreting R Charts
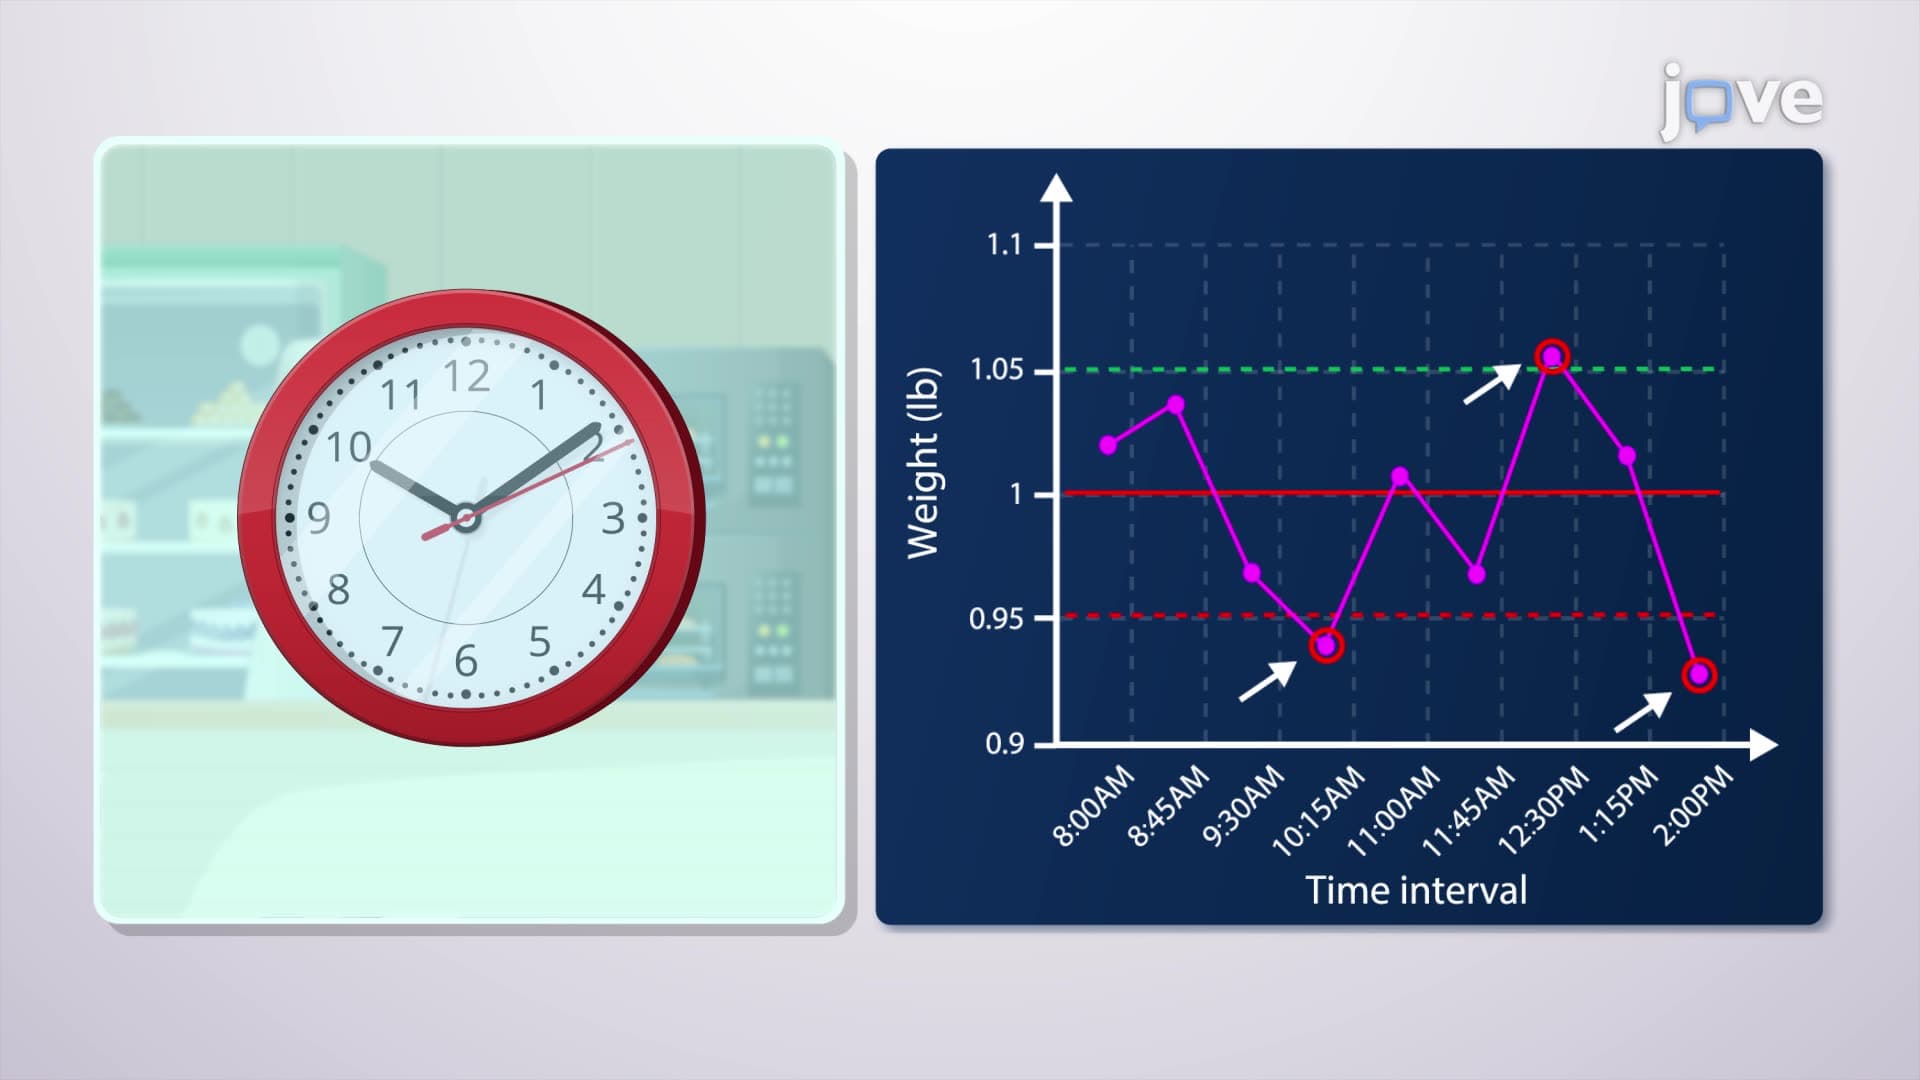
An R chart plots the range of subsets of measurements collected from a process. Each point on the chart represents the range—defined as the difference between the maximum and minimum values—of a sample...
 01:02
The R Chart
R charts are pivotal for pinpointing shifts in process variability. Stability is indicated when all data points remain within the defined upper and lower...
 01:52
Regression Toward the Mean
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:14
Identifying Statistically Significant Differences: The F-Test
 01:19
Variation
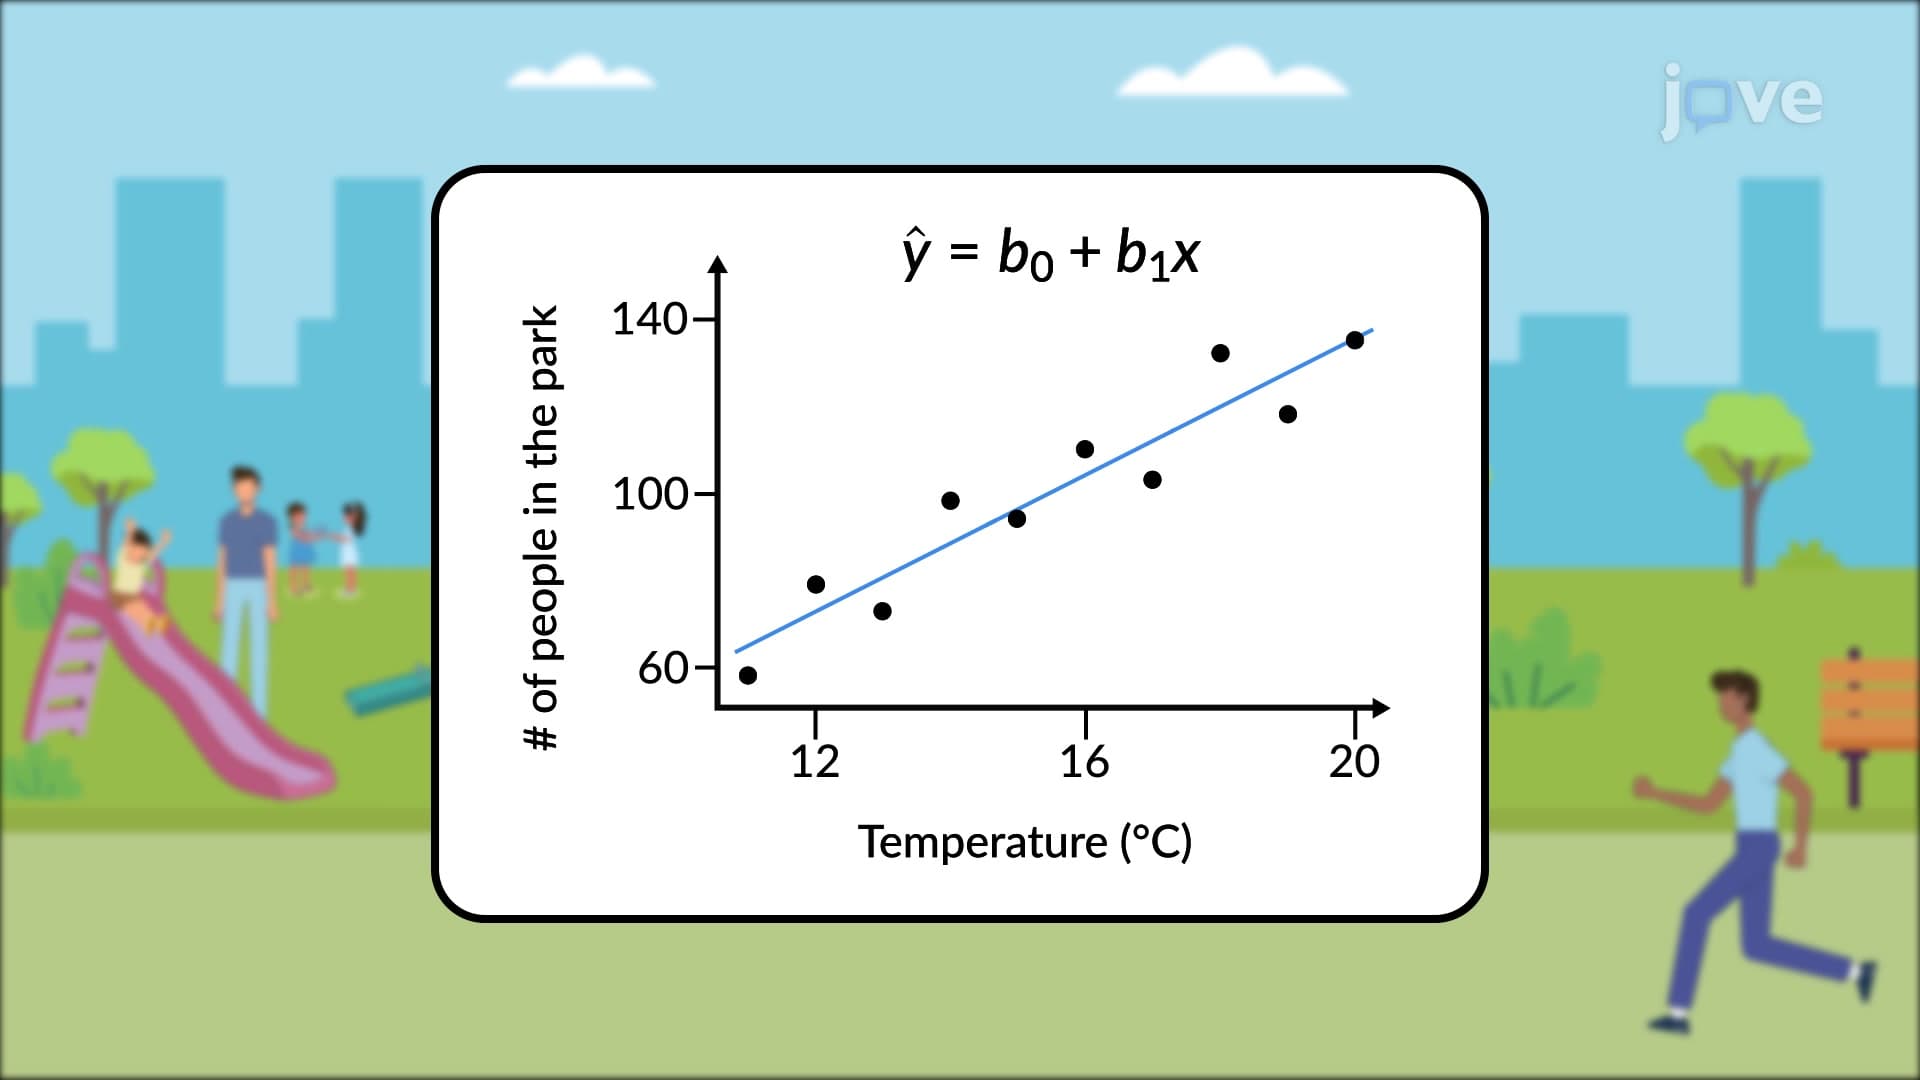
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...