Identification of hot regions in protein-protein interactions by sequential pattern mining
Related Experiment Video
Updated: Jul 14, 2026
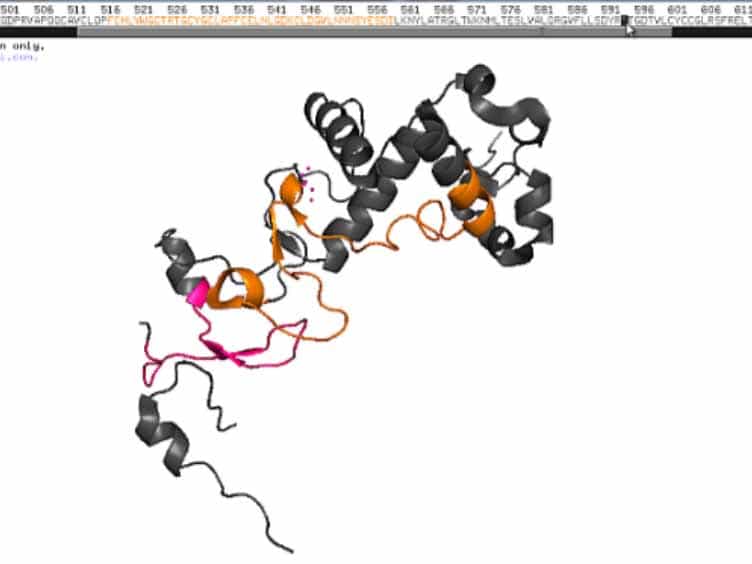
Identifying Protein-protein Interaction Sites Using Peptide Arrays
Published on: November 18, 2014
Chen-Ming Hsu1, Chien-Yu Chen, Baw-Jhiune Liu
1Department of Computer Science and Engineering, Yuan Ze University, Chung-Li, Taiwan, ROC. cmhsu@saturn.yzu.edu.tw

Background:
Identification of protein interacting sites is an important task in computational molecular biology. As more and more protein sequences are deposited without available structural information, it is strongly desirable to predict protein binding regions by their sequences alone. This paper presents a pattern mining approach to tackle this problem. It is observed that a functional region of protein structures usually consists of several peptide segments linked with large wildcard regions. Thus, the proposed mining technology considers large irregular gaps when growing patterns, in order to find the residues that are simultaneously conserved but largely separated on the sequences. A derived pattern is called a cluster-like pattern since the discovered conserved residues are always grouped into several blocks, which each corresponds to a local conserved region on the protein sequence.
Results:
The experiments conducted in this work demonstrate that the derived long patterns automatically discover the important residues that form one or several hot regions of protein-protein interactions. The methodology is evaluated by conducting experiments on the web server MAGIIC-PRO based on a well known benchmark containing 220 protein chains from 72 distinct complexes. Among the tested 218 proteins, there are 900 sequential blocks discovered, 4.25 blocks per protein chain on average. About 92% of the derived blocks are observed to be clustered in space with at least one of the other blocks, and about 66% of the blocks are found to be near the interface of protein-protein interactions. It is summarized that for about 83% of the tested proteins, at least two interacting blocks can be discovered by this approach.
Conclusion:
This work aims to demonstrate that the important residues associated with the interface of protein-protein interactions may be automatically discovered by sequential pattern mining. The detected regions possess high conservation and thus are considered as the computational hot regions. This information would be useful to characterizing protein sequences, predicting protein function, finding potential partners, and facilitating protein docking for drug discovery.
More Related Videos

Related Concept Videos
 02:04
Protein-protein Interfaces
02:04Protein-Protein Interfaces
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
02:26Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 01:24
Protein Organization
The primary structure of a protein is its amino acid sequence.