Bayesian k-Means as a "maximization-expectation" algorithm
Related Experiment Video
Updated: Jun 25, 2026

A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
Kenichi Kurihara1, Max Welling
1Department of Computer Science, Tokyo Institute of Technology, Meguro-ku, Tokyo 152-8552, Japan. kurihara@mi.cs.titech.ac.jp

Abstract:
We introduce a new class of "maximization-expectation" (ME) algorithms where we maximize over hidden variables but marginalize over random parameters. This reverses the roles of expectation and maximization in the classical expectation-maximization algorithm. In the context of clustering, we argue that these hard assignments open the door to very fast implementations based on data structures such as kd-trees and conga lines. The marginalization over parameters ensures that we retain the ability to infer model structure (i.e., number of clusters). As an important example, we discuss a top-down Bayesian k-means algorithm and a bottom-up agglomerative clustering algorithm. In experiments, we compare these algorithms against a number of alternative algorithms that have recently appeared in the literature.
Related Concept Videos
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:15
Expected Value
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 00:56
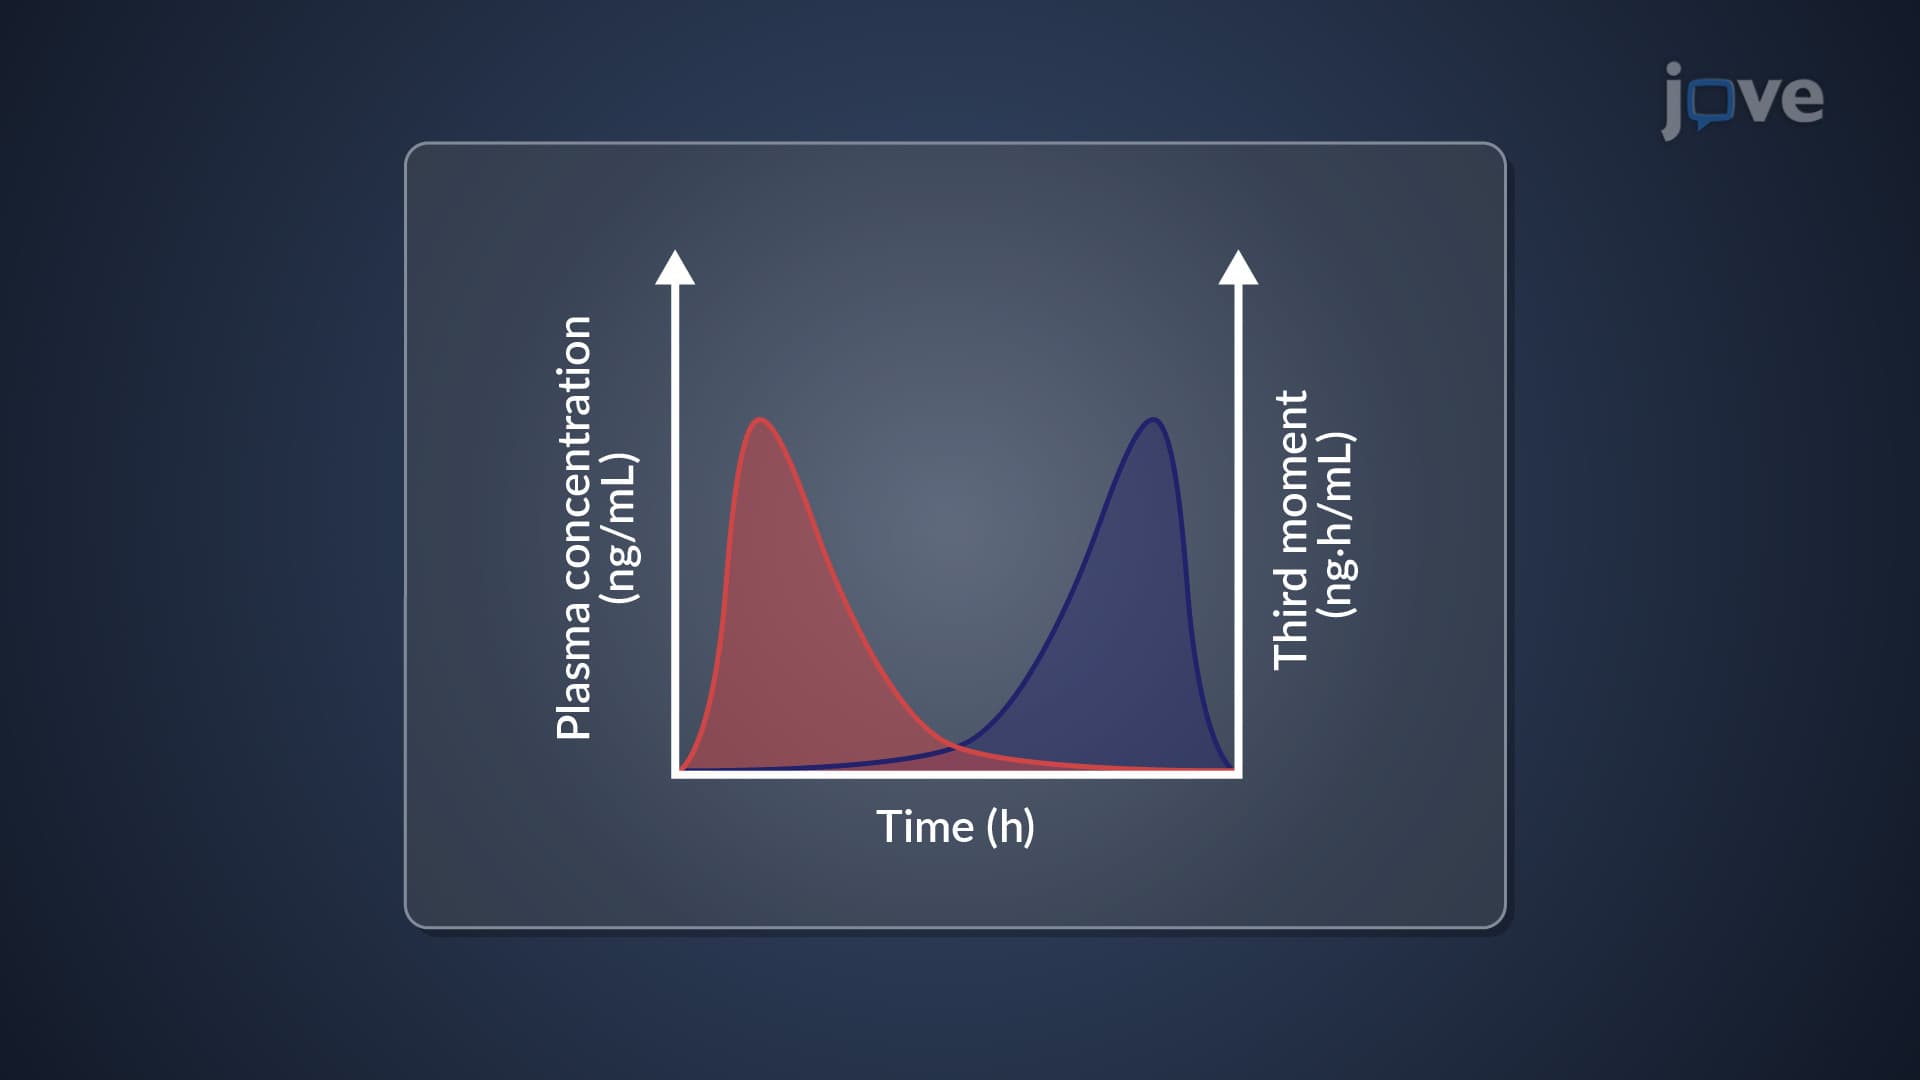
Noncompartmental Analysis: Statistical Moment Theory
 01:15
Chebyshev's Theorem to Interpret Standard Deviation
 01:20
Maxwell-Boltzmann Distribution: Problem Solving
This distribution function f(v) is defined by saying that the expected number N (v1,v2) of particles with speeds between v1 and v2 is given by