A conditional entropy minimization criterion for dimensionality reduction and multiple kernel learning
Related Experiment Videos
1hideitsu.hino@toki.waseda.jp

Abstract:
Reducing the dimensionality of high-dimensional data without losing its essential information is an important task in information processing. When class labels of training data are available, Fisher discriminant analysis (FDA) has been widely used. However, the optimality of FDA is guaranteed only in a very restricted ideal circumstance, and it is often observed that FDA does not provide a good classification surface for many real problems. This letter treats the problem of supervised dimensionality reduction from the viewpoint of information theory and proposes a framework of dimensionality reduction based on class-conditional entropy minimization. The proposed linear dimensionality-reduction technique is validated both theoretically and experimentally. Then, through kernel Fisher discriminant analysis (KFDA), the multiple kernel learning problem is treated in the proposed framework, and a novel algorithm, which iteratively optimizes the parameters of the classification function and kernel combination coefficients, is proposed. The algorithm is experimentally shown to be comparable to or outperforms KFDA for large-scale benchmark data sets, and comparable to other multiple kernel learning techniques on the yeast protein function annotation task.
Related Concept Videos
 01:19
Routh-Hurwitz Criterion II
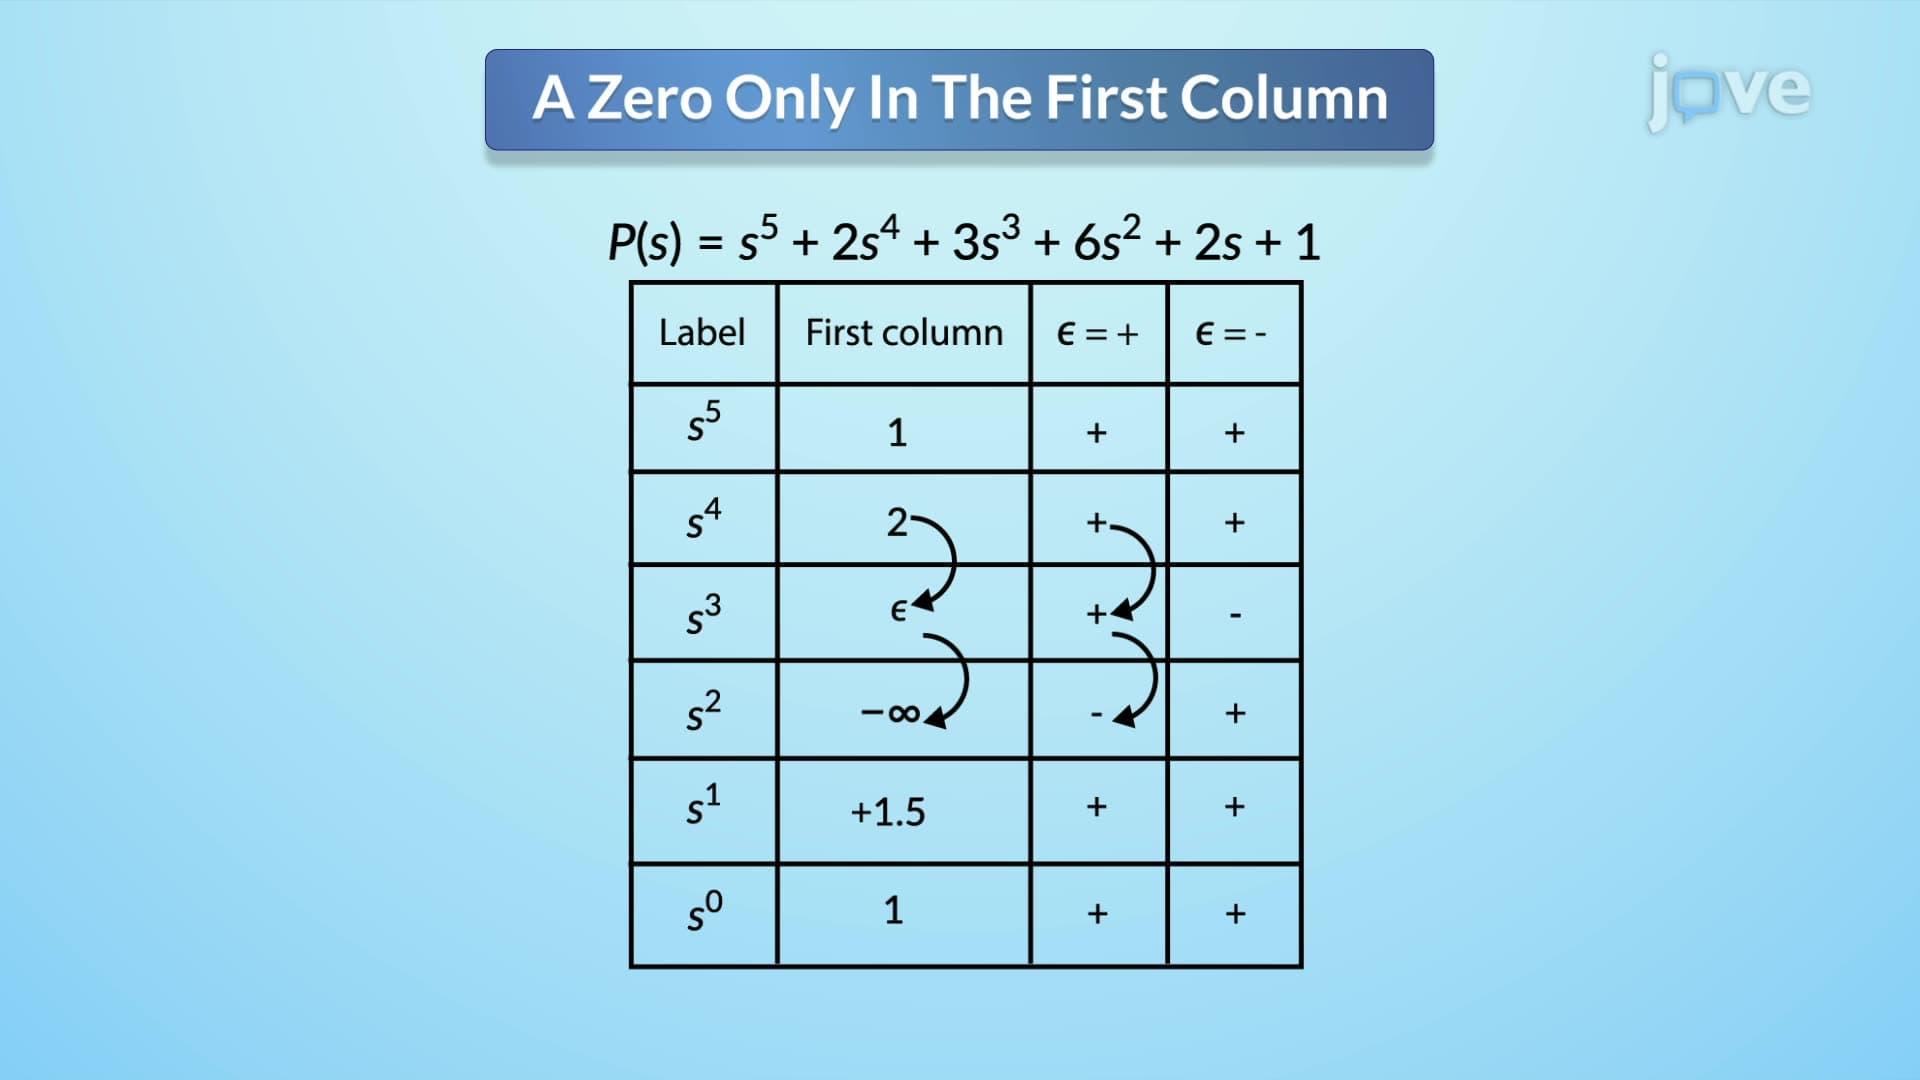
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first column of the Routh...
 01:15
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...
 01:28
Lagrange Multipliers: Two Constraints
 01:31
Local Maximum and Minimum Values
 01:15
Chebyshev's Theorem to Interpret Standard Deviation
 01:25
Maximizing the Directional Derivative