Improving protein secondary structure prediction based on short subsequences with local structure similarity
Related Experiment Video
Updated: Jan 31, 2026
Structure Solution of the Fluorescent Protein Cerulean Using MeshAndCollect
Published on: March 19, 2019
Hsin-Nan Lin1, Ting-Yi Sung, Shinn-Ying Ho
1Bioinformatics Program, Taiwan International Graduate Program, Academia Sinica, Taipei, Taiwan.

Background:
When characterizing the structural topology of proteins, protein secondary structure (PSS) plays an important role in analyzing and modeling protein structures because it represents the local conformation of amino acids into regular structures. Although PSS prediction has been studied for decades, the prediction accuracy reaches a bottleneck at around 80%, and further improvement is very difficult.
Results:
In this paper, we present an improved dictionary-based PSS prediction method called SymPred, and a meta-predictor called SymPsiPred. We adopt the concept behind natural language processing techniques and propose synonymous words to capture local sequence similarities in a group of similar proteins. A synonymous word is an n-gram pattern of amino acids that reflects the sequence variation in a protein's evolution. We generate a protein-dependent synonymous dictionary from a set of protein sequences for PSS prediction.On a large non-redundant dataset of 8,297 protein chains (DsspNr-25), the average Q3 of SymPred and SymPsiPred are 81.0% and 83.9% respectively. On the two latest independent test sets (EVA Set_1 and EVA_Set2), the average Q3 of SymPred is 78.8% and 79.2% respectively. SymPred outperforms other existing methods by 1.4% to 5.4%. We study two factors that may affect the performance of SymPred and find that it is very sensitive to the number of proteins of both known and unknown structures. This finding implies that SymPred and SymPsiPred have the potential to achieve higher accuracy as the number of protein sequences in the NCBInr and PDB databases increases.
Conclusions:
Our experiment results show that local similarities in protein sequences typically exhibit conserved structures, which can be used to improve the accuracy of secondary structure prediction. For the application of synonymous words, we demonstrate an example of a sequence alignment which is generated by the distribution of shared synonymous words of a pair of protein sequences. We can align the two sequences nearly perfectly which are very dissimilar at the sequence level but very similar at the structural level. The SymPred and SymPsiPred prediction servers are available at http://bio-cluster.iis.sinica.edu.tw/SymPred/.

Related Concept Videos
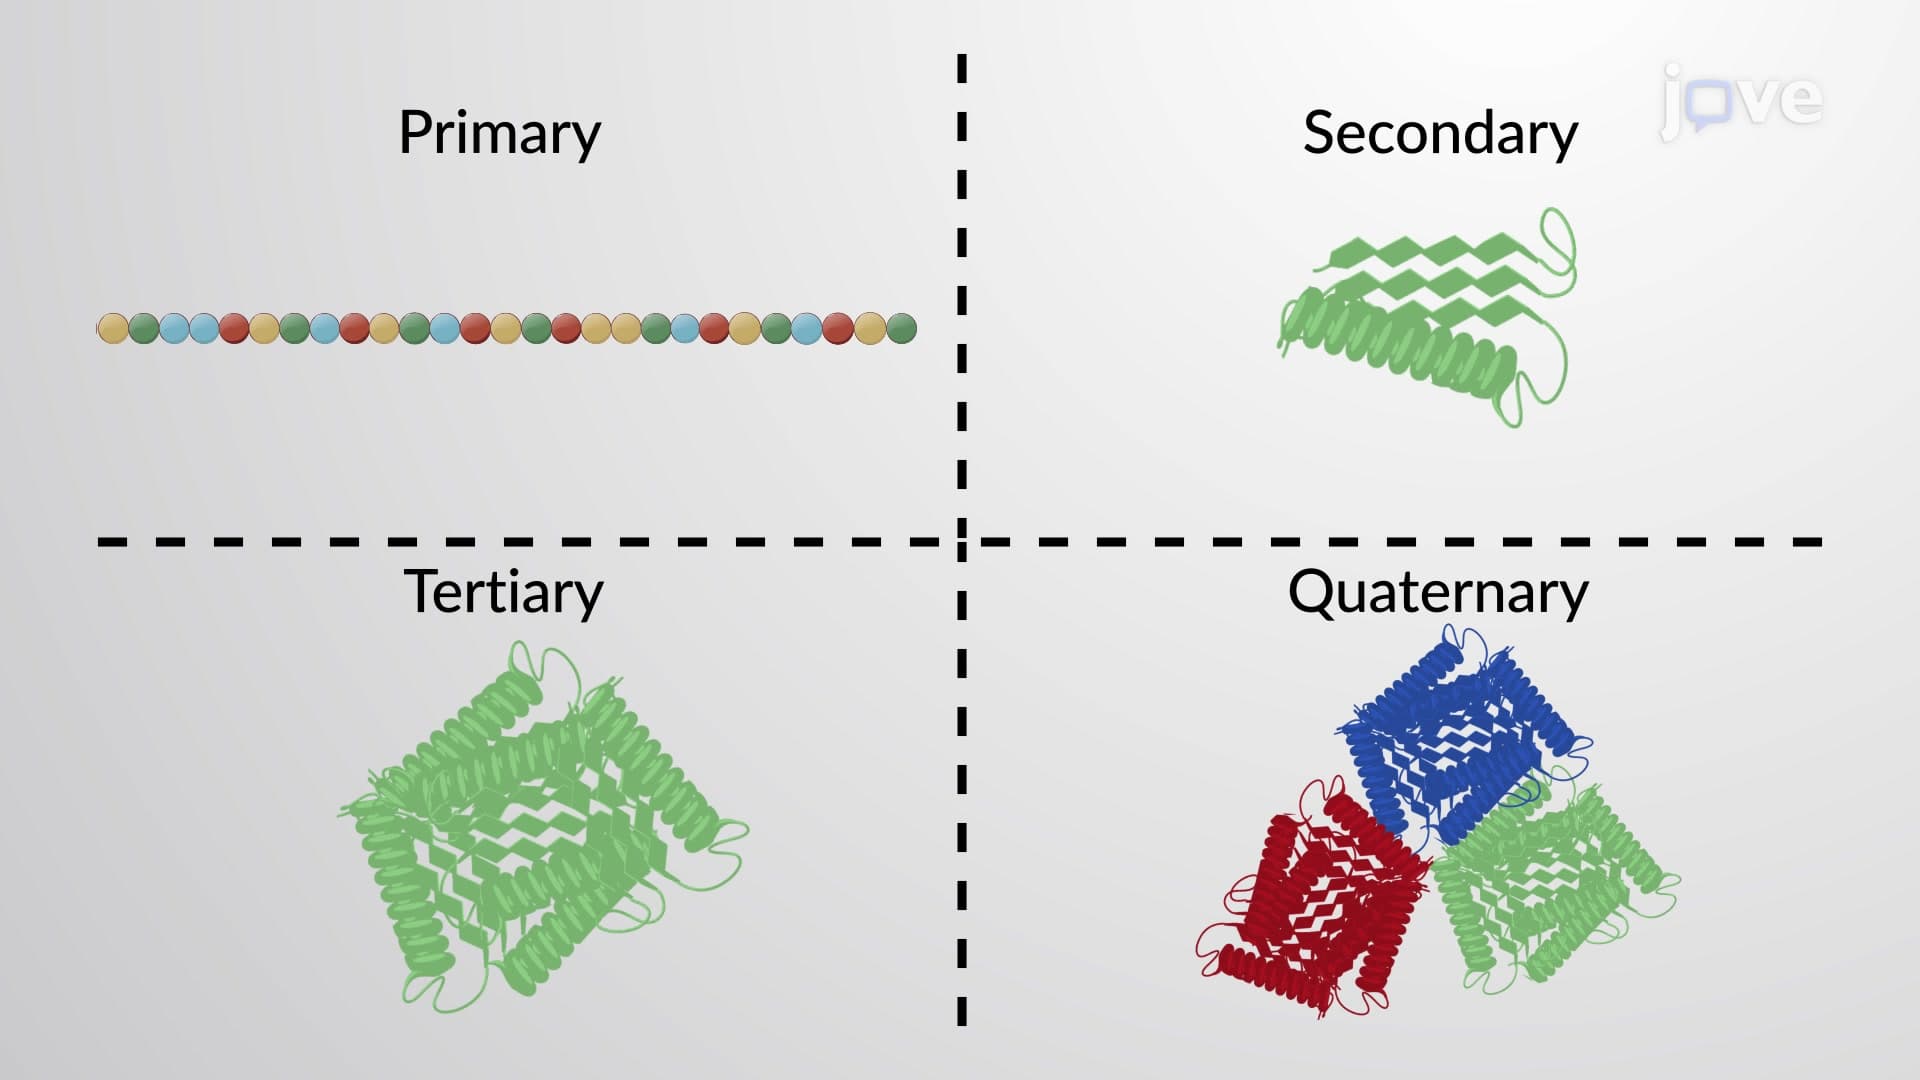 02:15
Protein and Protein Structure
A protein's shape is critical to its function. For example, an enzyme...
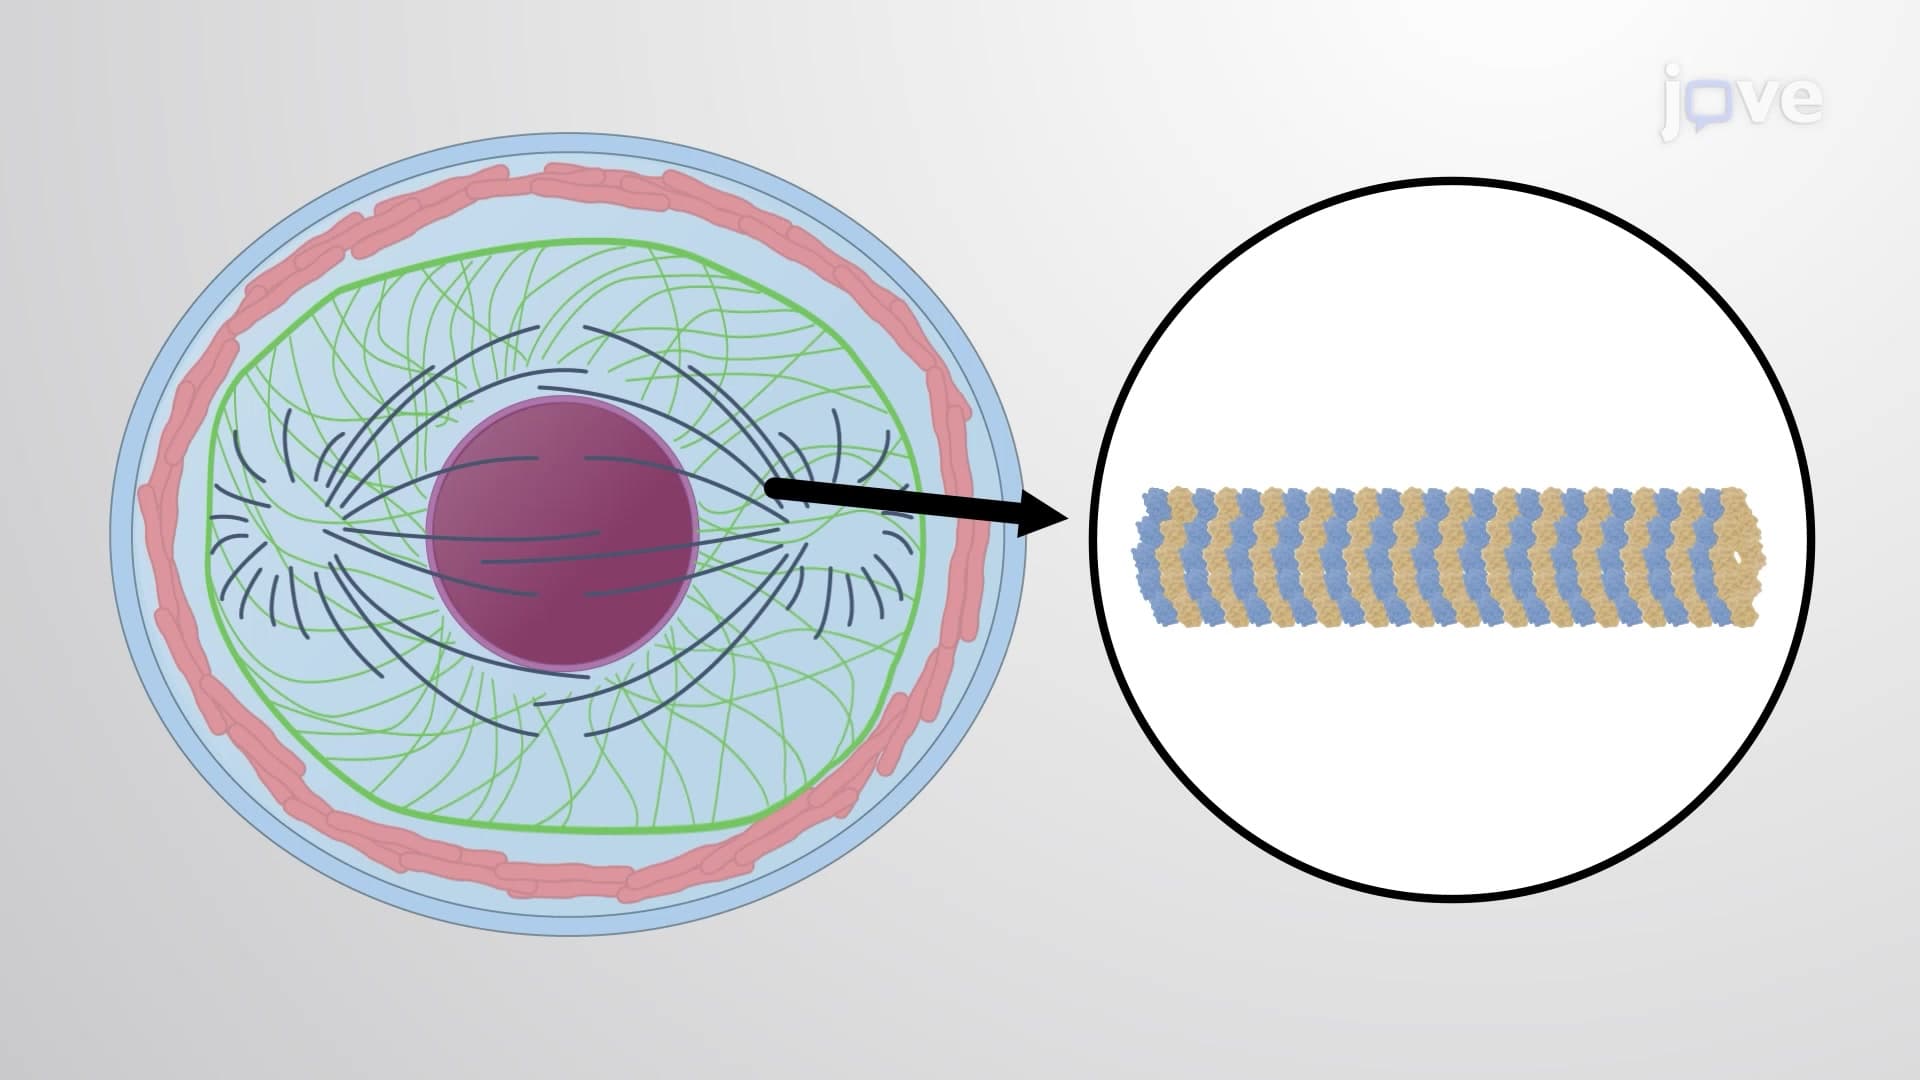 01:56
Structural Protein Function
Collagen, the most abundant protein in mammals, is found throughout the body. In connective tissue, such as skin, ligaments, and tendons, it provides tensile strength and elasticity. In bones and teeth, it mineralizes to...
01:56Structural Protein Function
02:15Protein and Protein Structures
 02:10
Additional Subnuclear Structures
The nucleus contains many membrane-less subnuclear organelles or nuclear bodies, such as nucleoli, Cajal bodies, speckles,...
 00:56
Viral Structure