Layout-aware text extraction from full-text PDF of scientific articles
Related Experiment Video
Updated: May 22, 2026
A Metadata Extraction Approach for Clinical Case Reports to Enable Advanced Understanding of Biomedical Concepts
Published on: September 20, 2018
Cartic Ramakrishnan1, Abhishek Patnia, Eduard Hovy
1Information Sciences Institute, University of Southern California, 4676 Admiralty Way, Suite 1001, Marina del Rey, CA, 90292-6695, USA. cartic@isi.edu.

Background:
The Portable Document Format (PDF) is the most commonly used file format for online scientific publications. The absence of effective means to extract text from these PDF files in a layout-aware manner presents a significant challenge for developers of biomedical text mining or biocuration informatics systems that use published literature as an information source. In this paper we introduce the 'Layout-Aware PDF Text Extraction' (LA-PDFText) system to facilitate accurate extraction of text from PDF files of research articles for use in text mining applications.
Results:
Our paper describes the construction and performance of an open source system that extracts text blocks from PDF-formatted full-text research articles and classifies them into logical units based on rules that characterize specific sections. The LA-PDFText system focuses only on the textual content of the research articles and is meant as a baseline for further experiments into more advanced extraction methods that handle multi-modal content, such as images and graphs. The system works in a three-stage process: (1) Detecting contiguous text blocks using spatial layout processing to locate and identify blocks of contiguous text, (2) Classifying text blocks into rhetorical categories using a rule-based method and (3) Stitching classified text blocks together in the correct order resulting in the extraction of text from section-wise grouped blocks. We show that our system can identify text blocks and classify them into rhetorical categories with Precision1 = 0.96% Recall = 0.89% and F1 = 0.91%. We also present an evaluation of the accuracy of the block detection algorithm used in step 2. Additionally, we have compared the accuracy of the text extracted by LA-PDFText to the text from the Open Access subset of PubMed Central. We then compared this accuracy with that of the text extracted by the PDF2Text system, 2commonly used to extract text from PDF. Finally, we discuss preliminary error analysis for our system and identify further areas of improvement.
Conclusions:
LA-PDFText is an open-source tool for accurately extracting text from full-text scientific articles. The release of the system is available at http://code.google.com/p/lapdftext/.

Related Concept Videos
 00:56
Extraction: Advanced Methods
 00:53
Extraction: Effects of pH
 01:08
Atomic Force Microscopy
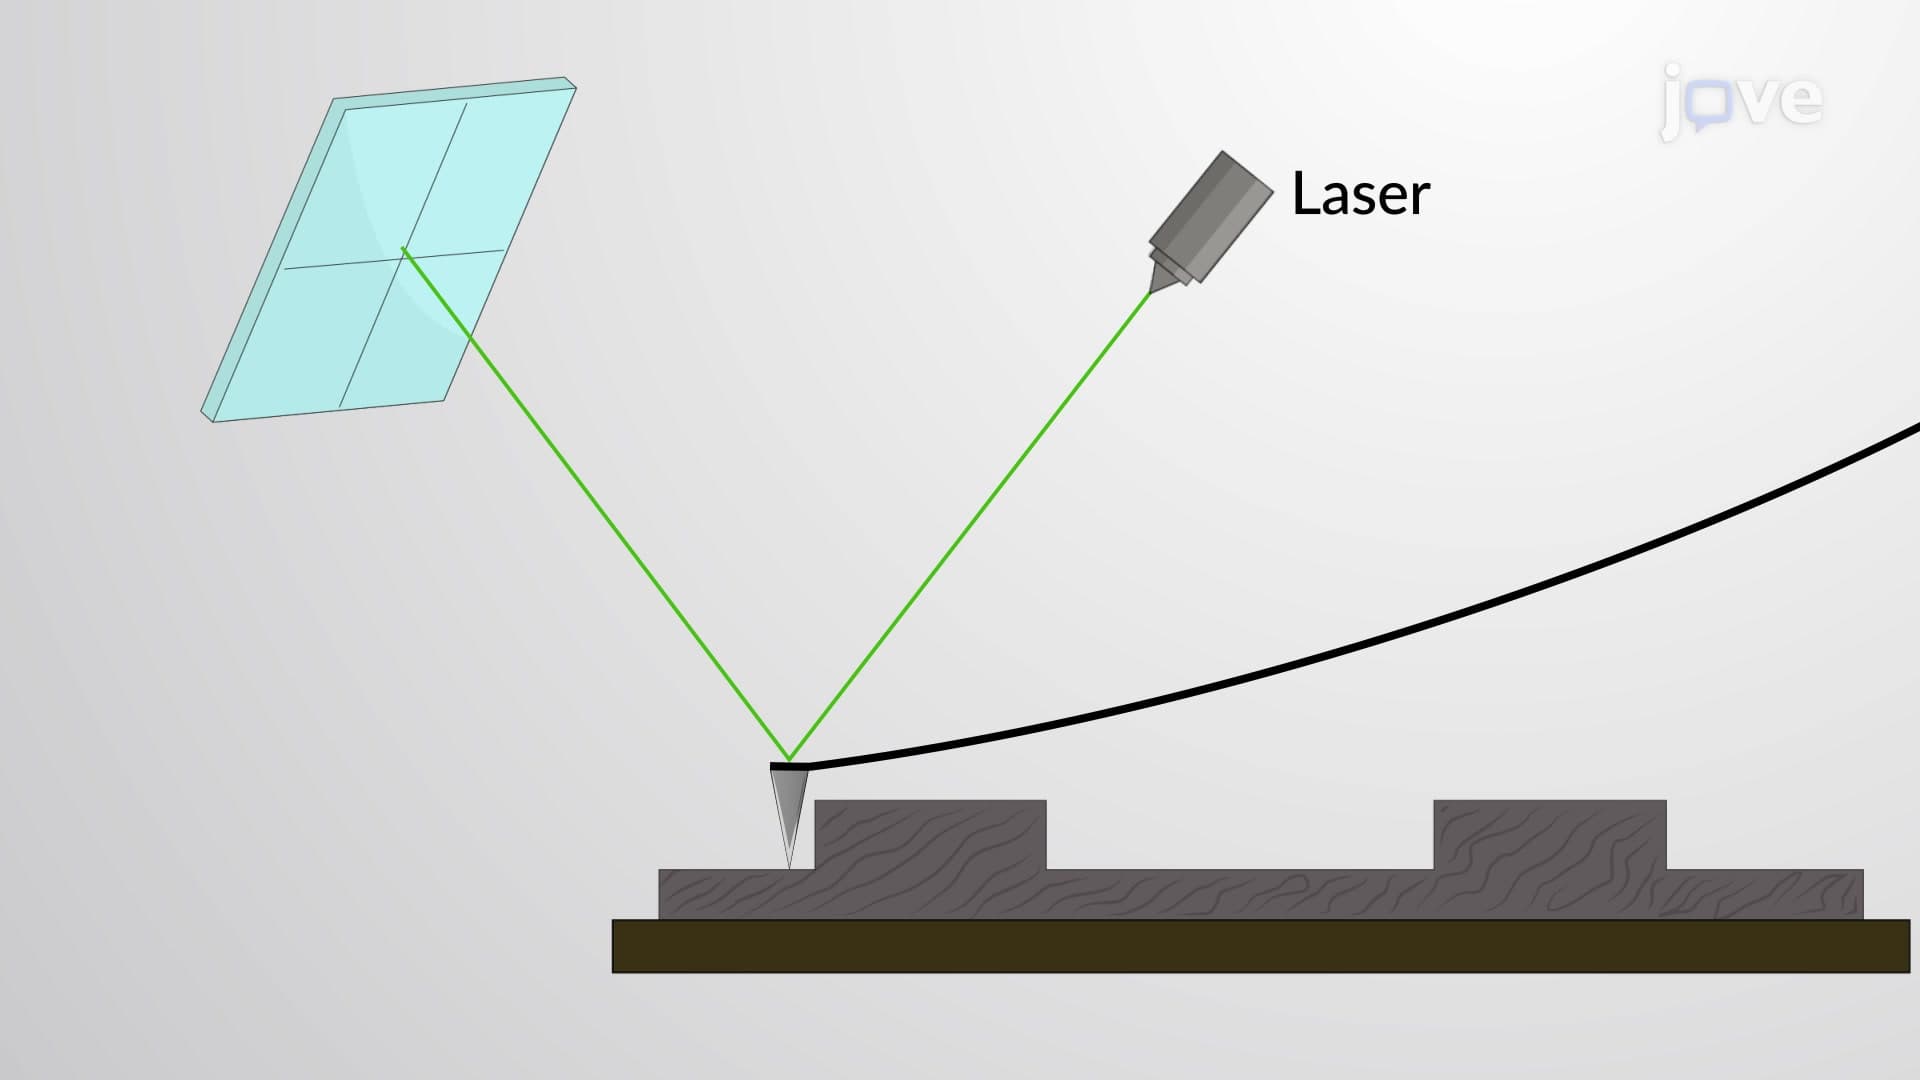
The AFM Probe
The probe is regarded as the heart of any AFM setup and comprises the...
 01:07
Scanning Electron Microscopy
Fundamental Principles
Accelerated...
 01:14
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an organic...
 01:15
Western Blotting
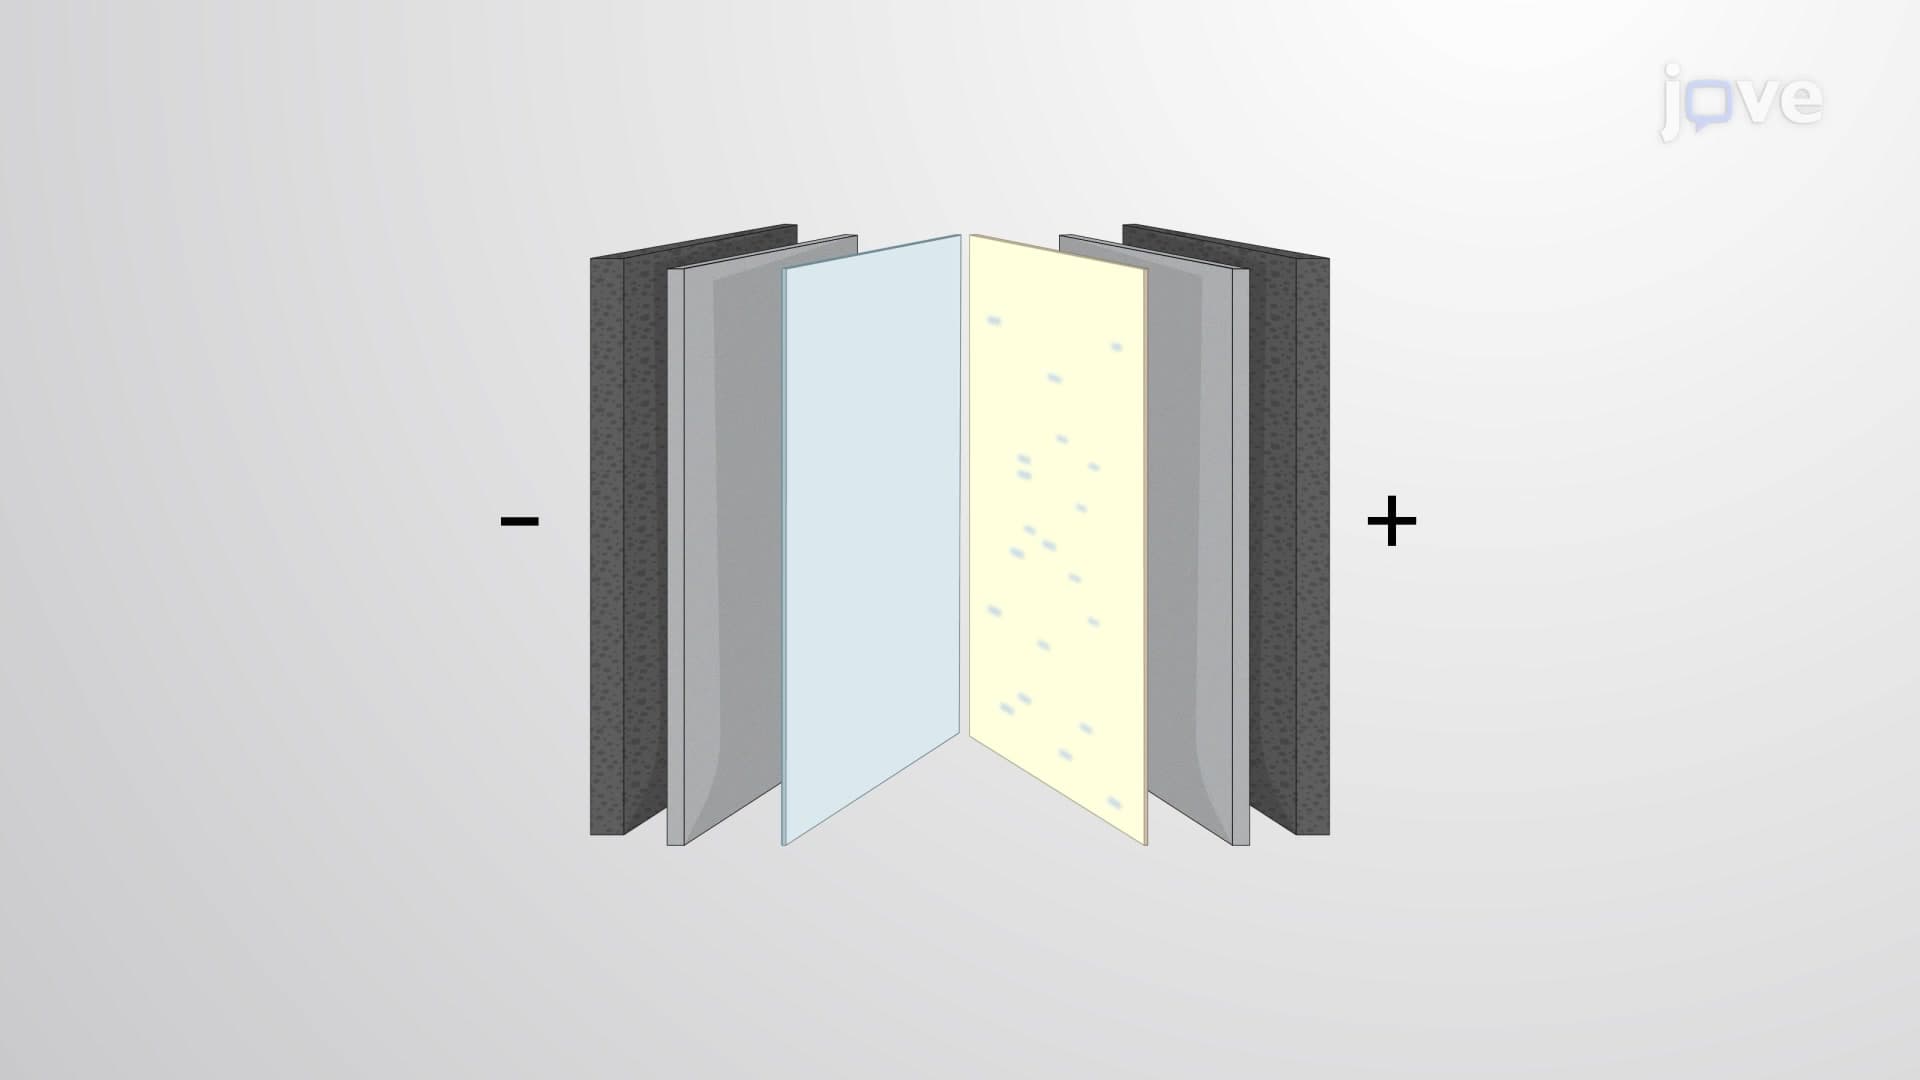
The technique begins with separating proteins from the sample using sodium dodecyl sulfate-polyacrylamide gel electrophoresis (SDS-PAGE), followed by protein transfer, immunoblotting, and finally, protein detection.