Related Experiment Video
Updated: Mar 8, 2026

04:35

Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
3.8K
Multinomial logistic regression to estimate and predict perceptions of bicycle and transportation infrastructure in a
Courtney Coughenour1, Alexander Paz2, Hanns de la Fuente-Mella3
1School of Community Health Sciences, University of Nevada Las Vegas, 4505 S. Maryland Pkwy, Box 3050, Las Vegas, NV 89154-4015, USA.
Journal of Public Health (Oxford, England)
|February 4, 2017

Abstract
No abstract available in PubMed .


Related Concept Videos
 01:25
Multiple Regression
4.2K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
4.2K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
313
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
313
 01:08
Determination of Expected Frequency
2.6K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.6K
 01:17
Probability Histograms
13.4K
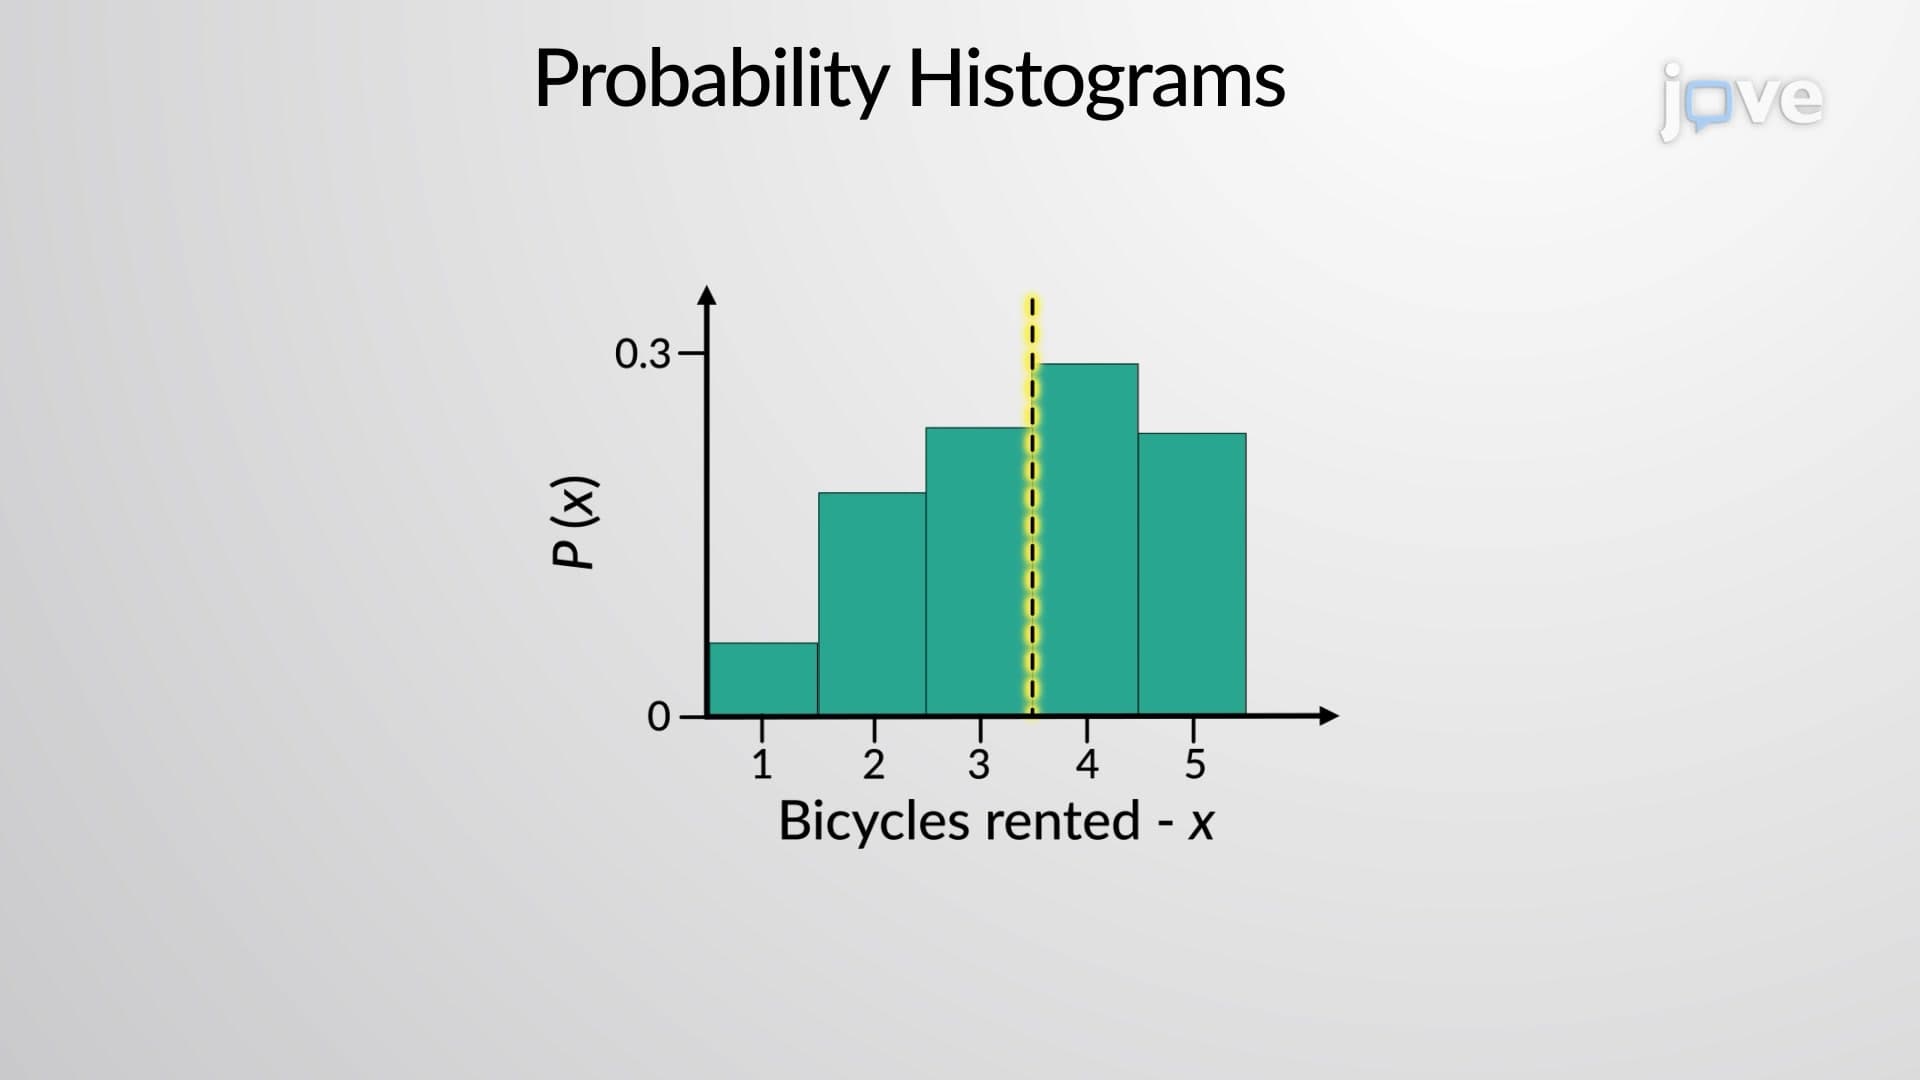
A probability histogram is a visual representation of a probability distribution. Similar a typical histogram, the probability histogram consists of contiguous (adjoining) boxes. It has both a horizontal axis and a vertical axis. The horizontal axis is labeled with what the data represents. The vertical axis is labeled with probability. Each rectangular bar in the histogram is 1 unit wide, which suggests that the area under each bar equals the probability, P(x), where x is 1, 2, 3, and so on.
13.4K
 01:11
Regression Analysis
8.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
8.7K
 01:11
Residuals and Least-Squares Property
9.7K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
9.7K