Related Experiment Video
Updated: Feb 11, 2026
A High-throughput Assay for the Prediction of Chemical Toxicity by Automated Phenotypic Profiling of Caenorhabditis elegans
Published on: March 14, 2019
ProTox-II: a webserver for the prediction of toxicity of chemicals
Priyanka Banerjee1, Andreas O Eckert1, Anna K Schrey1
1Structural Bioinformatics Group, Institute for Physiology & ECRC, Charité - University Medicine Berlin, 10115 Berlin, Germany.

Abstract:
Advancement in the field of computational research has made it possible for the in silico methods to offer significant benefits to both regulatory needs and requirements for risk assessments, and pharmaceutical industry to assess the safety profile of a chemical. Here, we present ProTox-II that incorporates molecular similarity, pharmacophores, fragment propensities and machine-learning models for the prediction of various toxicity endpoints; such as acute toxicity, hepatotoxicity, cytotoxicity, carcinogenicity, mutagenicity, immunotoxicity, adverse outcomes pathways (Tox21) and toxicity targets. The predictive models are built on data from both in vitro assays (e.g. Tox21 assays, Ames bacterial mutation assays, hepG2 cytotoxicity assays, Immunotoxicity assays) and in vivo cases (e.g. carcinogenicity, hepatotoxicity). The models have been validated on independent external sets and have shown strong performance. ProTox-II provides a freely available webserver for in silico toxicity prediction for toxicologists, regulatory agencies, computational and medicinal chemists, and all users without login at http://tox.charite.de/protox_II. The webserver takes a two-dimensional chemical structure as an input and reports the possible toxicity profile of the chemical for 33 models with confidence scores, and an overall toxicity radar chart along with three most similar compounds with known acute toxicity.
Related Concept Videos
 02:27
Predicting Molecular Geometry
 02:37
Types of Chemical Bonds
 02:57
Physical and Chemical Properties of Matter
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 02:52
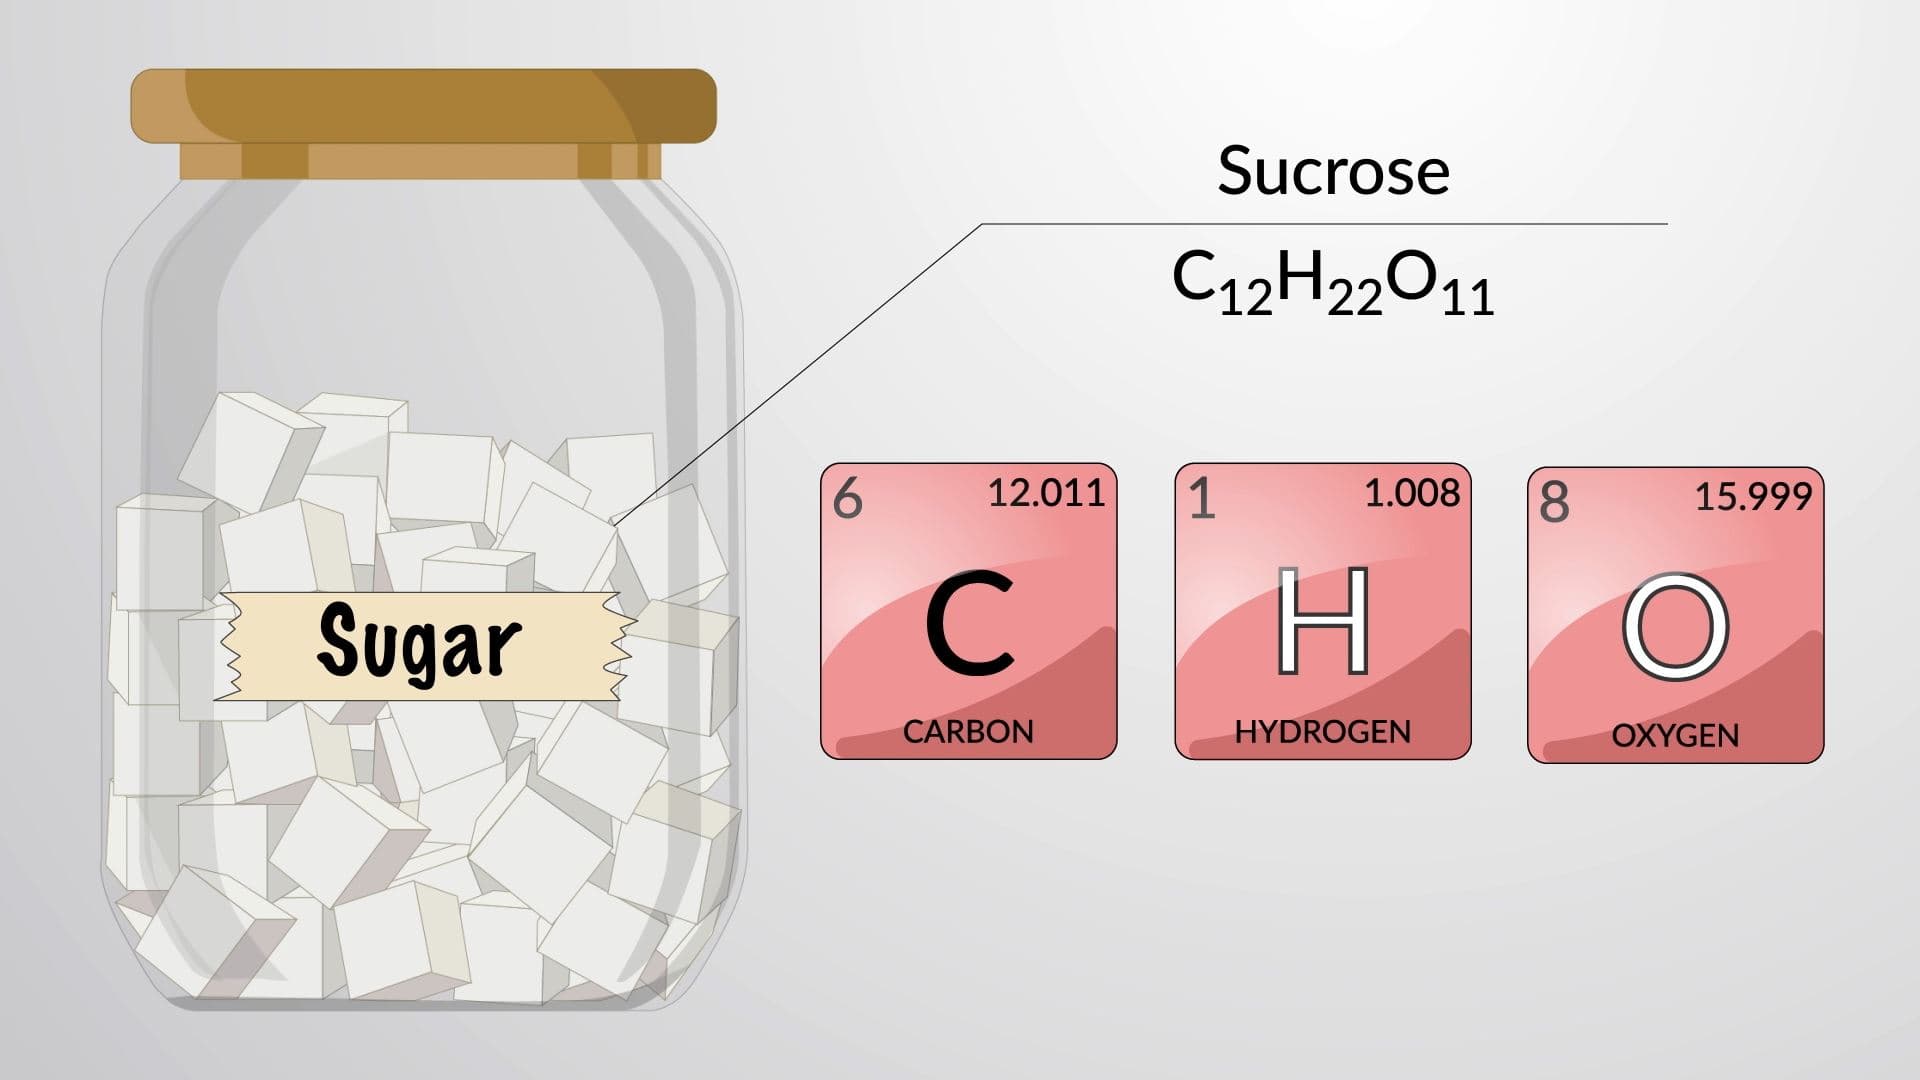
Chemical Formulas
 03:10
Chemical Equations