Related Experiment Video
Updated: Jan 25, 2026

Analysis of Fatty Acid Content and Composition in Microalgae
Published on: October 1, 2013
Reliability of genomic prediction for milk fatty acid composition by using a multi-population reference and
Grum Gebreyesus1,2, Henk Bovenhuis3, Mogens S Lund4
1Department of Molecular Biology and Genetics, Center for Quantitative Genetics and Genomics, Aarhus University, Blichers Allé 20, P.O. Box 50, 8830, Tjele, Denmark. grum.gebreyesus@mbg.au.dk.

Background:
Large-scale phenotyping for detailed milk fatty acid (FA) composition is difficult due to expensive and time-consuming analytical techniques. Reliability of genomic prediction is often low for traits that are expensive/difficult to measure and for breeds with a small reference population size. An effective method to increase reference population size could be to combine datasets from different populations. Prediction models might also benefit from incorporation of information on the biological underpinnings of quantitative traits. Genome-wide association studies (GWAS) show that genomic regions on Bos taurus chromosomes (BTA) 14, 19 and 26 underlie substantial proportions of the genetic variation in milk FA traits. Genomic prediction models that incorporate such results could enable improved prediction accuracy in spite of limited reference population sizes. In this study, we combine gas chromatography quantified FA samples from the Chinese, Danish and Dutch Holstein populations and implement a genomic feature best linear unbiased prediction (GFBLUP) model that incorporates variants on BTA14, 19 and 26 as genomic features for which random genetic effects are estimated separately. Prediction reliabilities were compared to those estimated with traditional GBLUP models.
Results:
Predictions using a multi-population reference and a traditional GBLUP model resulted in average gains in prediction reliability of 10% points in the Dutch, 8% points in the Danish and 1% point in the Chinese populations compared to predictions based on population-specific references. Compared to the traditional GBLUP, implementation of the GFBLUP model with a multi-population reference led to further increases in prediction reliability of up to 38% points in the Dutch, 23% points in the Danish and 13% points in the Chinese populations. Prediction reliabilities from the GFBLUP model were moderate to high across the FA traits analyzed.
Conclusions:
Our study shows that it is possible to predict genetic merits for milk FA traits with reasonable accuracy by combining related populations of a breed and using models that incorporate GWAS results. Our findings indicate that international collaborations that facilitate access to multi-population datasets could be highly beneficial to the implementation of genomic selection for detailed milk composition traits.
More Related Videos
 08:27
Large-Scale Multi-Omics Genome-Wide Association Studies Mo-GWAS: Guidelines for Sample Preparation and Normalization
Published on: July 27, 2021
 07:27
Optimized Incorporation of Alkynyl Fatty Acid Analogs for the Detection of Fatty Acylated Proteins using Click Chemistry
Published on: April 9, 2021
Related Concept Videos
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:29
Reliability and Validity
 01:28
Overview of Fatty Acid Metabolism
Fatty acids are catabolized in a process called beta-oxidation, which takes place in the matrix of the mitochondria and converts their fatty acid chains into two-carbon units of acetyl groups. The acetyl...
 01:17
Solution Composition During Acid/Base Titrations
The α0 and α1 values...
 01:19
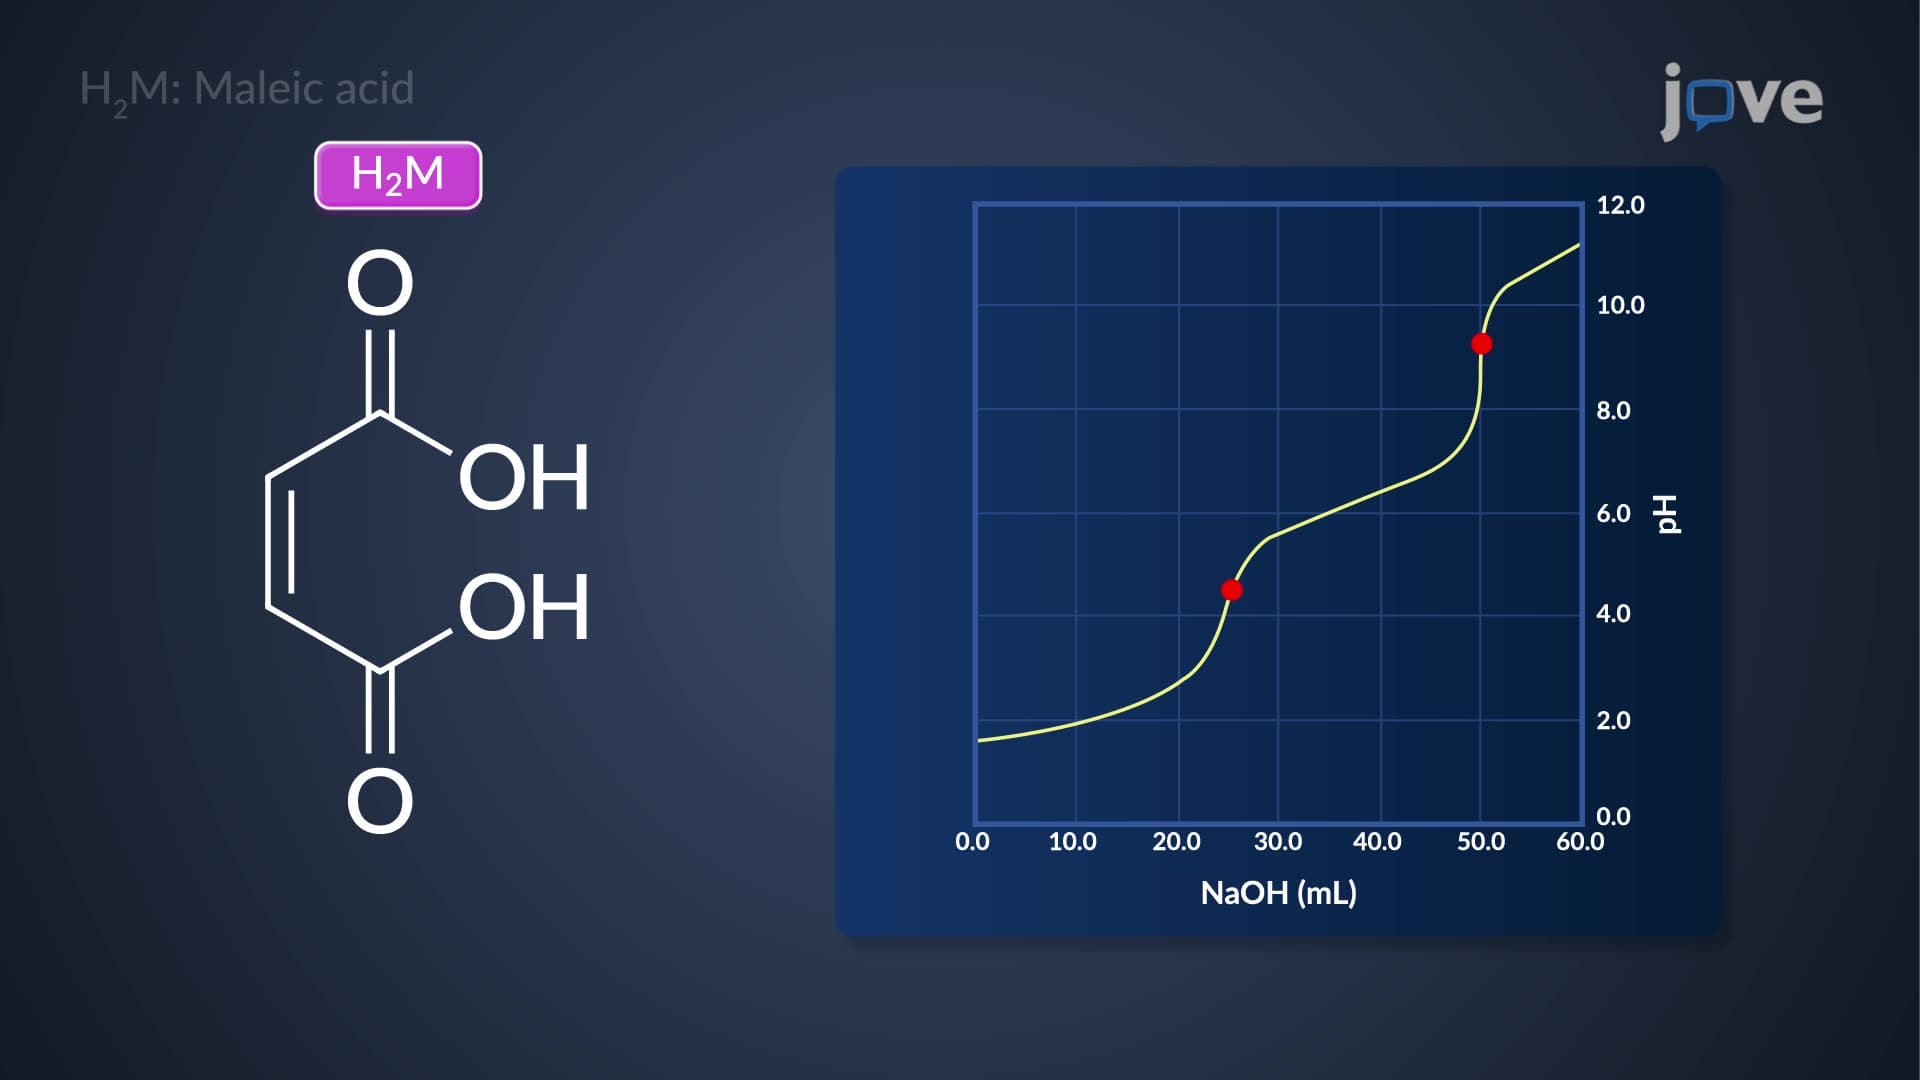
Composition of Polyprotic Acid Solutions as a Function of pH
A graph with the alpha values is plotted against the volume of...
 00:57
Population Growth