Related Experiment Video
Updated: Jan 22, 2026
Deep Learning-Based Segmentation of Cryo-Electron Tomograms
Published on: November 11, 2022
Revisiting Video Saliency Prediction in the Deep Learning Era

Abstract:
Predicting where people look in static scenes, a.k.a visual saliency, has received significant research interest recently. However, relatively less effort has been spent in understanding and modeling visual attention over dynamic scenes. This work makes three contributions to video saliency research. First, we introduce a new benchmark, called DHF1K (Dynamic Human Fixation 1K), for predicting fixations during dynamic scene free-viewing, which is a long-time need in this field. DHF1K consists of 1K high-quality elaborately-selected video sequences annotated by 17 observers using an eye tracker device. The videos span a wide range of scenes, motions, object types and backgrounds. Second, we propose a novel video saliency model, called ACLNet (Attentive CNN-LSTM Network), that augments the CNN-LSTM architecture with a supervised attention mechanism to enable fast end-to-end saliency learning. The attention mechanism explicitly encodes static saliency information, thus allowing LSTM to focus on learning a more flexible temporal saliency representation across successive frames. Such a design fully leverages existing large-scale static fixation datasets, avoids overfitting, and significantly improves training efficiency and testing performance. Third, we perform an extensive evaluation of the state-of-the-art saliency models on three datasets : DHF1K, Hollywood-2, and UCF sports. An attribute-based analysis of previous saliency models and cross-dataset generalization are also presented. Experimental results over more than 1.2K testing videos containing 400K frames demonstrate that ACLNet outperforms other contenders and has a fast processing speed (40 fps using a single GPU). Our code and all the results are available at https://github.com/wenguanwang/DHF1K.
More Related Videos
 09:34
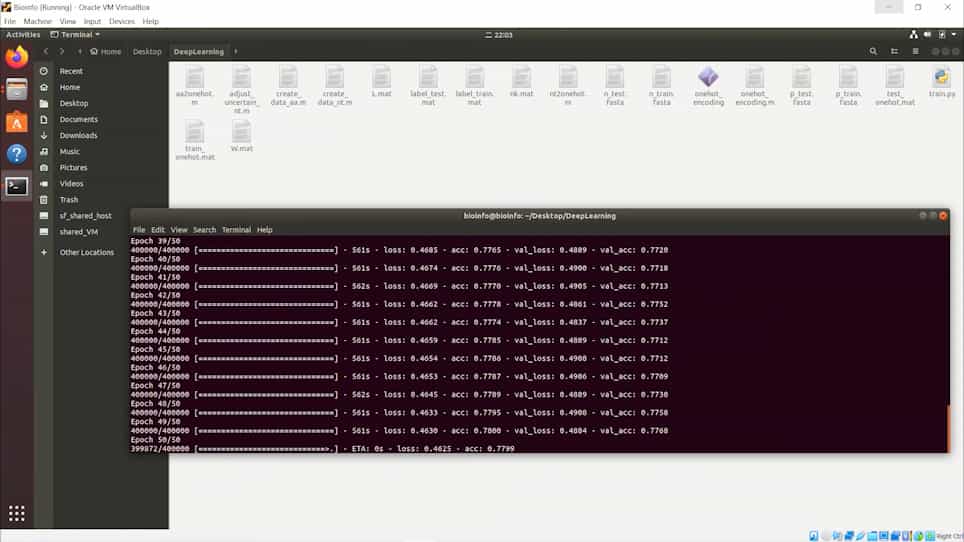
A Virtual Machine Platform for Non-Computer Professionals for Using Deep Learning to Classify Biological Sequences of Metagenomic Data
Published on: September 25, 2021
 05:41
A Step-by-Step Implementation of DeepBehavior, Deep Learning Toolbox for Automated Behavior Analysis
Published on: February 6, 2020
Related Concept Videos
 02:27
Predicting Molecular Geometry
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:14
Avoidance Learning and Learned Helplessness
Avoidance learning occurs when an organism learns that a specific behavior can prevent an unpleasant outcome. For example, a student who receives a bad grade may start studying harder to avoid future poor grades. This behavior persists even when the negative outcome is no longer present. Avoidance learning is powerful because it maintains behavior in the absence of the...
 01:07
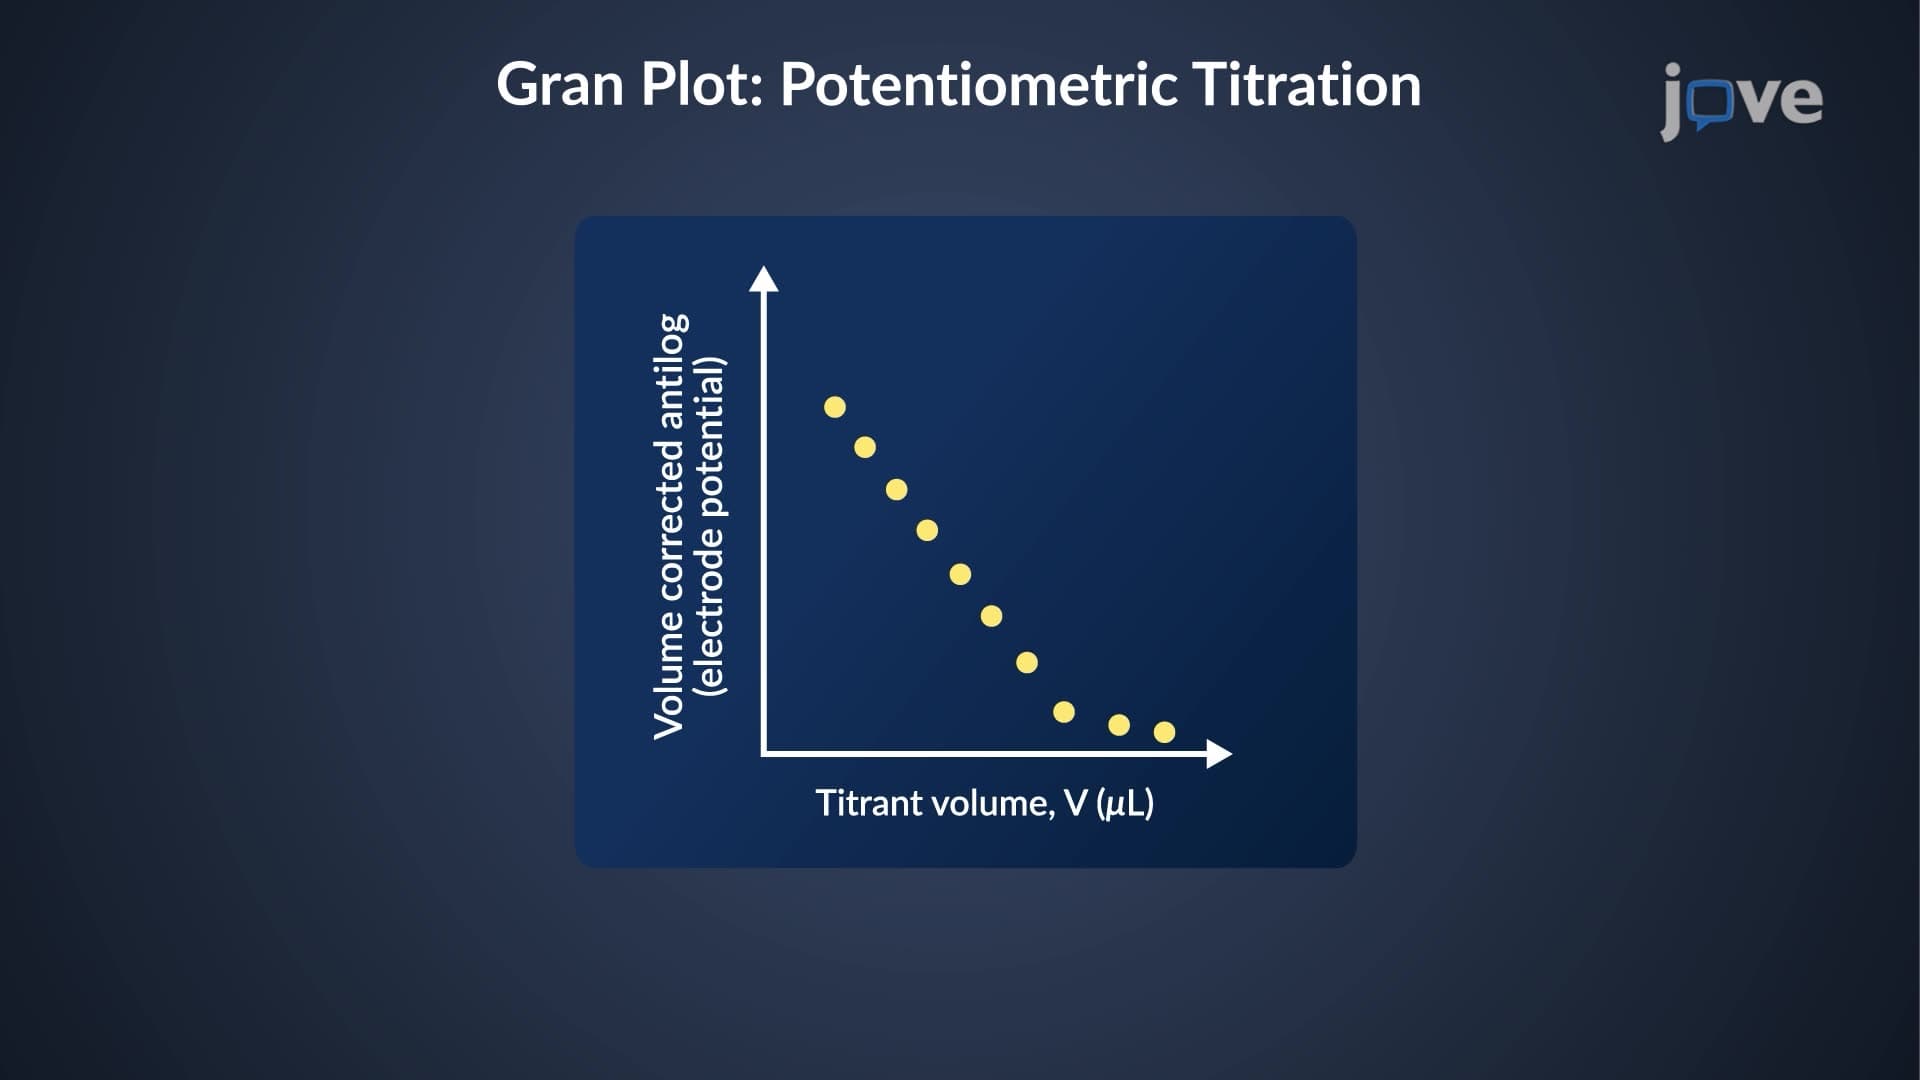
End Point Prediction: Gran Plot
For potentiometric titration, the Gran plot is created by plotting...
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 02:24
Predicting Reaction Outcomes