Related Experiment Video
Updated: Jan 2, 2026

Holistic Facial Composite Creation and Subsequent Video Line-up Eyewitness Identification Paradigm
Published on: December 24, 2015
Self-Enhanced Convolutional Network for Facial Video Hallucination

Abstract:
As a domain-specific super-resolution problem, facial image hallucination has enjoyed a series of breakthroughs thanks to the advances of deep convolutional neural networks. However, the direct migration of existing methods to video is still difficult to achieve good performance due to its lack of alignment and consistency modelling in temporal domain. Taking advantage of high inter-frame dependency in videos, we propose a selfenhanced convolutional network for facial video hallucination. It is implemented by making full usage of preceding super-resolved frames and a temporal window of adjacent low-resolution frames. Specifically, the algorithm first obtains the initial high-resolution inference of each frame by taking into consideration a sequence of consecutive low-resolution inputs through temporal consistency modelling. It further recurrently exploits the reconstructed results and intermediate features of a sequence of preceding frames to improve the initial super-resolution of the current frame by modelling the coherence of structural facial features across frames. Quantitative and qualitative evaluations demonstrate the superiority of the proposed algorithm against state-of-theart methods. Moreover, our algorithm also achieves excellent performance in the task of general video super-resolution in a single-shot setting.
More Related Videos
Related Concept Videos
 01:24
Facial Feedback Hypothesis
 01:24
Prosopagnosia
 01:19
Masking and Demasking Agents
There are many masking agents, such as cyanide, fluoride, triethanolamine, thiourea, and 2,3-bis(sulfanyl)propan-1-ol (formerly 2,3-dimercapto-1-propanol), with the masking agent chosen based on...
 01:20
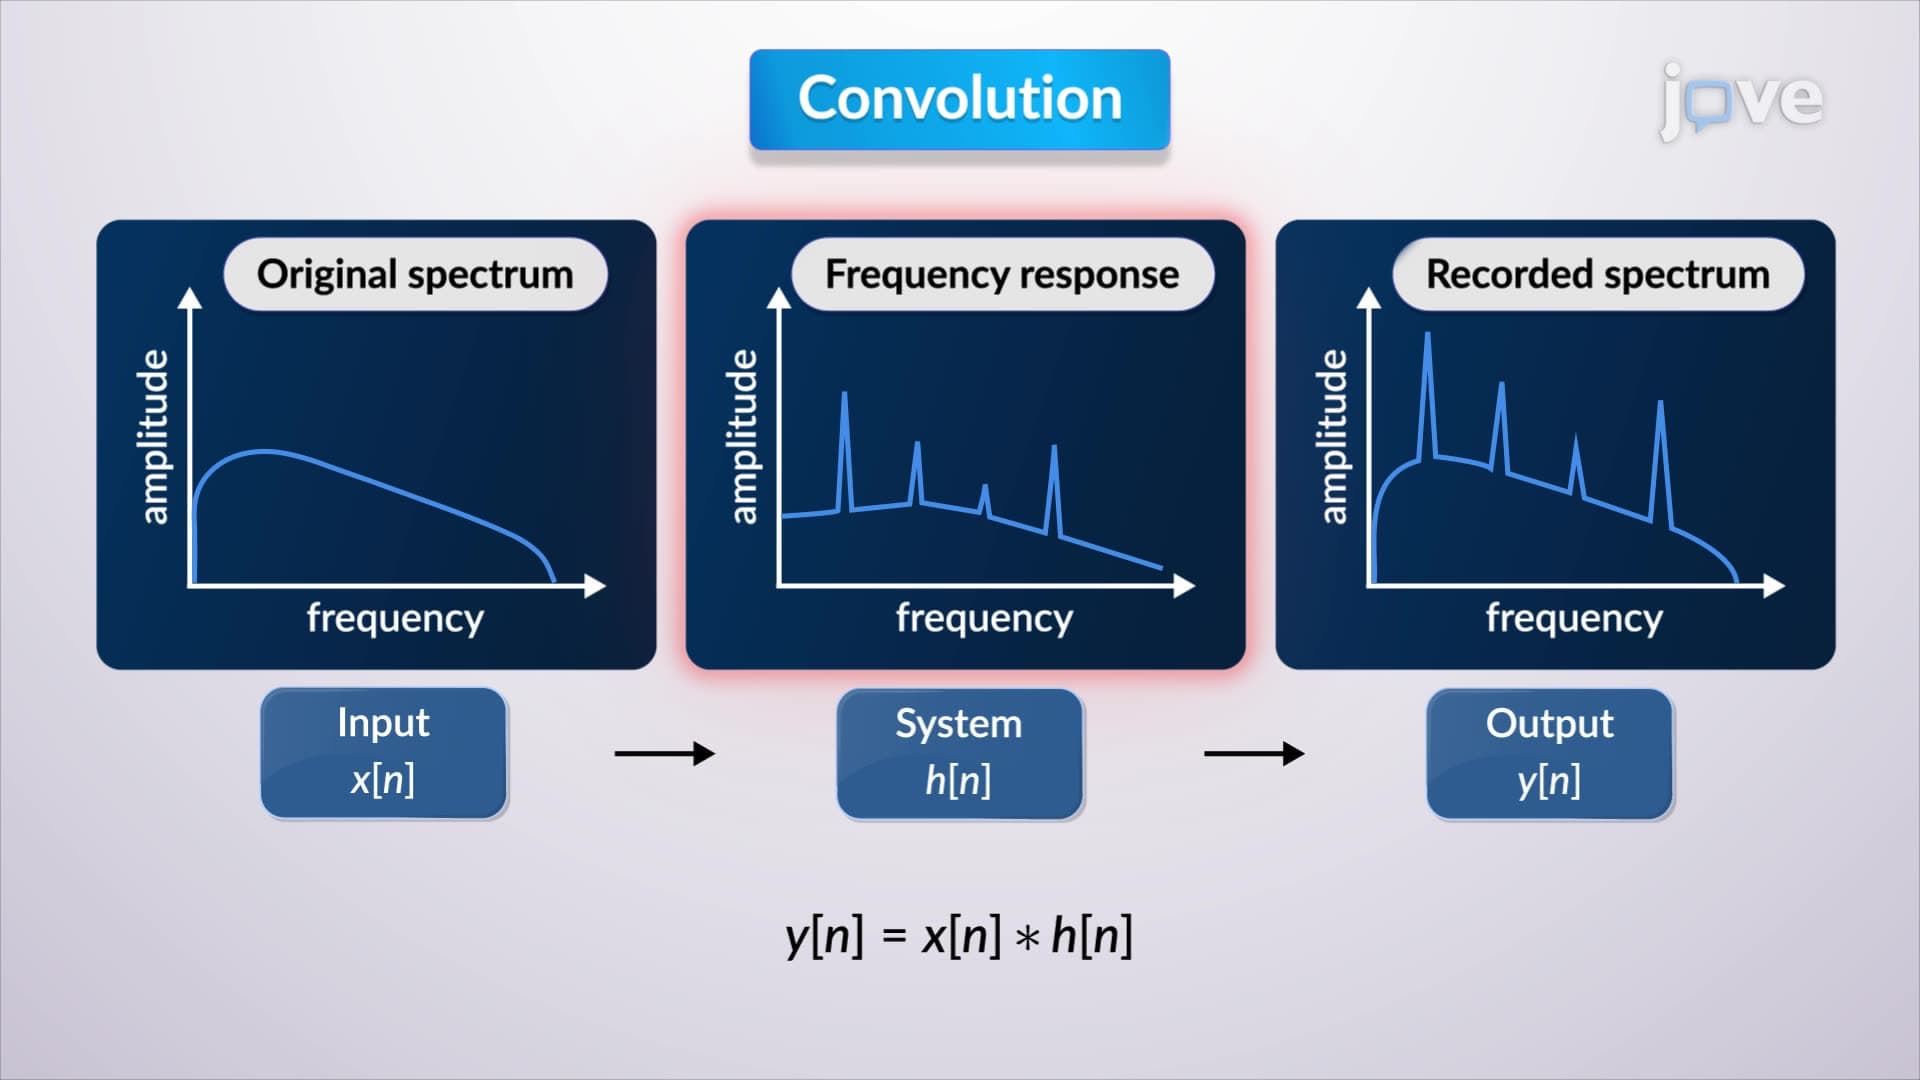
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...