Related Experiment Video
Updated: Oct 25, 2025
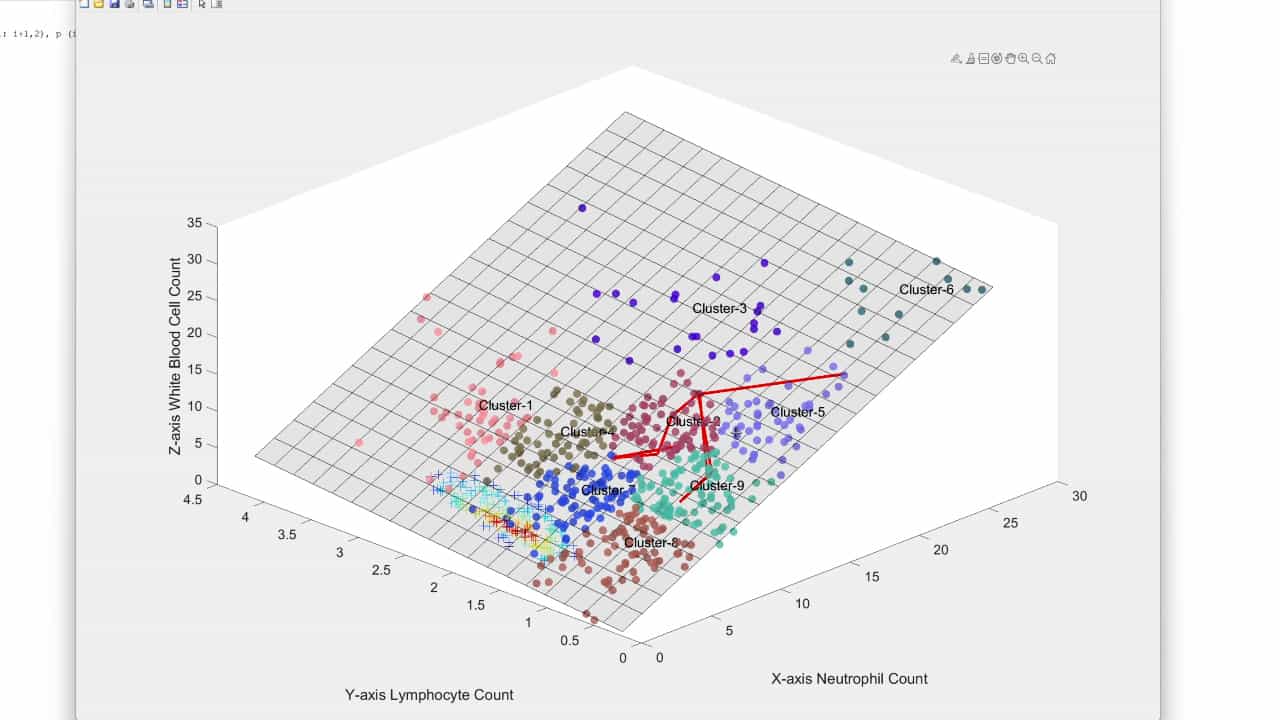

A Data-Driven Approach to Quantifying Immune States in Sepsis
Published on: February 7, 2025
Machine learned hybrid Gaussian analysis of COVID-19 pandemic in India
Shivam Bhardwaj1, Majed Alowaidi2, Rashmi Bhardwaj3
1Maharaja Agrasen Institute of Technology, Guru Gobind Singh Indraprastha University, Delhi, India.

Abstract:
This article discusses short term forecasting of the Novel Corona Virus (COVID -19) data for infected, recovered and active cases using the Machine learned hybrid Gaussian and ARIMA method for the spread in India. The Covid-19 data is obtained from the World meter and MOH (Ministry of Health, India). The data is analyzed for the period from January 30, 2020 (the first case reported) to October 15, 2020. Using ARIMA (2, 1, 0), we obtain the short forecast up to October 31, 2020. The several statistics parameters have tested for the goodness of fit to evaluate the forecasting methods but the results show that ARIMA (2, 1, 0) gives better forecast for the data system. It is observed that COVID 19 data follows quadratic behavior and in long run it spreads with high peak roughly estimated in September 18, 2020. Also, using nonlinear regression it is observed that the trend in long run follows the Gaussian mixture model. It is concluded that COVID 19 will follow secondary shock wave in the month of November 2020. In India we are approaching towards herd immunity. Also, it is observed that the impact of pandemic will be about 441 to 465 days and the pandemic will end in between April-May 2021. It is concluded that primary peak observed in September 2020 and the secondary shock wave to be around November 2020 with sharp peak. Thus, it is concluded that the people should follow precautionary measures and it is better to maintain social distancing with all safety measures as the pandemic situation is not in control due to non-availability of medicines.
Related Concept Videos
 01:18
Steps in Outbreak Investigation
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:12
Quantitative Analysis
In quantitative analysis, two key measurements are made: the sample quantity and a property proportional to the amount of the analyte (the substance being analyzed). This forms the basis of the...
 01:09
Types of Skewness
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...