Related Experiment Video
Updated: Aug 17, 2025

Development of a Gaze-Contingent Display Framework Designed for Perceptual and Oculomotor Research with Simulated Central Vision Loss
Published on: April 11, 2025
Understanding 3D vision as a policy network
1School of Psychology and Clinical Language Sciences, University of Reading, RG6 6AL Reading, UK.

Abstract:
It is often assumed that the brain builds 3D coordinate frames, in retinal coordinates (with binocular disparity giving the third dimension), head-centred, body-centred and world-centred coordinates. This paper questions that assumption and begins to sketch an alternative based on, essentially, a set of reflexes. A 'policy network' is a term used in reinforcement learning to describe the set of actions that are generated by an agent depending on its current state. This is an untypical starting point for describing 3D vision, but a policy network can serve as a useful representation both for the 3D layout of a scene and the location of the observer within it. It avoids 3D reconstruction of the type used in computer vision but is similar to recent representations for navigation generated through reinforcement learning. A policy network for saccades (pure rotations of the camera/eye) is a logical starting point for understanding (i) an ego-centric representation of space (e.g. Marr's (Marr 1982 Vision: a computational investigation into the human representation and processing of visual information) 2[Formula: see text]-D sketch) and (ii) a hierarchical, compositional representation for navigation. The potential neural implementation of policy networks is straightforward; a network with a large range of sensory and task-related inputs such as the cerebellum would be capable of implementing this input/output function. This is not the case for 3D coordinate transformations in the brain: no neurally implementable proposals have yet been put forward that could carry out a transformation of a visual scene from retinal to world-based coordinates. Hence, if the representation underlying 3D vision can be described as a policy network (in which the actions are either saccades or head translations), this would be a significant step towards a neurally plausible model of 3D vision. This article is part of the theme issue 'New approaches to 3D vision'.
More Related Videos
Related Concept Videos
 01:15
Depth Perception and Spatial Vision
 01:24
Vision
 01:26
Visual System
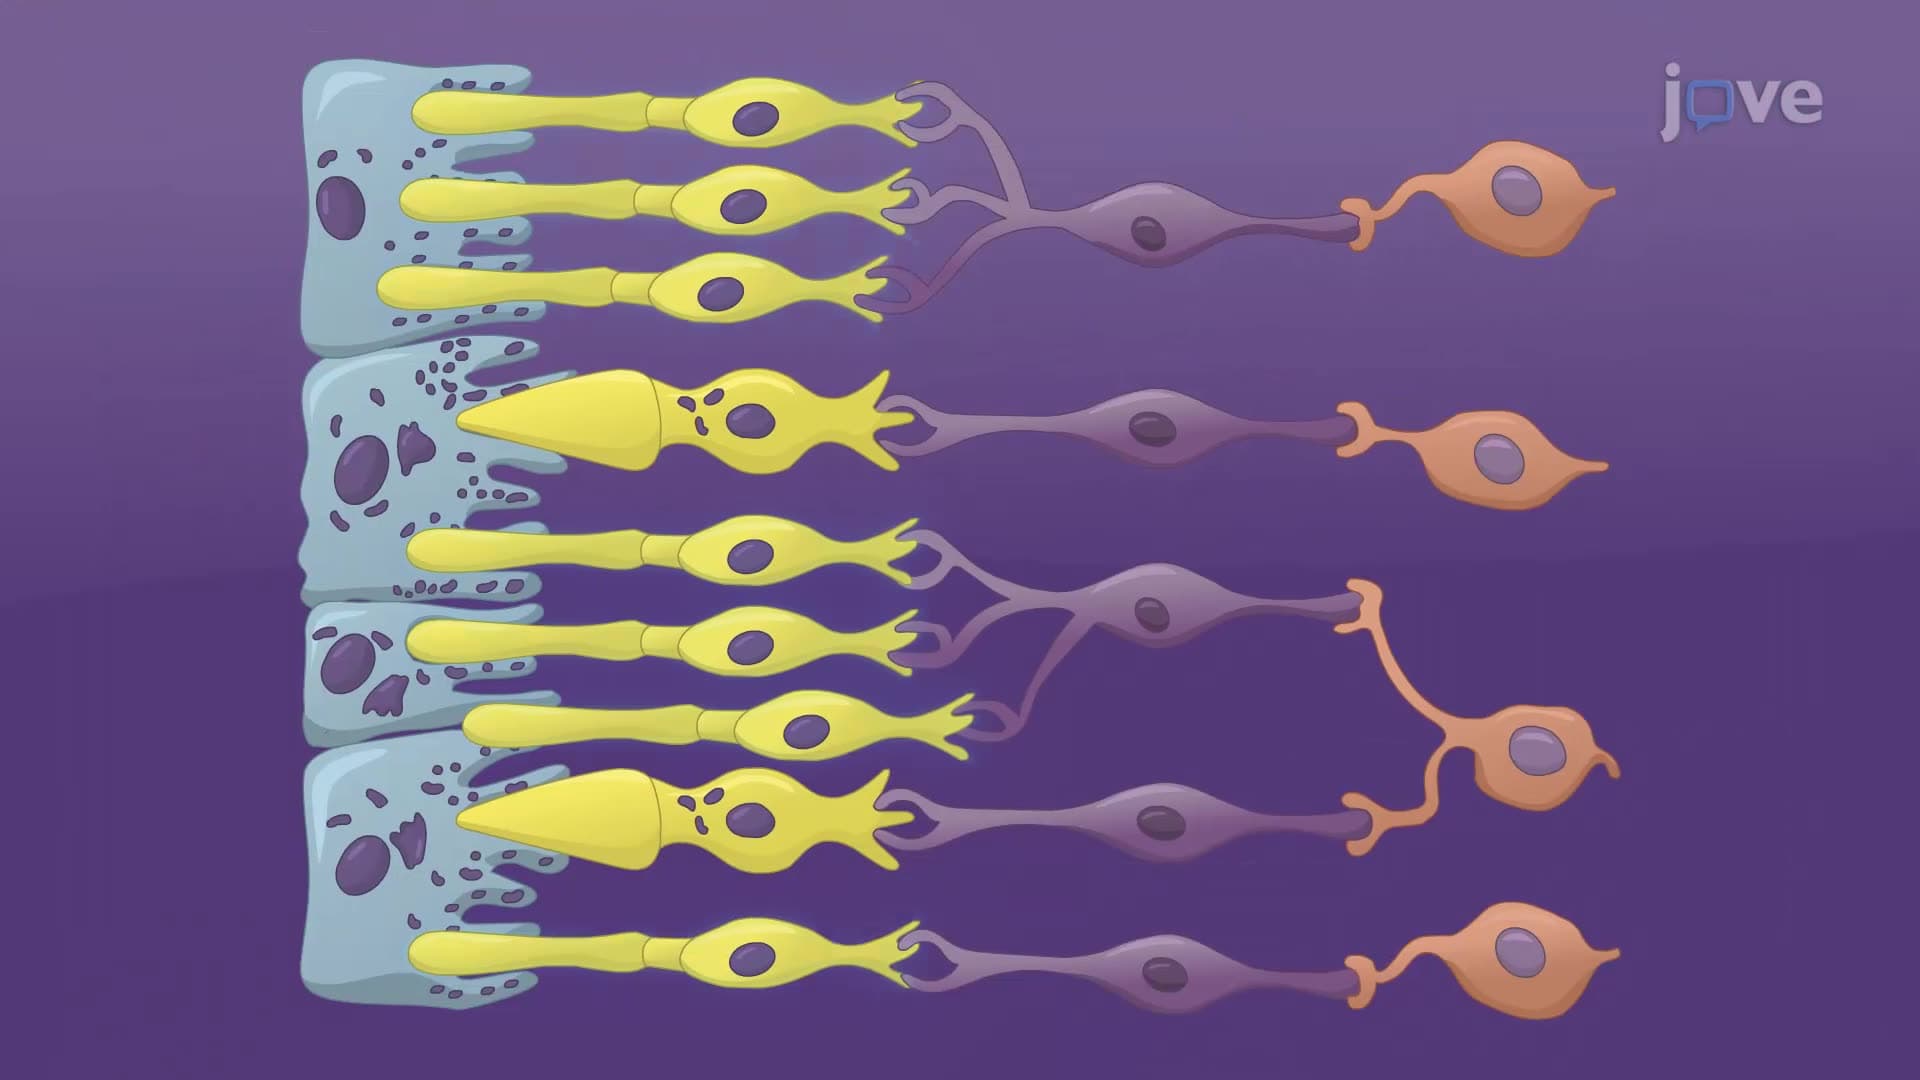
Once through the pupil, the light passes through the lens, a...
 01:24
Color Vision
 01:21
Gestalt Principles of Perception
 01:27
Support Reactions in Three Dimensions
Ball and Socket Joint is one of the supports allowing free rotation about any axis. This freedom of rotation is...