Related Experiment Video
Updated: Jul 5, 2025


Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
Data aggregation can lead to biased inferences in Bayesian linear mixed models and Bayesian analysis of variance
Daniel J Schad1, Bruno Nicenboim2, Shravan Vasishth3
1Institute for Mind, Brain and Behavior, Health and Medical University (HMU).

Abstract:
Bayesian linear mixed-effects models (LMMs) and Bayesian analysis of variance (ANOVA) are increasingly being used in the cognitive sciences to perform null hypothesis tests, where a null hypothesis that an effect is zero is compared with an alternative hypothesis that the effect exists and is different from zero. While software tools for Bayes factor null hypothesis tests are easily accessible, how to specify the data and the model correctly is often not clear. In Bayesian approaches, many authors use data aggregation at the by-subject level and estimate Bayes factors on aggregated data. Here, we use simulation-based calibration for model inference applied to several example experimental designs to demonstrate that, as with frequentist analysis, such null hypothesis tests on aggregated data can be problematic in Bayesian analysis. Specifically, when random slope variances differ (i.e., violated sphericity assumption), Bayes factors are too conservative for contrasts where the variance is small and they are too liberal for contrasts where the variance is large. Running Bayesian ANOVA on aggregated data can-if the sphericity assumption is violated-likewise lead to biased Bayes factor results. Moreover, Bayes factors for by-subject aggregated data are biased (too liberal) when random item slope variance is present but ignored in the analysis. These problems can be circumvented or reduced by running Bayesian LMMs on nonaggregated data such as on individual trials, and by explicitly modeling the full random effects structure. Reproducible code is available from https://osf.io/mjf47/. (PsycInfo Database Record (c) 2025 APA, all rights reserved).

Related Concept Videos
 01:22
Bias
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...
 01:29
Bias in Epidemiological Studies
 01:20
Biostatistics: Overview
Discrete variables are...
 01:12
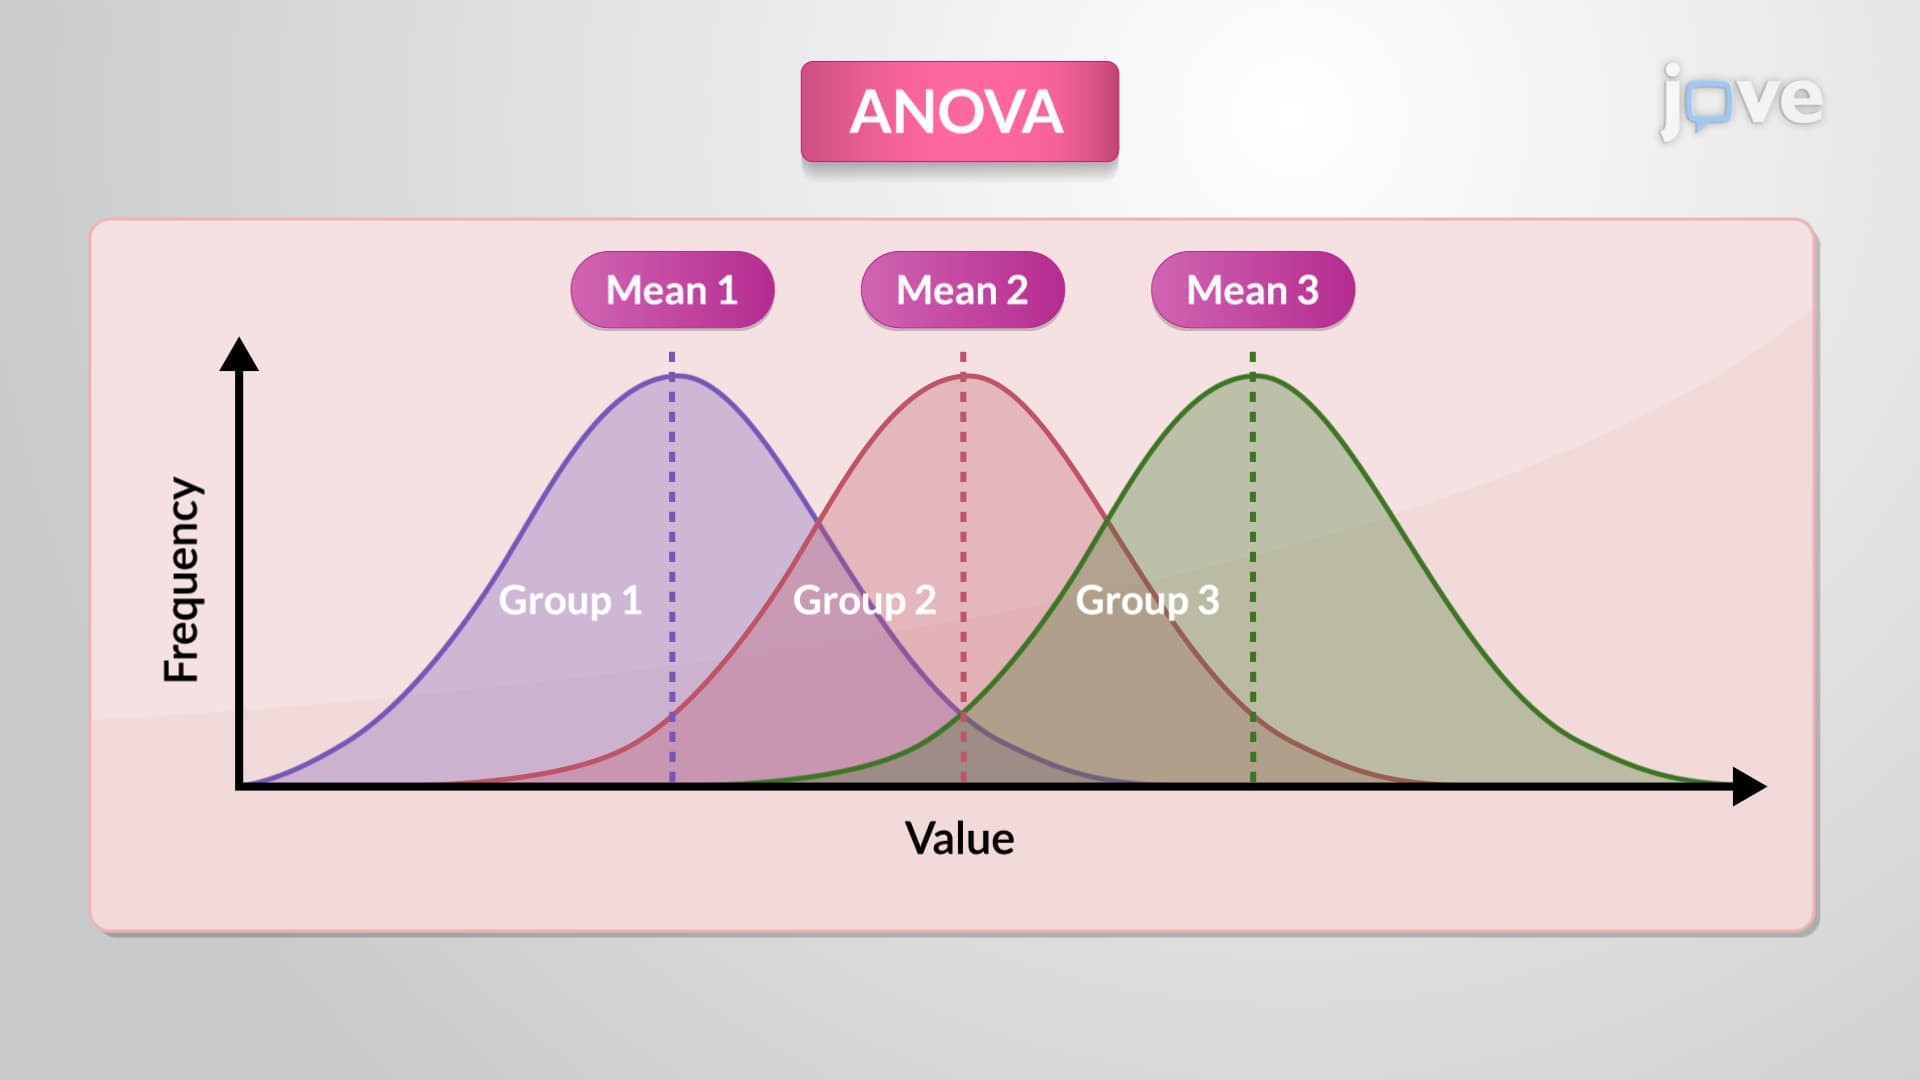
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:18
One-Way ANOVA
 01:15
One-Way ANOVA: Equal Sample Sizes
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...