Related Experiment Video
Updated: Jul 2, 2025

Foreign Accent and Forensic Speaker Identification in Voice Lineups: The Influence of Acoustic Features Based on Prosody
Published on: September 27, 2024
The Effect on Speech-in-Noise Perception of Real Faces and Synthetic Faces Generated with either Deep Neural Networks
Yingjia Yu1, Anastasia Lado1, Yue Zhang2
1Department of Neurosurgery, Perelman School of Medicine, University of Pennsylvania.

Abstract:
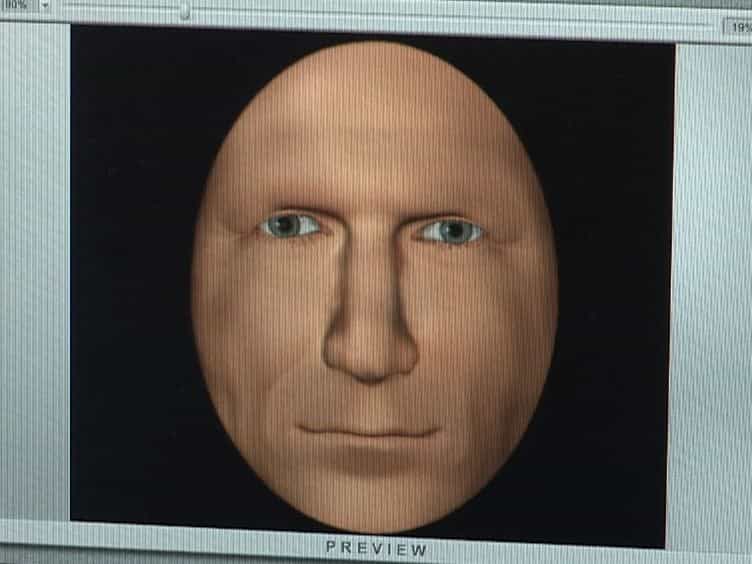
The prevalence of synthetic talking faces in both commercial and academic environments is increasing as the technology to generate them grows more powerful and available. While it has long been known that seeing the face of the talker improves human perception of speech-in-noise, recent studies have shown that synthetic talking faces generated by deep neural networks (DNNs) are also able to improve human perception of speech-in-noise. However, in previous studies the benefit provided by DNN synthetic faces was only about half that of real human talkers. We sought to determine whether synthetic talking faces generated by an alternative method would provide a greater perceptual benefit. The facial action coding system (FACS) is a comprehensive system for measuring visually discernible facial movements. Because the action units that comprise FACS are linked to specific muscle groups, synthetic talking faces generated by FACS might have greater verisimilitude than DNN synthetic faces which do not reference an explicit model of the facial musculature. We tested the ability of human observers to identity speech-in-noise accompanied by a blank screen; the real face of the talker; and synthetic talking face generated either by DNN or FACS. We replicated previous findings of a large benefit for seeing the face of a real talker for speech-in-noise perception and a smaller benefit for DNN synthetic faces. FACS faces also improved perception, but only to the same degree as DNN faces. Analysis at the phoneme level showed that the performance of DNN and FACS faces was particularly poor for phonemes that involve interactions between the teeth and lips, such as /f/, /v/, and /th/. Inspection of single video frames revealed that the characteristic visual features for these phonemes were weak or absent in synthetic faces. Modeling the real vs. synthetic difference showed that increasing the realism of a few phonemes could substantially increase the overall perceptual benefit of synthetic faces, providing a roadmap for improving communication in this rapidly developing domain.
More Related Videos

Related Concept Videos
 01:25
Factors Affecting Perception
An illustrative example of a perceptual set is the scenario where an airline pilot told...
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by...
 01:24
Facial Feedback Hypothesis