Related Experiment Video
Updated: Jun 18, 2025
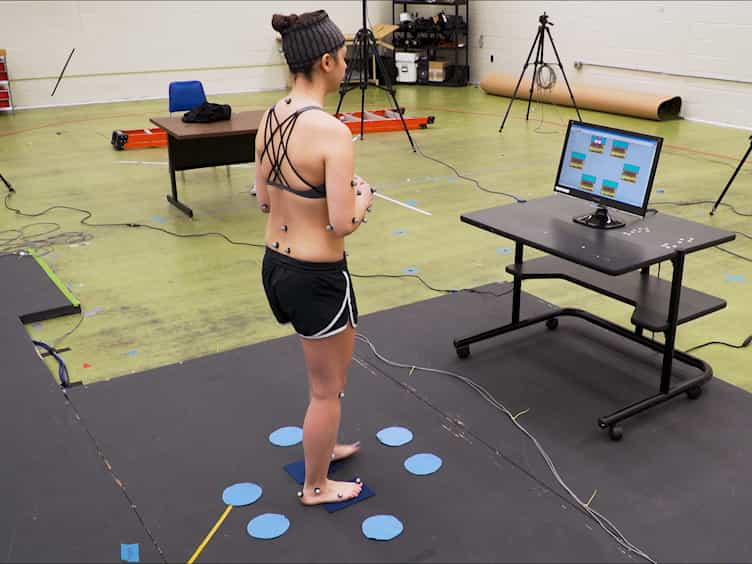

The "Motor" in Implicit Motor Sequence Learning: A Foot-stepping Serial Reaction Time Task
Published on: May 3, 2018
Adaptive self-supervised learning for sequential recommendation
Xiujuan Sun1, Fuzhen Sun1, Zhiwei Zhang1
1School of Computer Science and Technology, Shandong University of Technology, China.

Abstract:
Sequential recommendation typically utilizes deep neural networks to mine rich information in interaction sequences. However, existing methods often face the issue of insufficient interaction data. To alleviate the sparsity issue, self-supervised learning is introduced into sequential recommendation. Despite its effectiveness, we argue that current self-supervised learning-based (i.e., SSL-based) sequential recommendation models have the following limitations: (1) using only a single self-supervised learning method, either contrastive self-supervised learning or generative self-supervised learning. (2) employing a simple data augmentation strategy in either the graph structure domain or the node feature domain. We believe that they have not fully utilized the capabilities of both self-supervised methods and have not sufficiently explored the advantages of combining graph augmentation schemes. As a result, they often fail to learn better item representations. In light of this, we propose a novel multi-task sequential recommendation framework named Adaptive Self-supervised Learning for sequential Recommendation (ASLRec). Specifically, our framework combines contrastive and generative self-supervised learning methods adaptively, simultaneously applying different perturbations at both the graph topology and node feature levels. This approach constructs diverse augmented graph views and employs multiple loss functions (including contrastive loss, generative loss, mask loss, and prediction loss) for joint training. By encompassing the capabilities of various methods, our model learns item representations across different augmented graph views to achieve better performance and effectively mitigate interaction noise and sparsity. In addition, we add a small proportion of random uniform noise to item representations, making the item representations more uniform and mitigating the inherent popularity bias in interaction records. We conduct extensive experiments on three publicly available benchmark datasets to evaluate our model. The results demonstrate that our approach achieves state-of-the-art performance compared to 14 other competitive methods: the hit rate (HR) improved by over 14.39%, and the normalized discounted cumulative gain (NDCG) increased by over 18.67%.
Related Concept Videos
 02:05
Self-Presentation: Self-Monitoring and Self-Handicapping
 02:16
Self-Schemas
 02:27
Predicting Products: SN1 vs. SN2
With increased substitution on the alkyl halide,...
 02:57
The Sense of Self: Reflected Self-Appraisal and Social Comparison
 03:00
Self-Evaluation: Self-Enhancement and Self-Verification
 01:12
Observational Learning