A general TD-Q learning control approach for discrete-time Markov jump systems
Related Experiment Video
Updated: May 23, 2025

WheelCon: A Wheel Control-Based Gaming Platform for Studying Human Sensorimotor Control
Published on: August 15, 2020
Jiwei Wen1, Huiwen Xue1, Xiaoli Luan1
1Key Laboratory of Advanced Process Control for Light Industry (Ministry of Education), School of Internet of Things Engineering, Jiangnan University, Wuxi 214122, China.

Abstract:
This paper develops a novel temporal difference Q (TD-Q) learning approach, designed to address the robust control challenge in discrete-time Markov jump systems (MJSs) which are characterized by entirely unknown dynamics and transition probabilities (TPs). The model-free TD-Q learning method is uniquely comprehensive, including two special cases: Q learning for MJSs with unknown dynamics, and TD learning for MJSs with undetermined TPs. We propose an innovative ternary policy iteration framework, which iteratively refines the control policies through a dynamic loop of alternating updates. This loop consists of three synergistic processes: firstly, aligning TD value functions with current policies; secondly, enhancing Q-function's matrix kernels (QFMKs) using these TD value functions; and thirdly, generating greedy policies based on the enhanced QFMKs. We demonstrate that, with a sufficient number of episodes, the TD value functions, QFMKs, and control policies converge optimally within this iterative loop. To illustrate efficiency of the developed approach, we introduce a numerical example that highlights its substantial benefits through a thorough comparison with current learning control methods for MJSs. Moreover, a structured population dynamics model for pests is utilized to validate the practical applicability.
More Related Videos
Related Concept Videos
 01:24
BIBO stability of continuous and discrete -time systems
To determine the BIBO stability, the convolution integral is utilized when a bounded continuous-time input is applied to a Linear Time-Invariant (LTI) system....
 01:23
Linear time-invariant Systems
The input-output behavior of an LTI system can be fully defined by its response to an impulsive excitation at its input. Once this impulse response is known, the system's reaction to any other input can be...
 01:26
Feedback control systems
Linear feedback systems are theoretical models that simplify analysis and design. These systems operate under the principle that their output is directly proportional to their input within certain ranges. For instance, an amplifier in a control system behaves linearly as long as the input signal remains within a specific range. However, most physical systems exhibit inherent nonlinearity...
 01:07
Time-Domain Interpretation of PD Control
Consider the example of control of motor torque. Initially, a positive...
 01:21
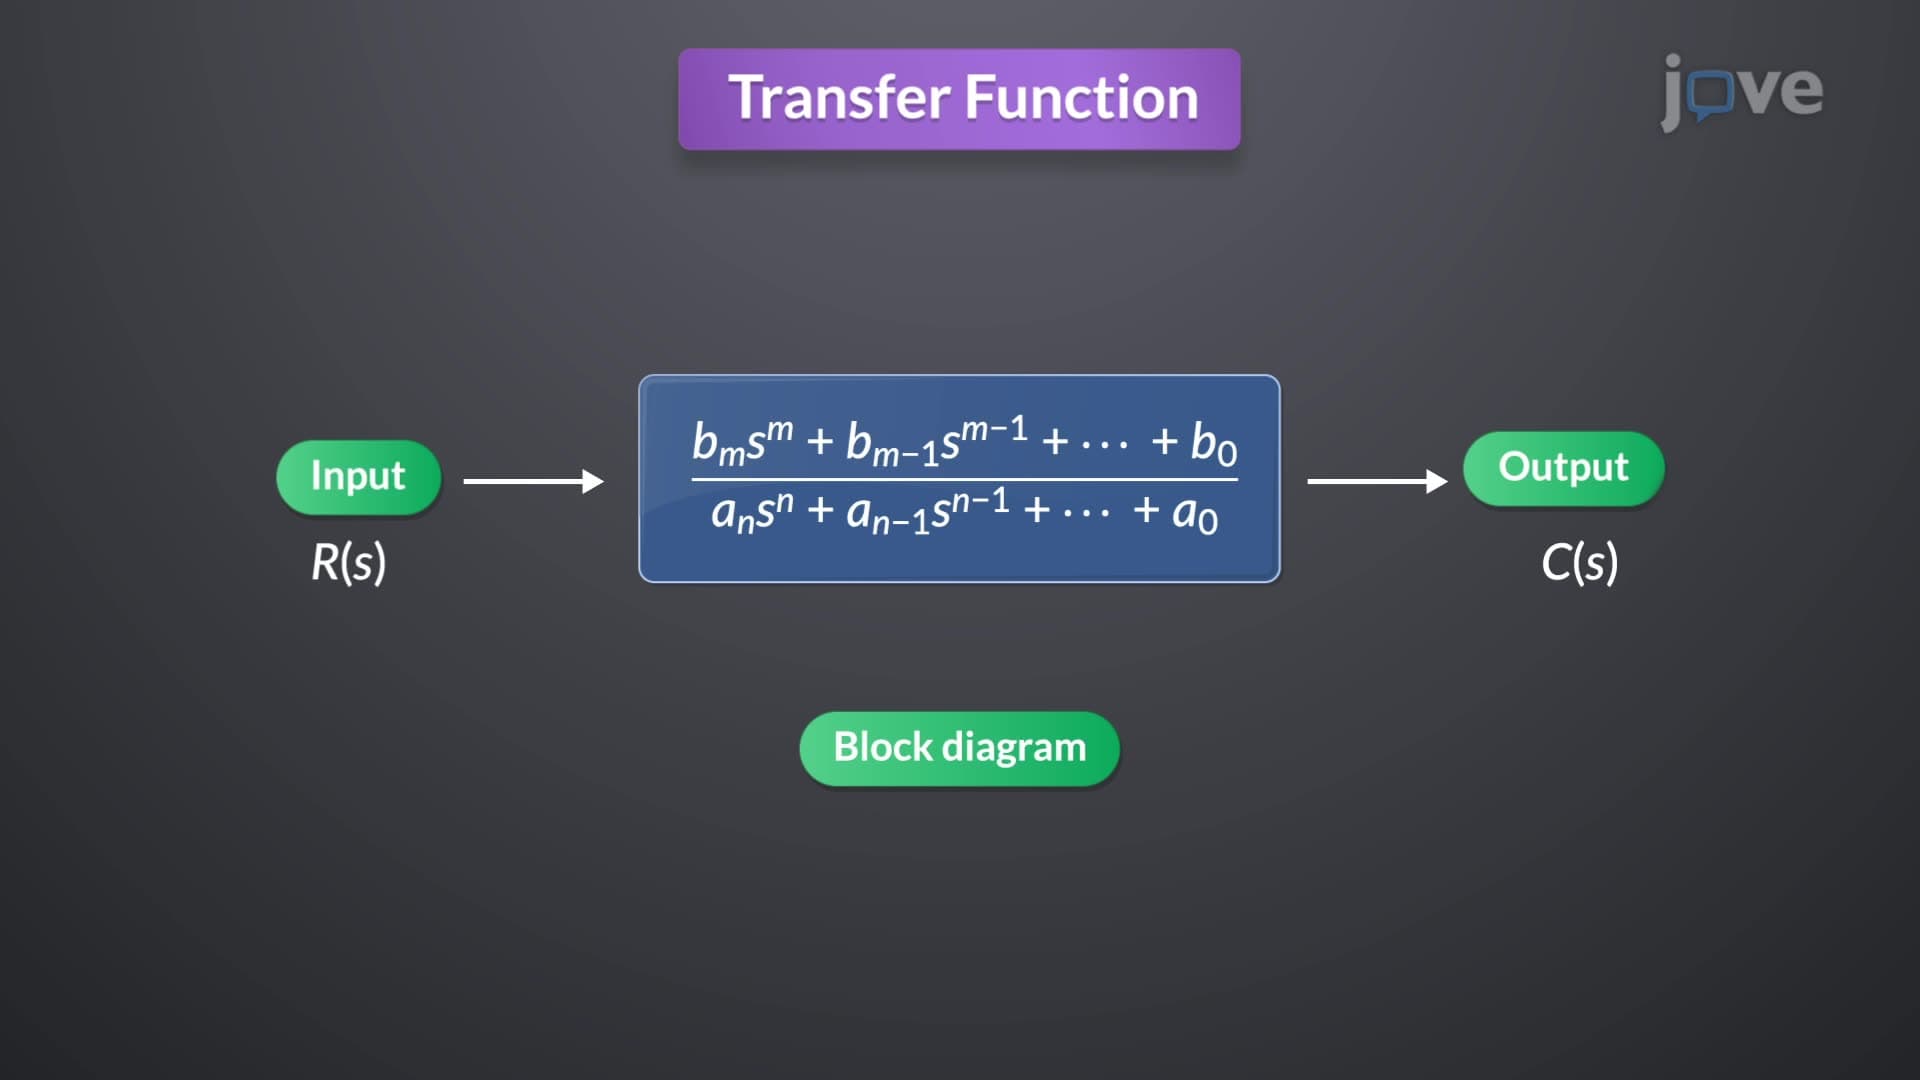
Transfer Function in Control Systems
To derive the transfer function, consider a general nth-order linear time-invariant...
 01:16
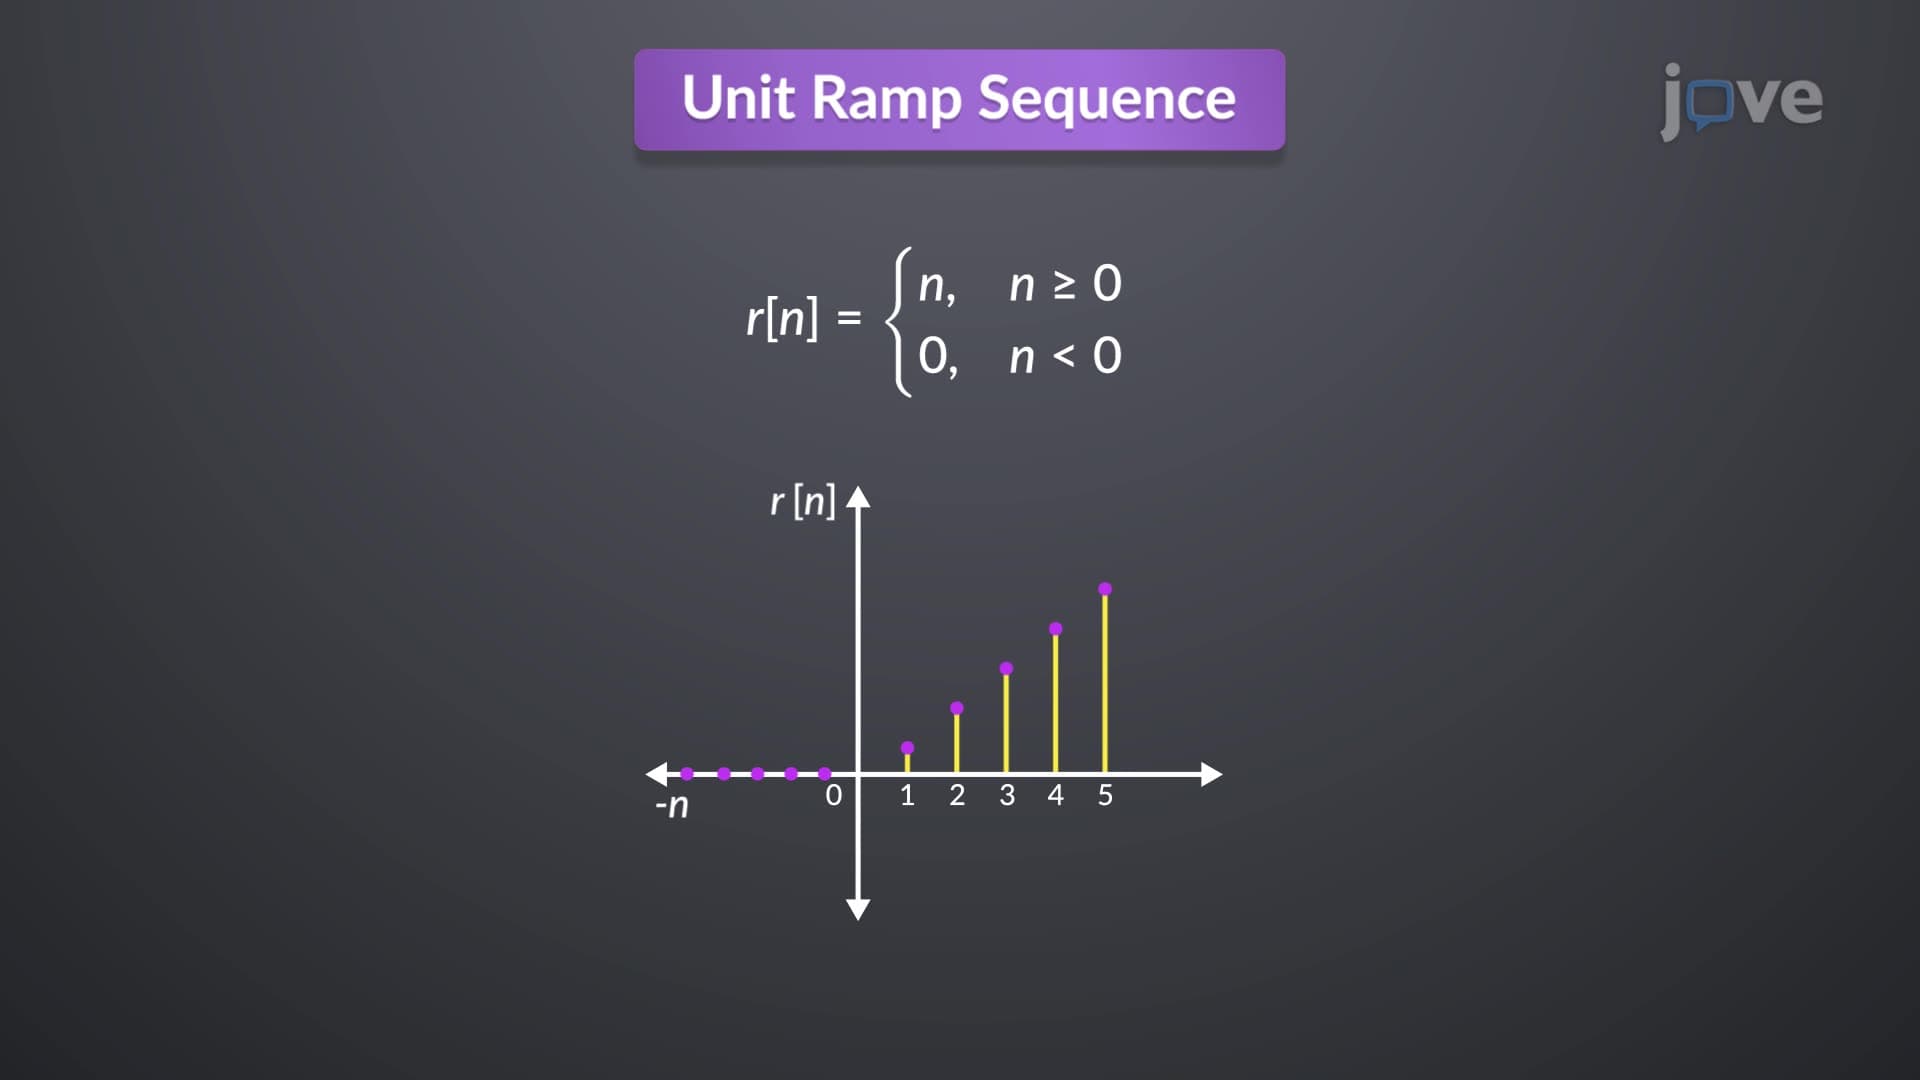
Basic Discrete Time Signals
The unit impulse or sample sequence is mathematically expressed as zero for all n values except at n=0, where it is one. The unit impulse sequence, denoted by δ(n), is the first difference of the unit step sequence, while the unit step sequence u(n) is...