Related Experiment Video
Updated: May 9, 2025

Establishing a Competing Risk Regression Nomogram Model for Survival Data
Published on: October 23, 2020
Logistic Multidimensional Data Analysis for Ordinal Response Variables Using a Cumulative Link Function
Mark de Rooij1, Ligaya Breemer1, Dion Woestenburg1
1Methodology and Statistics Department, Leiden University, Leiden, The Netherlands.

Abstract:
We present a multidimensional data analysis framework for the analysis of ordinal response variables. Underlying the ordinal variables, we assume a continuous latent variable, leading to cumulative logit models. The framework includes unsupervised methods, when no predictor variables are available, and supervised methods, when predictor variables are available. We distinguish between dominance variables and proximity variables, where dominance variables are analyzed using inner product models, whereas the proximity variables are analyzed using distance models. An expectation-majorization-minimization algorithm is derived for estimation of the parameters of the models. We illustrate our methodology with three empirical data sets highlighting the advantages of the proposed framework. A simulation study is conducted to evaluate the performance of the algorithm.
More Related Videos

Related Concept Videos
 00:55
Ordinal Level of Measurement
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
 01:19
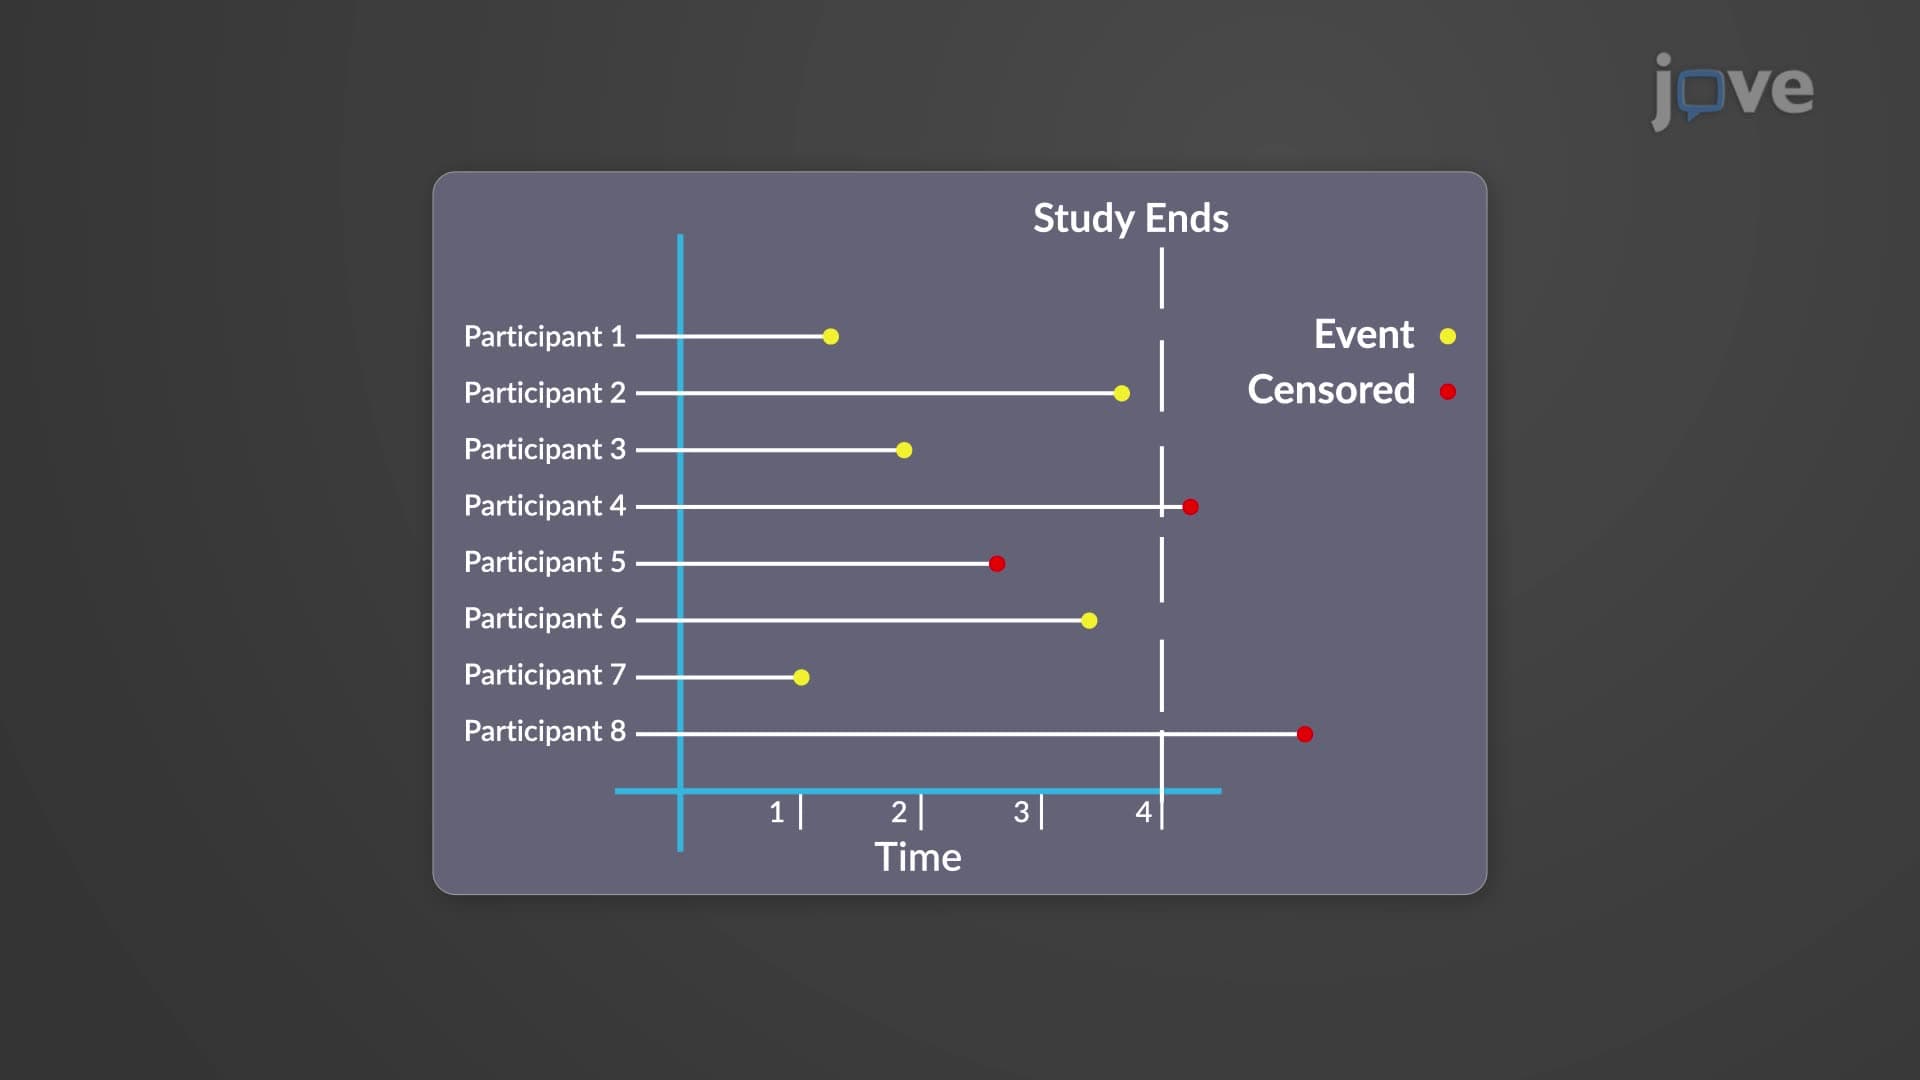
The Mantel-Cox Log-Rank Test
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...