Related Experiment Video
Updated: Jan 14, 2026

Curation of Computational Chemical Libraries Demonstrated with Alpha-Amino Acids
Published on: April 13, 2022
Direct construction of sparse suffix arrays with Libsais
Simon Van de Vyver1, Tibo Vande Moortele1, Peter Dawyndt1
1Department of Mathematics, Computer Science and Statistics, Faculty of Sciences, Ghent University, Ghent, 9000, Belgium.

Background:
Pattern matching is a fundamental challenge in bioinformatics, especially in the fields of genomics, transcriptomics and proteomics. Efficient indexing structures, such as suffix arrays, are critical for searching large datasets. A sparse suffix array (SSA) retains only suffixes at every k-th position in the text, where k is the sparseness factor. While sparse suffix arrays offer significant memory savings compared to full suffix arrays, they typically still require the construction of a full suffix array prior to a sampling step, resulting in substantial memory overhead during the construction phase.
Results:
We present an alternative method to directly construct the sparse suffix array using a simple, yet powerful text encoding. This encoding reduces the input text length by grouping characters, thereby enabling direct SSA construction by extending the widely used Libsais library. This approach bypasses the need to construct a full suffix array, reducing memory usage and construction time by 50 to 75% when building a sparse suffix array with sparseness factor 3 or 4 for various nucleotide and amino acid datasets. Depending on the alphabet size, similar gains can be achieved for sparseness factors up to 8. For higher sparseness factors, comparable performance improvements can be obtained by constructing the SSA using a suitable divisor of the desired sparseness factor, followed by a subsampling step. The method is particularly effective for applications with small alphabets, such as a nucleotide or amino acid alphabet. An open-source implementation of this method is available on GitHub, enabling easy adoption for large-scale bioinformatics applications.
Conclusions:
We introduce an efficient method for the construction of sparse suffix arrays for large datasets. Central to this approach is the introduction of a simple text transformation, which then serves as input to Libsais. This method reduces the length of both the input text and the resulting suffix array by a factor of k, which improves execution time and memory usage significantly.
Related Concept Videos
 01:16
SFG Algebra
Each node in an SFG corresponds to a variable, and the interactions between nodes are represented by branches with associated gains. When multiple branches lead into a node, the value at that node is the sum of the...
 01:15
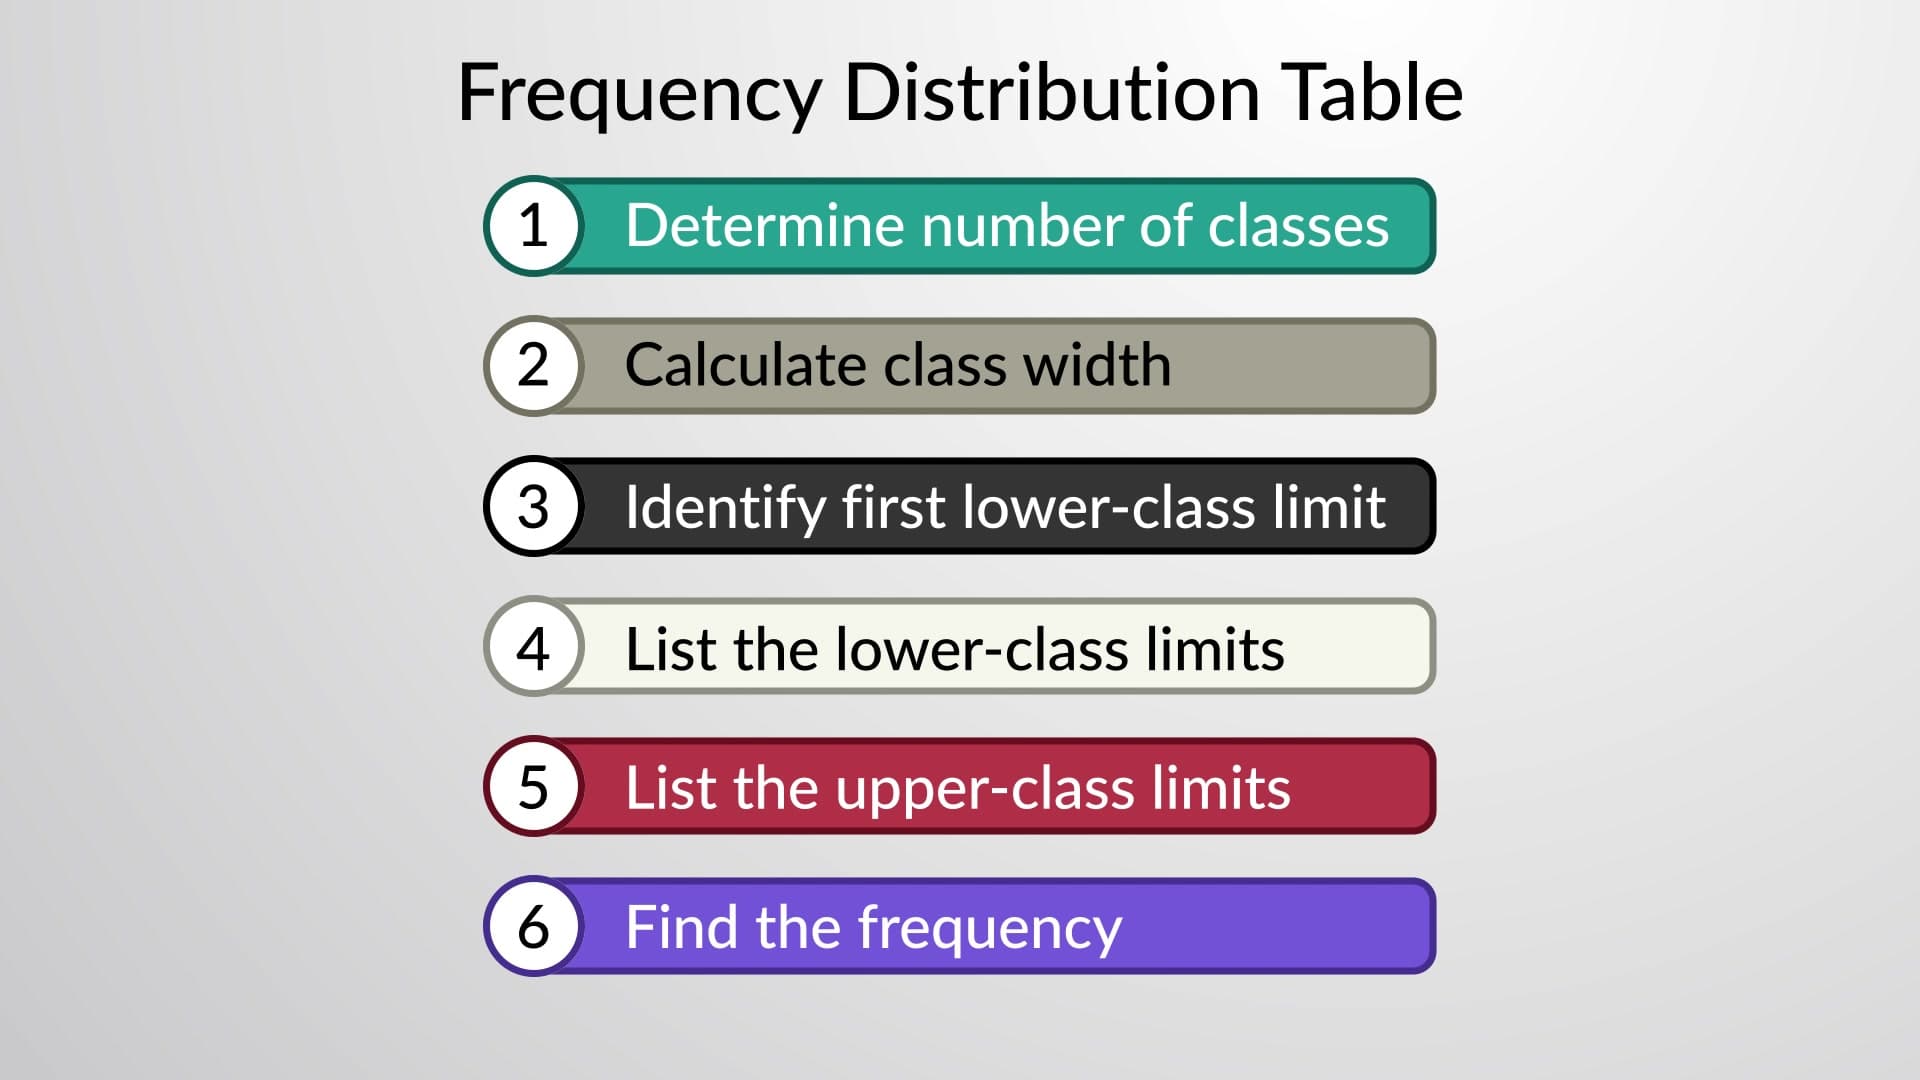
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is...
 02:56
Buffers
 01:28
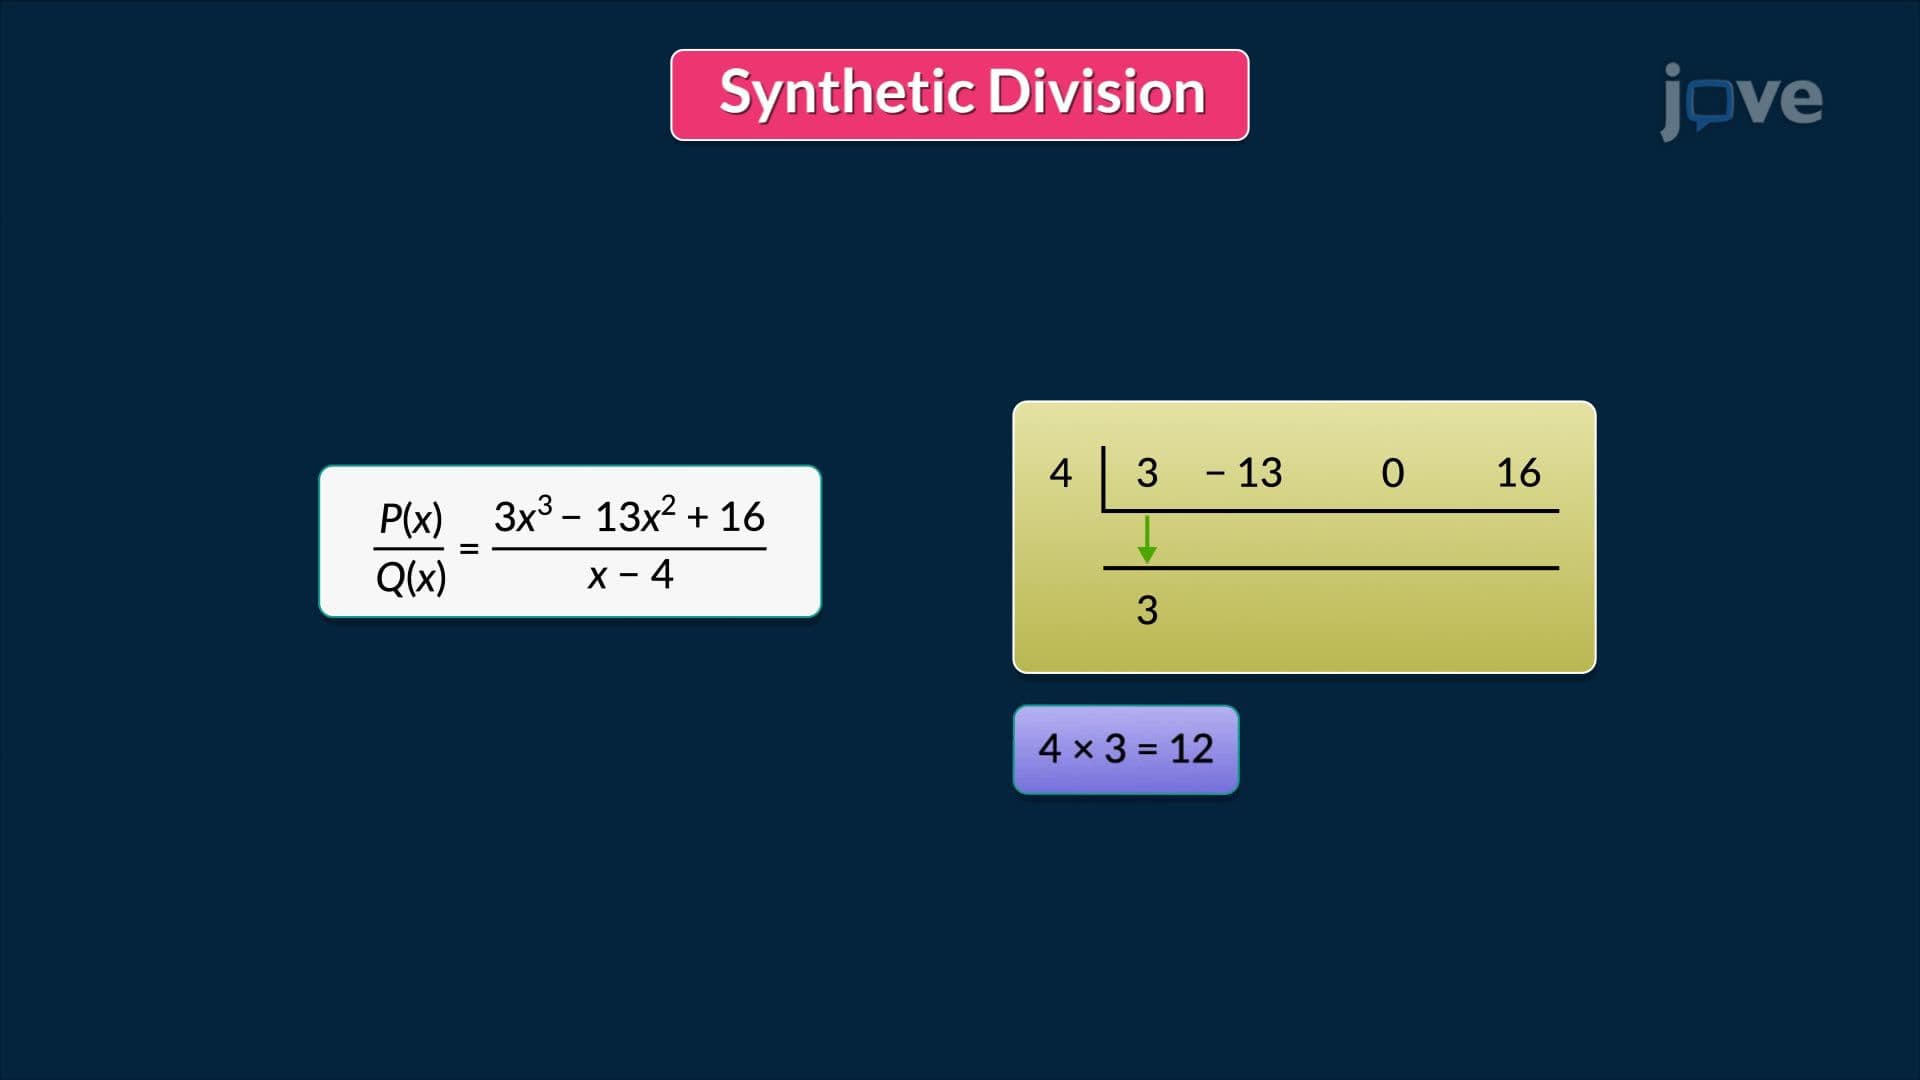
Synthetic Disvision of Polynomials
 01:14
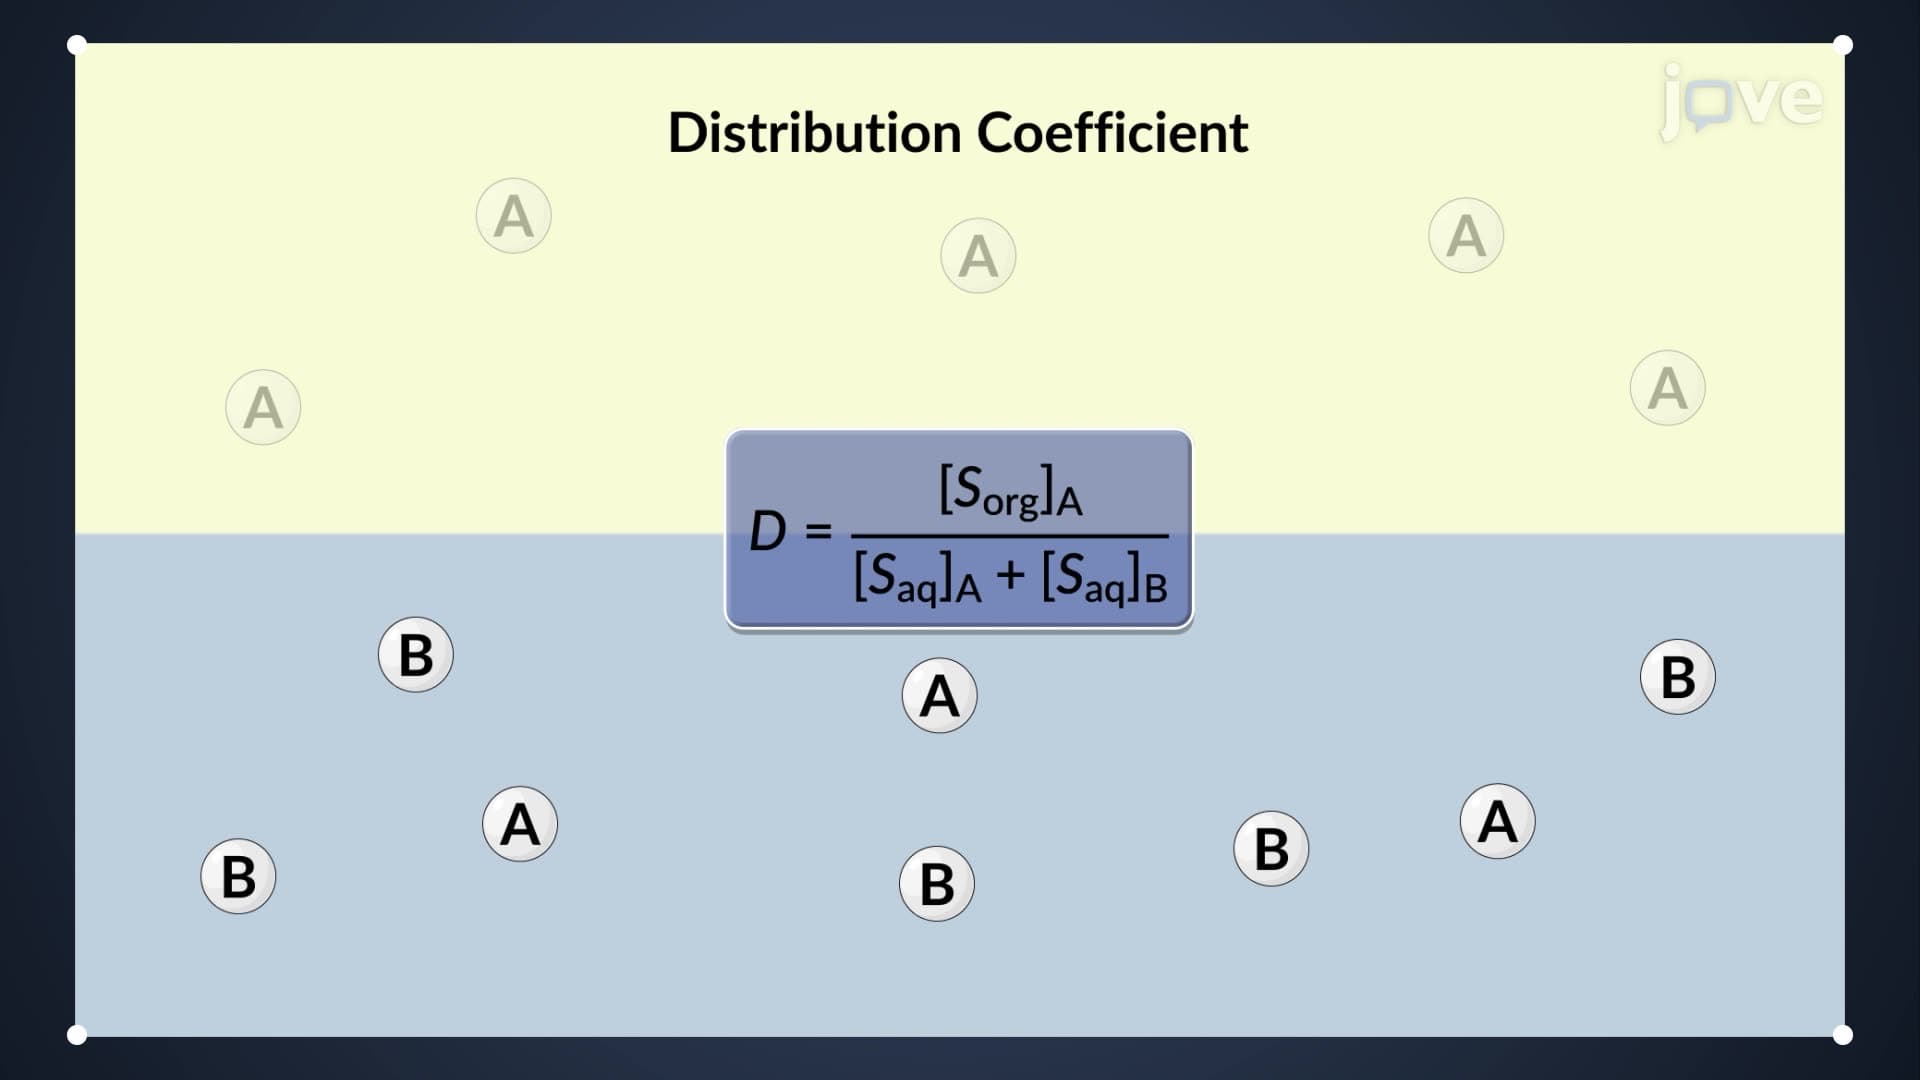
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:18
Assembly of Cytoskeletal Filaments