Trustworthy navigation with variational policy in deep reinforcement learning
Related Experiment Video
Updated: Jan 14, 2026
A Networked Desktop Virtual Reality Setup for Decision Science and Navigation Experiments with Multiple Participants
Published on: August 26, 2018
Karla Bockrath1, Liam Ernst1, Rohaan Nadeem1
1Chester F. Carlson Center for Imaging Science, Rochester Institute of Technology, Rochester, NY, United States.

Introduction:
Developing a reliable and trustworthy navigation policy in deep reinforcement learning (DRL) for mobile robots is extremely challenging, particularly in real-world, highly dynamic environments. Particularly, exploring and navigating unknown environments without prior knowledge, while avoiding obstacles and collisions, is very cumbersome for mobile robots.
Methods:
This study introduces a novel trustworthy navigation framework that utilizes variational policy learning to quantify uncertainty in the estimation of the robot's action, localization, and map representation. Trust-Nav employs the Bayesian variational approximation of the posterior distribution over the policy-based neural network's parameters. Policy-based and value-based learning are combined to guide the robot's actions in unknown environments. We derive the propagation of variational moments through all layers of the policy network and employ a first-order approximation for the nonlinear activation functions. The uncertainty in robot action is measured by the propagated variational covariance in the DRL policy network. At the same time, the uncertainty in the robot's localization and mapping is embedded in the reward function and stems from the traditional Theory of Optimal Experimental Design. The total loss function optimizes the parameters of the policy and value networks to maximize the robot's cumulative reward in an unknown environment.
Results:
Experiments conducted using the Gazebo robotics simulator demonstrate the superior performance of the proposed Trust-Nav model in achieving robust autonomous navigation and mapping.
Discussion:
Trust-Nav consistently outperforms deterministic DRL approaches, particularly in complicated environments involving noisy conditions and adversarial attacks. This integration of uncertainty into the policy network promotes safer and more reliable navigation, especially in complex or unpredictable environments. Trust-Nav offers a step toward deployable, self-aware robotic systems capable of recognizing and responding to their own limitations.
Related Concept Videos
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:12
Observational Learning
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 01:09
Decision Making: P-value Method
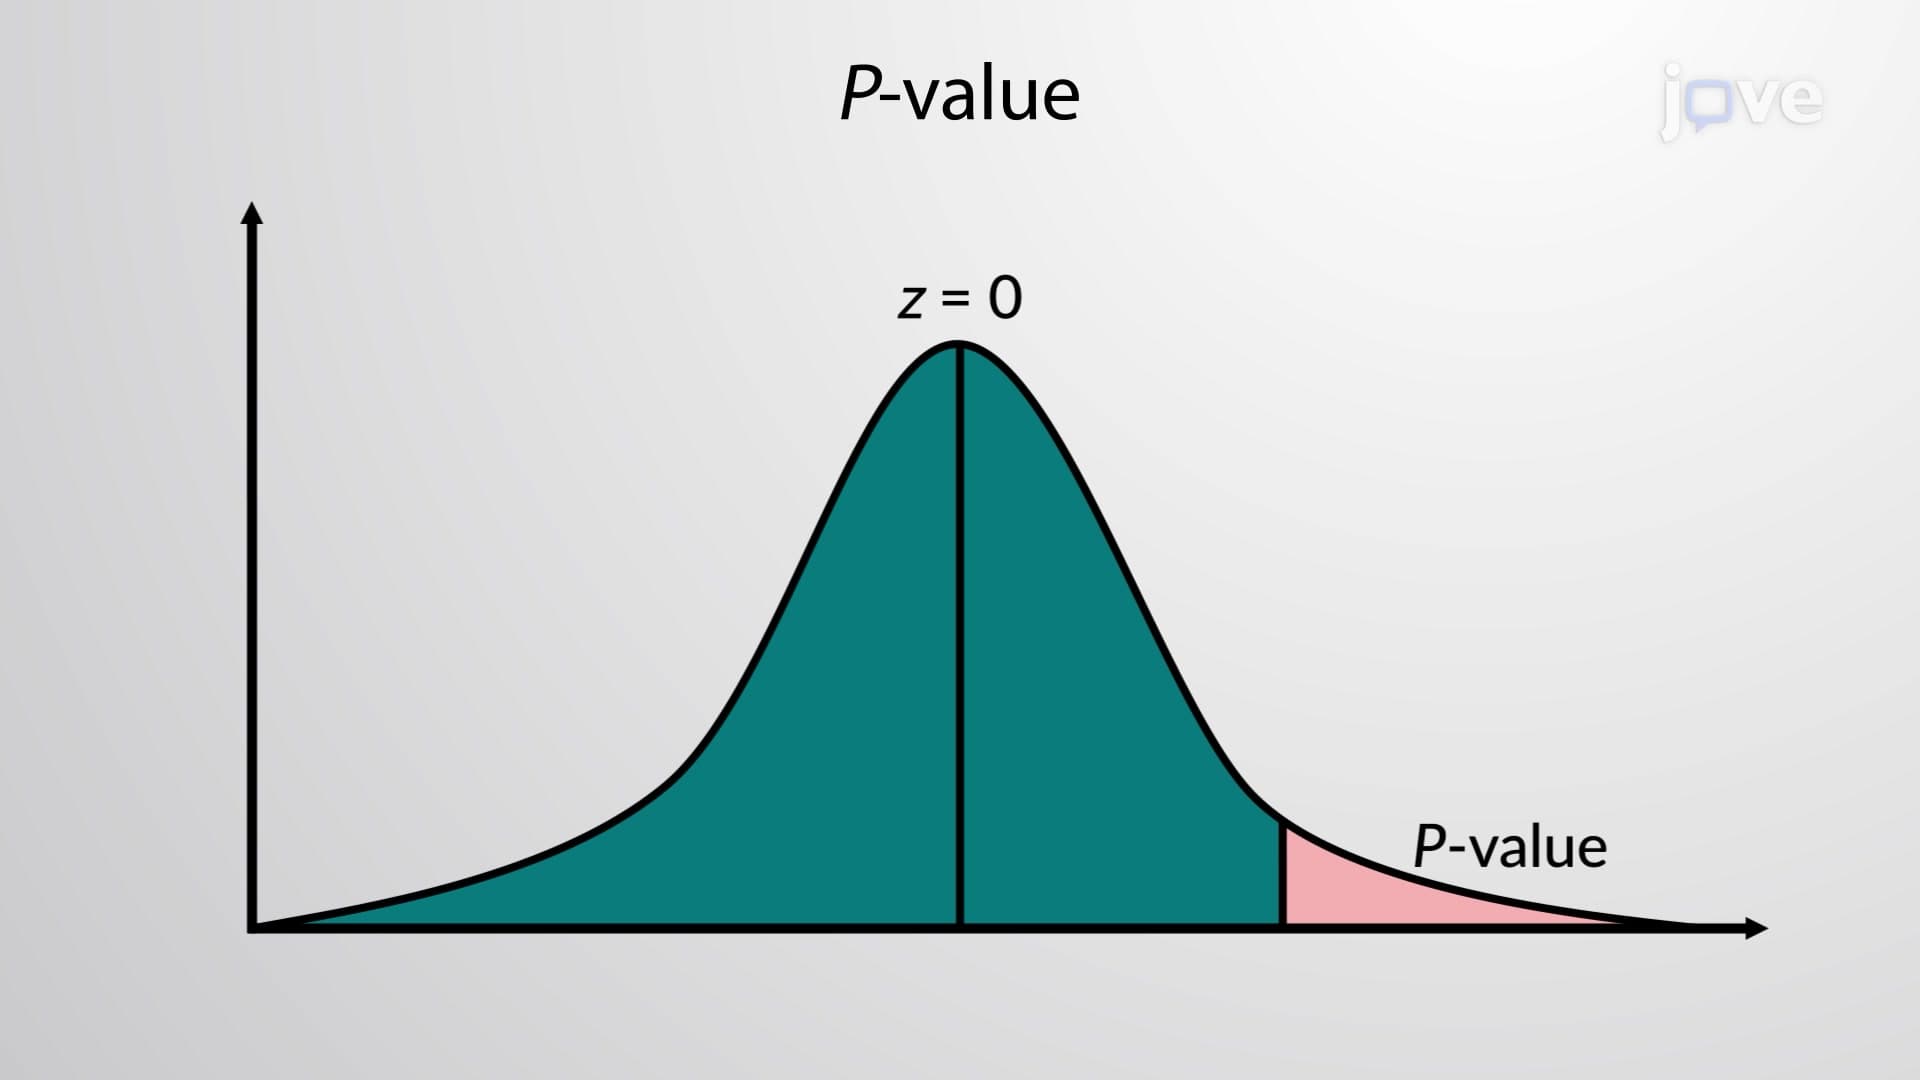
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 00:59
Propagation of Uncertainty from Random Error
 01:34
Woodward–Hoffmann Selection Rules and Microscopic Reversibility