Understanding Adversarial Imitation Learning in Small Sample Regime: A Stage-Coupled Analysis
Related Experiment Video
Updated: Mar 14, 2026
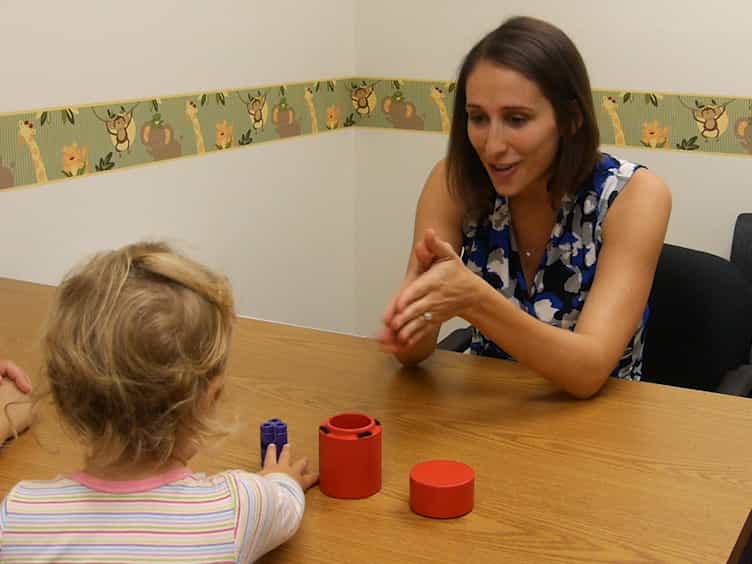
Examining Recall Memory in Infancy and Early Childhood Using the Elicited Imitation Paradigm
Published on: April 28, 2016

Abstract:
Imitation learning (IL) learns a policy from expert trajectories, serving as a fundamental paradigm in both large language model training and embodied AI. This process is challenging due to the nature of sequential decision-making where errors can accumulate and distributions may shift over horizons. However, it has been found that a kind of IL approach, adversarial imitation learning (AIL), can have exceptional empirical performance. With just one expert trajectory, AIL often matches the expert performance even in a long horizon, on tasks such as robotic locomotion control. There are two fundamental yet unsolved questions: why does AIL perform well with so few trajectories, and why does it maintain good performance over long horizons? Previous theoretical results fail to answer these questions as they are meaningful only in large sample regime (i.e., lots of expert trajectories) and have dependence on the decision horizon. In this paper, we analyze a total-variation-distance-based AIL (called TV-AIL), showing a horizon-free imitation gap ${\mathcal {O}}(\min \lbrace 1, \sqrt{|{\mathcal {S}}|/N} \rbrace )$O(min{1,|S|/N}) on a class of instances abstracted from robotic locomotion control tasks. Here $|{\mathcal {S}}|$|S| is the state space size for a Markov Decision Process (MDP), and $N$N is the number of expert trajectories. We emphasize two important features of our bound. First, this bound is meaningful in both small and large sample regimes. Second, this bound suggests that the imitation gap of TV-AIL does not increase with the decision horizon. Together, our bound can therefore explain the empirical observations and provide insights into how AIL addresses the distribution shift issue. Our analysis leverages the multi-stage policy optimization structure in TV-AIL and presents a new stage-coupled analysis. This tool also helps analyze the worst-case imitation gap of TV-AIL, disclosing its limitations in general MDPs.
More Related Videos
Related Concept Videos
 01:12
Observational Learning
 01:13
Nonconscious Mimicry
 01:14
Avoidance Learning and Learned Helplessness
Avoidance learning occurs when an organism learns that a specific behavior can prevent an unpleasant outcome. For example, a student who receives a bad grade may start studying harder to avoid future poor grades. This behavior persists even when the negative outcome is no longer present. Avoidance learning is powerful because it maintains behavior in the absence of the...
 01:27
Associative Learning
Classical conditioning, also known...
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:18
Introduction to Learning
In contrast to learned behaviors, unlearned behaviors such as crying, sexual...