Related Experiment Video
Updated: Jul 7, 2026
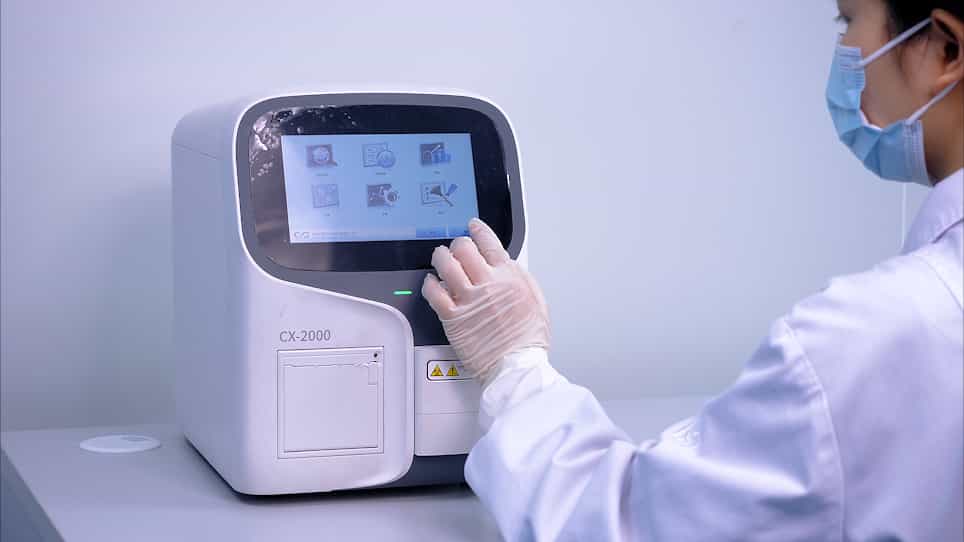
Evaluation of a Point-of-Care Testing Analyzer for Measuring Peripheral Blood Leukocytes
Published on: March 22, 2022
Performance of deepseek-R1 and ChatGPT-5.4 thinking in the medical laboratory professional title examination:
Zhili Niu1,2,3, Dongling Tang1,2,3, Juanjuan Chen1,2,3
1Department of Clinical Laboratory, Renmin Hospital of Wuhan University, Wuhan, China.

Objective:
To systematically evaluate the accuracy, reproducibility, and performance of Deepseek-R1 and ChatGPT-5.4 Thinking across different question types and disciplines in the Medical Laboratory Junior Professional Title Examination, and to compare their performance with that of interns.
Methods:
Four examination papers comprising a total of 3,879 questions were independently administered to both models in three repeated sessions. Accuracy rates were recorded, and reproducibility was assessed. Performance was further compared across three question types and five disciplines. In addition, 46 final-year interns were recruited, and their accuracy rates were compared with those of the two models.
Results:
Neither model showed significant differences in accuracy across the three repeated sessions (p > 0.05), and both demonstrated good reproducibility and stability, with Fleiss' kappa coefficients exceeding 0.7 (p < 0.001). No significant differences in accuracy were observed across question types for either model (p > 0.05). Across disciplines, Deepseek-R1 showed no significant differences across disciplines (p > 0.05), whereas ChatGPT-5.4 Thinking exhibited significant cross-disciplinary differences in Papers I, II, and III (p < 0.05). Inter-model comparison revealed that Deepseek-R1 achieved significantly higher accuracy than ChatGPT-5.4 Thinking in Papers I, II, and III (p < 0.05), while no significant difference was observed in Paper IV (p > 0.05). Both models achieved higher accuracy than interns on most papers; interns performed comparably to the AI models on Paper I but scored substantially lower on Papers II, III, and IV. Deepseek-R1 showed the highest overall performance. Analysis of error types indicated that the highest proportion of errors were those consistently incorrect across all three repetitions, suggesting stable knowledge gaps.
Conclusion:
Both Deepseek-R1 and ChatGPT-5.4 Thinking demonstrated strong performance and reproducibility in the Medical Laboratory Junior Professional Title Examination. Deepseek-R1 showed superior overall accuracy and greater disciplinary consistency. Both models outperformed fourth-year interns, highlighting their potential as auxiliary tools for examination preparation, though the use of publicly available historical questions limits conclusions about genuine reasoning ability.
