Bridging the Gap in Exam Handwritten Text Recognition: Dataset, Benchmark, and Modeling
Related Experiment Video
Updated: Aug 11, 2026
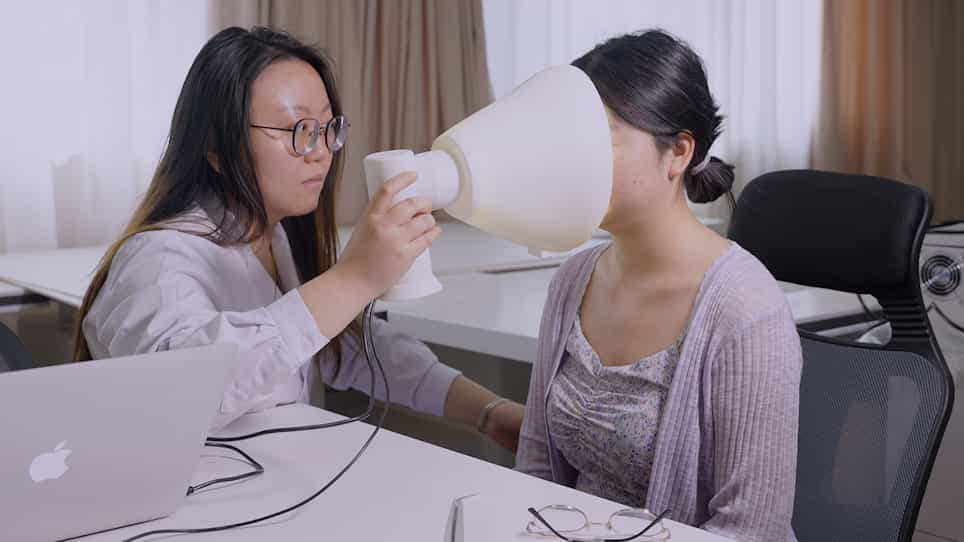
Objectification of Tongue Diagnosis in Traditional Medicine, Data Analysis, and Study Application
Published on: April 14, 2023

Abstract:
Handwritten text recognition (HTR) in examination scenarios has gained increasing attention for its role in intelligent grading systems. However, existing studies have not systematically modeled the complex handwriting phenomena inherent in exam settings, hindering a comprehensive understanding of the recognition challenges and limitations of current methods. Specifically, handwriting artifacts pose significant challenges to recognition models in two complementary aspects: sequentially, they disrupt the reading order and lead to non-monotonic sequences, while visually, they distort character structures and induce attention drift. To enable systematic benchmarking of exam handwriting, we first construct BNU-Exam-HTR, a large-scale dataset of handwritten exam text, and establish BNU-Exam-Benchmark, a fine-grained evaluation framework defining 12 representative challenges observed in real exam handwriting. To overcome these challenges, we further propose EduOCR, a recognition model with a collaborative dual-branch decoder. The Sequential Symbol Module (SSM) uses autoregressive decoding to handle non-monotonic sequences, while the Permutation-Aware Prediction Head (PPH) simulates artifact perturbations to guide the shared encoder in distinguishing characters from noise, thus stabilizing attention and mitigating alignment errors. Extensive experiments show that EduOCR consistently outperforms state-of-the-art HTR models, OCR tools, and multimodal large language models across all 12 challenges, demonstrating superior robustness and adaptability.