Related Experiment Videos
Regret Bound for Multi-Armed Bandits with Discounting: A Robust Stochastic Control Approach
1School of Mathematics and Statistics, University of Sydney, Sydney 2006, Australia.

Abstract:
We investigate the exact regret bound for stochastic multi-armed bandit problems with discounting, by formulating the regret bound as the value of a robust stochastic control problem. We first show that the regret bound coincides with the value associated with the Bayesian optimization problem under the worst prior. However, a solution to this Bayesian optimization may not be an optimal strategy for the robust control problem. To resolve this dilemma, we introduce an entropy regularization term into the cost function. In this way, we prove the existence of a saddle point for the entropy-regularized robust control. Moreover, the unique optimal strategy for the Bayesian optimization under the worst prior is also an (almost) optimal strategy for the original robust stochastic control problem.
Related Concept Videos
 01:30
Lagrange Multipliers: Problem Solving
 01:22
Multi-input and Multi-variable systems
In the absence of...
 01:28
Lagrange Multipliers: Two Constraints
 01:29
Lagrange Multipliers: One Constraint
 01:09
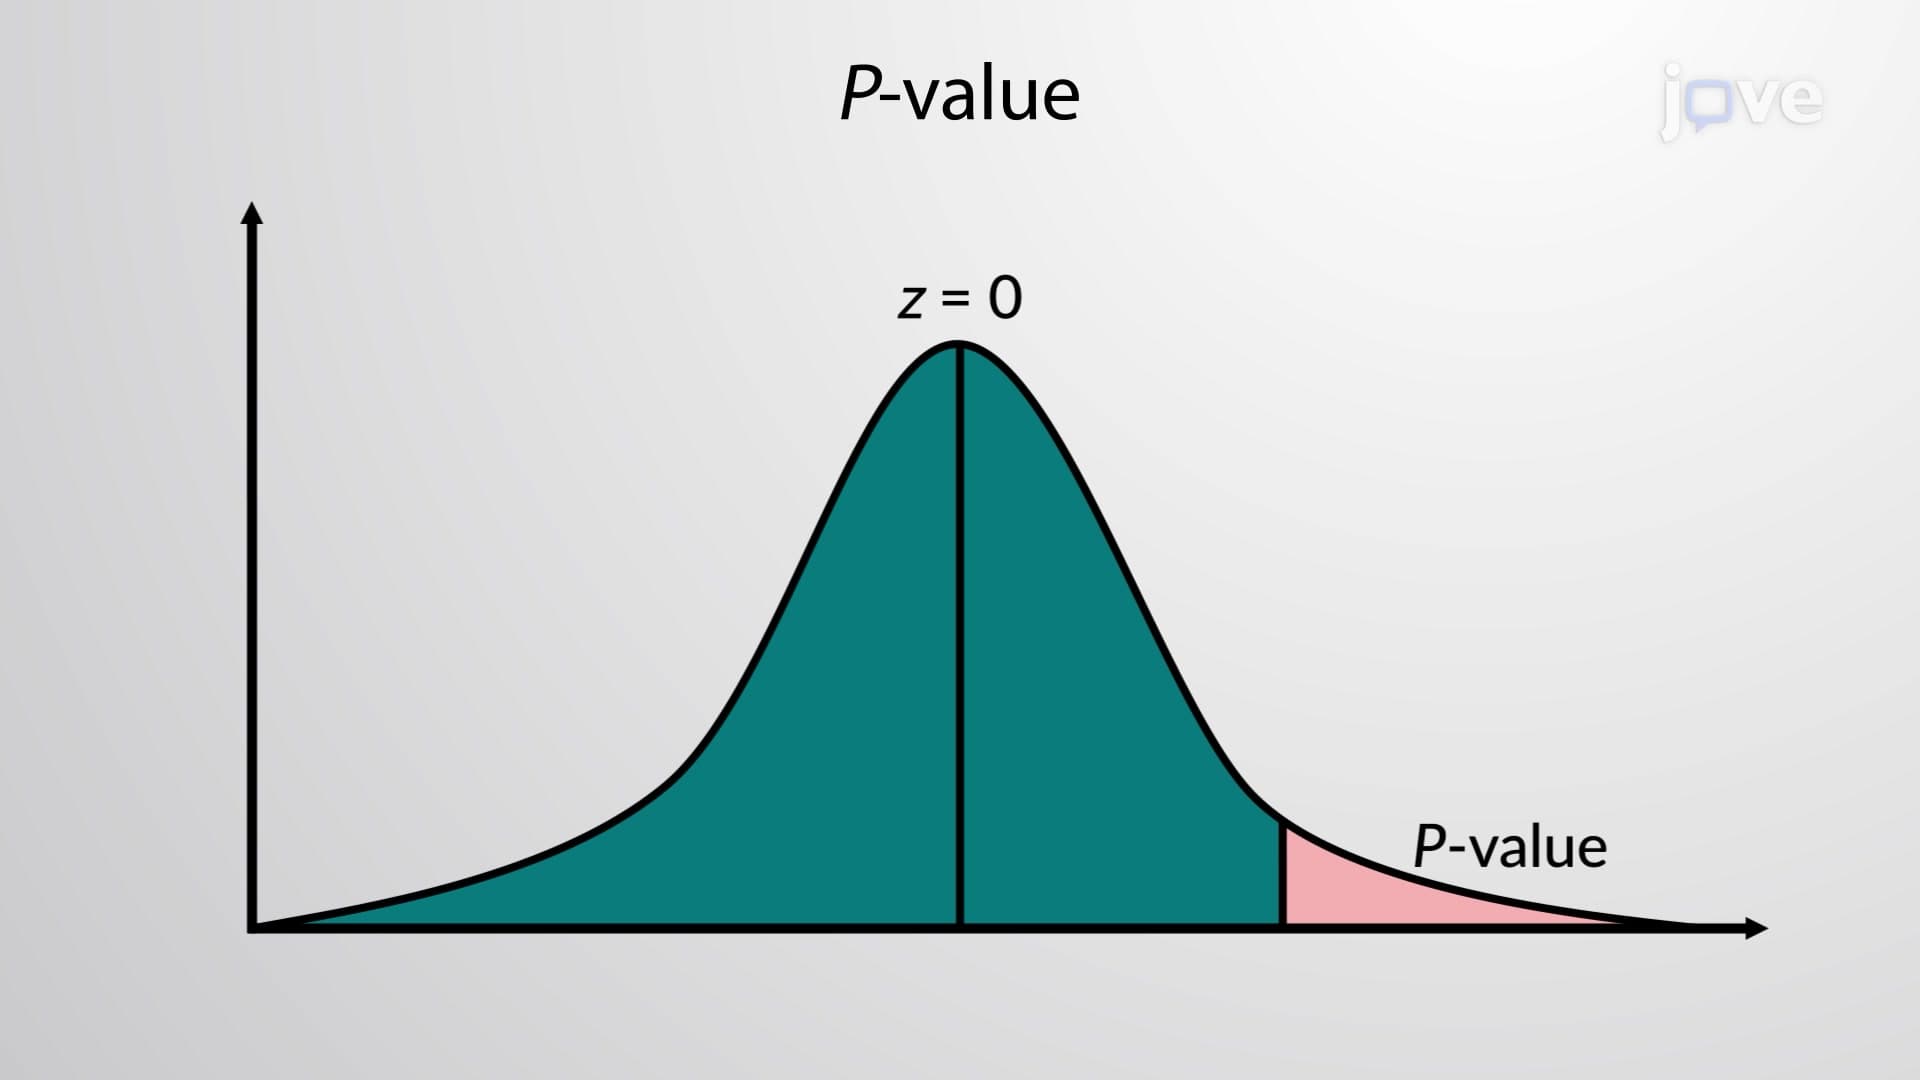
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can have a...
 01:22
Controller Configurations
Control-system compensation involves various configurations, most commonly series or cascade compensation, in which the controller aligns...