How well do video-language models understand traffic risk?: Three-stage comparative evaluation in driving video
Related Experiment Video
Updated: Nov 5, 2026
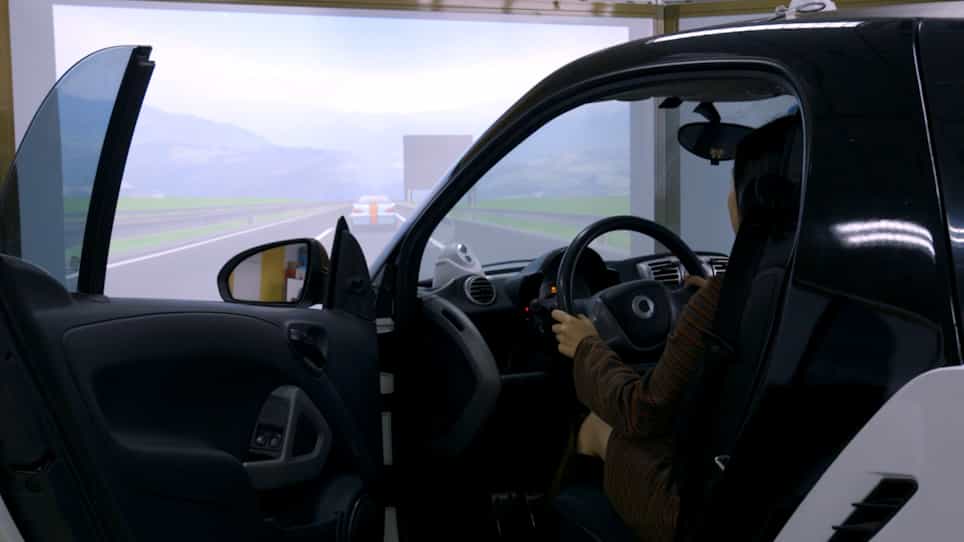
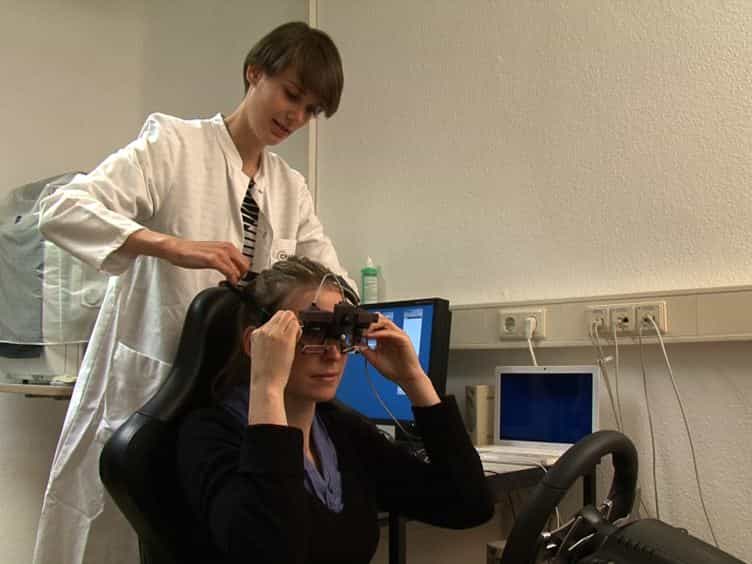
Tactile Vibrating Toolkit and Driving Simulation Platform for Driving-Related Research
Published on: December 18, 2020
1Department of Transportation and Logistics Engineering, Hanyang University ERICA, Ansan, 15588, South Korea.

Abstract:
In autonomous driving, video-language models (VLMs) increasingly promise natural-language interpretation of driving scenes, yet whether they can reliably support safety-critical traffic risk understanding remains unclear. To address this, we benchmark seven VLMs on real-road dashcam videos in CoVLA. We propose a three-stage evaluation benchmark that decomposes driving-scene risk assessment into spatiotemporal environment perception (Q1), interaction understanding between agents (Q2), and critical risk identification (Q3), and operationalizes each stage as a scoreable multiple-choice probe derived from caption-based video labels. Using 500 dashcam clips sampled from the CoVLA dataset (1500 question items in total), we compare Qwen3VL (8B), InternVL3.5 (8B), VideoLLaMA3 (7B), BLIP3 (4B), SALMONN2+ (7B), Videochat-R1.5 (7B), and GLM 4.6v-flash (9B) under two dialogue modes: single-turn, in which each question is processed independently with a fully reset context, and multi-turn, in which questions are presented sequentially so that the model retains its own prior responses as context history. The quantitative evaluation employs overall accuracy, question-wise accuracy, mode shift (ΔOverall), and Q3 macro-F1 and balanced accuracy, while the qualitative evaluation examines context usage, visual grounding, hazard prioritization, and failure patterns across selected illustrative scenarios. In the single-turn setting, Qwen3VL achieved the highest overall accuracy at 55.6%; in the multi-turn setting it maintained the lead at 53.5%. Across both modes, Q3 was consistently the most difficult stage, and differences between dialogue modes varied sharply across models: Videochat-R1.5 improved by 3.9 percentage points, whereas SALMONN2+ collapsed to 13.5% overall with 970 unparseable outputs. These results indicate that current VLMs are not yet reliable enough for direct safety-critical decision support, but they may become useful for post-hoc risk analysis, failure triage, and human-supervised scenario review as model tuning, multi-turn design, output-format control, and broader expert adjudication improve. The practical deployment of traffic risk understanding systems will require not only high accuracy but also strong visual grounding, stable context retention, accurate hazard prioritization, and robustness against error propagation.