Related Experiment Video
Updated: Jun 3, 2026
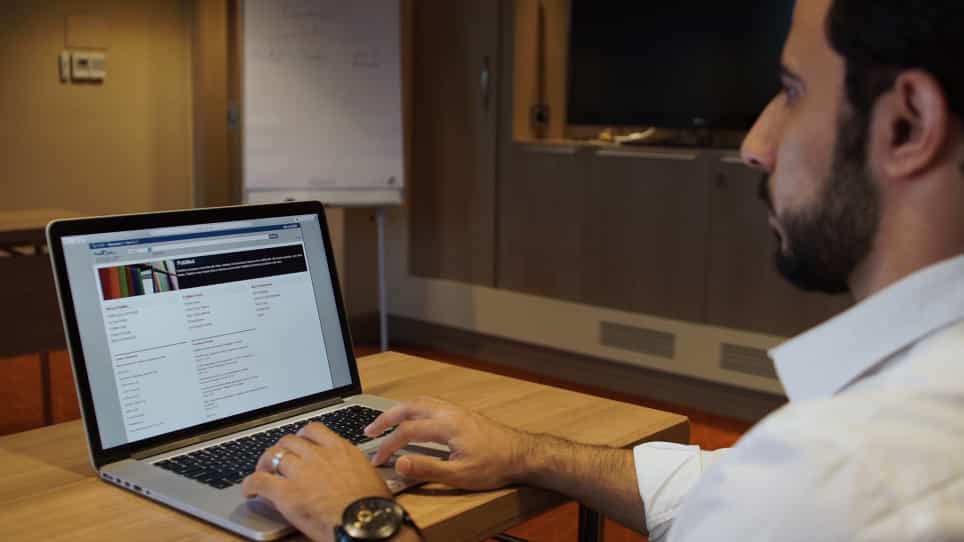

Comparing Bibliometric Analysis Using PubMed, Scopus, and Web of Science Databases
Published on: October 24, 2019
Clustering more than two million biomedical publications: comparing the accuracies of nine text-based similarity
Kevin W Boyack1, David Newman, Russell J Duhon
1SciTech Strategies, Inc., Albuquerque, New Mexico, United States of America. kboyack@mapofscience.com

Background:
We investigate the accuracy of different similarity approaches for clustering over two million biomedical documents. Clustering large sets of text documents is important for a variety of information needs and applications such as collection management and navigation, summary and analysis. The few comparisons of clustering results from different similarity approaches have focused on small literature sets and have given conflicting results. Our study was designed to seek a robust answer to the question of which similarity approach would generate the most coherent clusters of a biomedical literature set of over two million documents.
Methodology:
We used a corpus of 2.15 million recent (2004-2008) records from MEDLINE, and generated nine different document-document similarity matrices from information extracted from their bibliographic records, including titles, abstracts and subject headings. The nine approaches were comprised of five different analytical techniques with two data sources. The five analytical techniques are cosine similarity using term frequency-inverse document frequency vectors (tf-idf cosine), latent semantic analysis (LSA), topic modeling, and two Poisson-based language models--BM25 and PMRA (PubMed Related Articles). The two data sources were a) MeSH subject headings, and b) words from titles and abstracts. Each similarity matrix was filtered to keep the top-n highest similarities per document and then clustered using a combination of graph layout and average-link clustering. Cluster results from the nine similarity approaches were compared using (1) within-cluster textual coherence based on the Jensen-Shannon divergence, and (2) two concentration measures based on grant-to-article linkages indexed in MEDLINE.
Conclusions:
PubMed's own related article approach (PMRA) generated the most coherent and most concentrated cluster solution of the nine text-based similarity approaches tested, followed closely by the BM25 approach using titles and abstracts. Approaches using only MeSH subject headings were not competitive with those based on titles and abstracts.
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy
 02:26
Comparing Copy Number Variations and SNPs
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
 02:46
Chi-square Analysis
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
 02:02
Genomics