Related Experiment Video
Updated: Feb 2, 2026
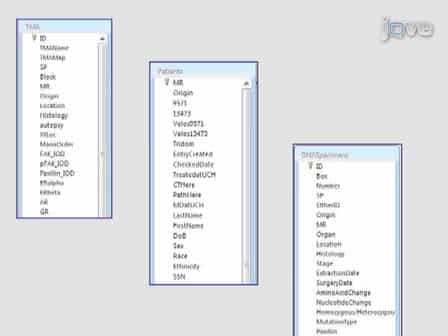

Generation of Comprehensive Thoracic Oncology Database - Tool for Translational Research
Published on: January 22, 2011
Variant information systems for precision oncology
Johannes Starlinger1,2, Steffen Pallarz3, Jurica Ševa3
1Department of Computer Science, Humboldt-Universität zu Berlin, Unter den Linden 6, Berlin, 10099, Germany. starlinger@informatik.hu-berlin.de.

Background:
The decreasing cost of obtaining high-quality calls of genomic variants and the increasing availability of clinically relevant data on such variants are important drivers for personalized oncology. To allow rational genome-based decisions in diagnosis and treatment, clinicians need intuitive access to up-to-date and comprehensive variant information, encompassing, for instance, prevalence in populations and diseases, functional impact at the molecular level, associations to druggable targets, or results from clinical trials. In practice, collecting such comprehensive information on genomic variants is difficult since the underlying data is dispersed over a multitude of distributed, heterogeneous, sometimes conflicting, and quickly evolving data sources. To work efficiently, clinicians require powerful Variant Information Systems (VIS) which automatically collect and aggregate available evidences from such data sources without suppressing existing uncertainty.
Methods:
We address the most important cornerstones of modeling a VIS: We take from emerging community standards regarding the necessary breadth of variant information and procedures for their clinical assessment, long standing experience in implementing biomedical databases and information systems, our own clinical record of diagnosis and treatment of cancer patients based on molecular profiles, and extensive literature review to derive a set of design principles along which we develop a relational data model for variant level data. In addition, we characterize a number of public variant data sources, and describe a data integration pipeline to integrate their data into a VIS.
Results:
We provide a number of contributions that are fundamental to the design and implementation of a comprehensive, operational VIS. In particular, we (a) present a relational data model to accurately reflect data extracted from public databases relevant for clinical variant interpretation, (b) introduce a fault tolerant and performant integration pipeline for public variant data sources, and (c) offer recommendations regarding a number of intricate challenges encountered when integrating variant data for clincal interpretation.
Conclusion:
The analysis of requirements for representation of variant level data in an operational data model, together with the implementation-ready relational data model presented here, and the instructional description of methods to acquire comprehensive information to fill it, are an important step towards variant information systems for genomic medicine.
Related Concept Videos
 02:30
Histone Variants at the Centromere
 03:37
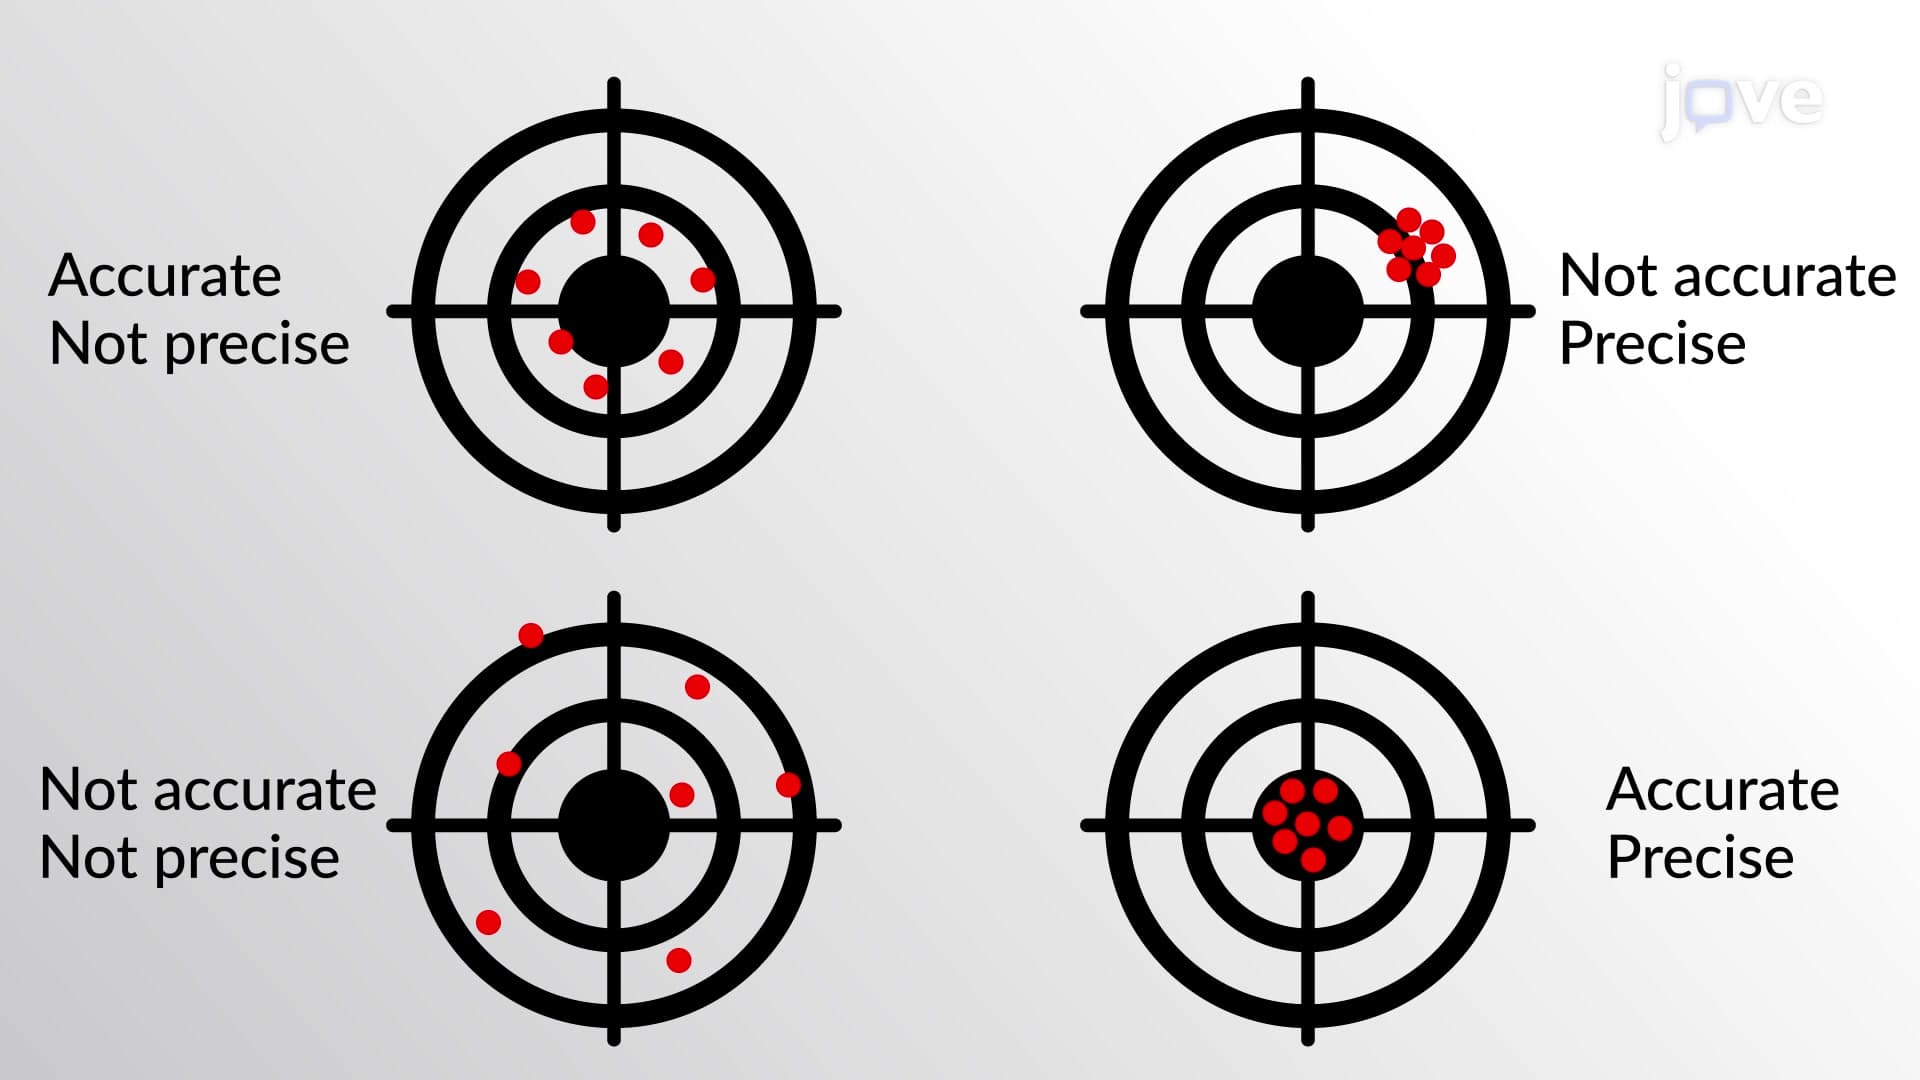
Uncertainty in Measurement: Accuracy and Precision
 01:52
Accuracy and Precision
 01:18
Second Order systems II
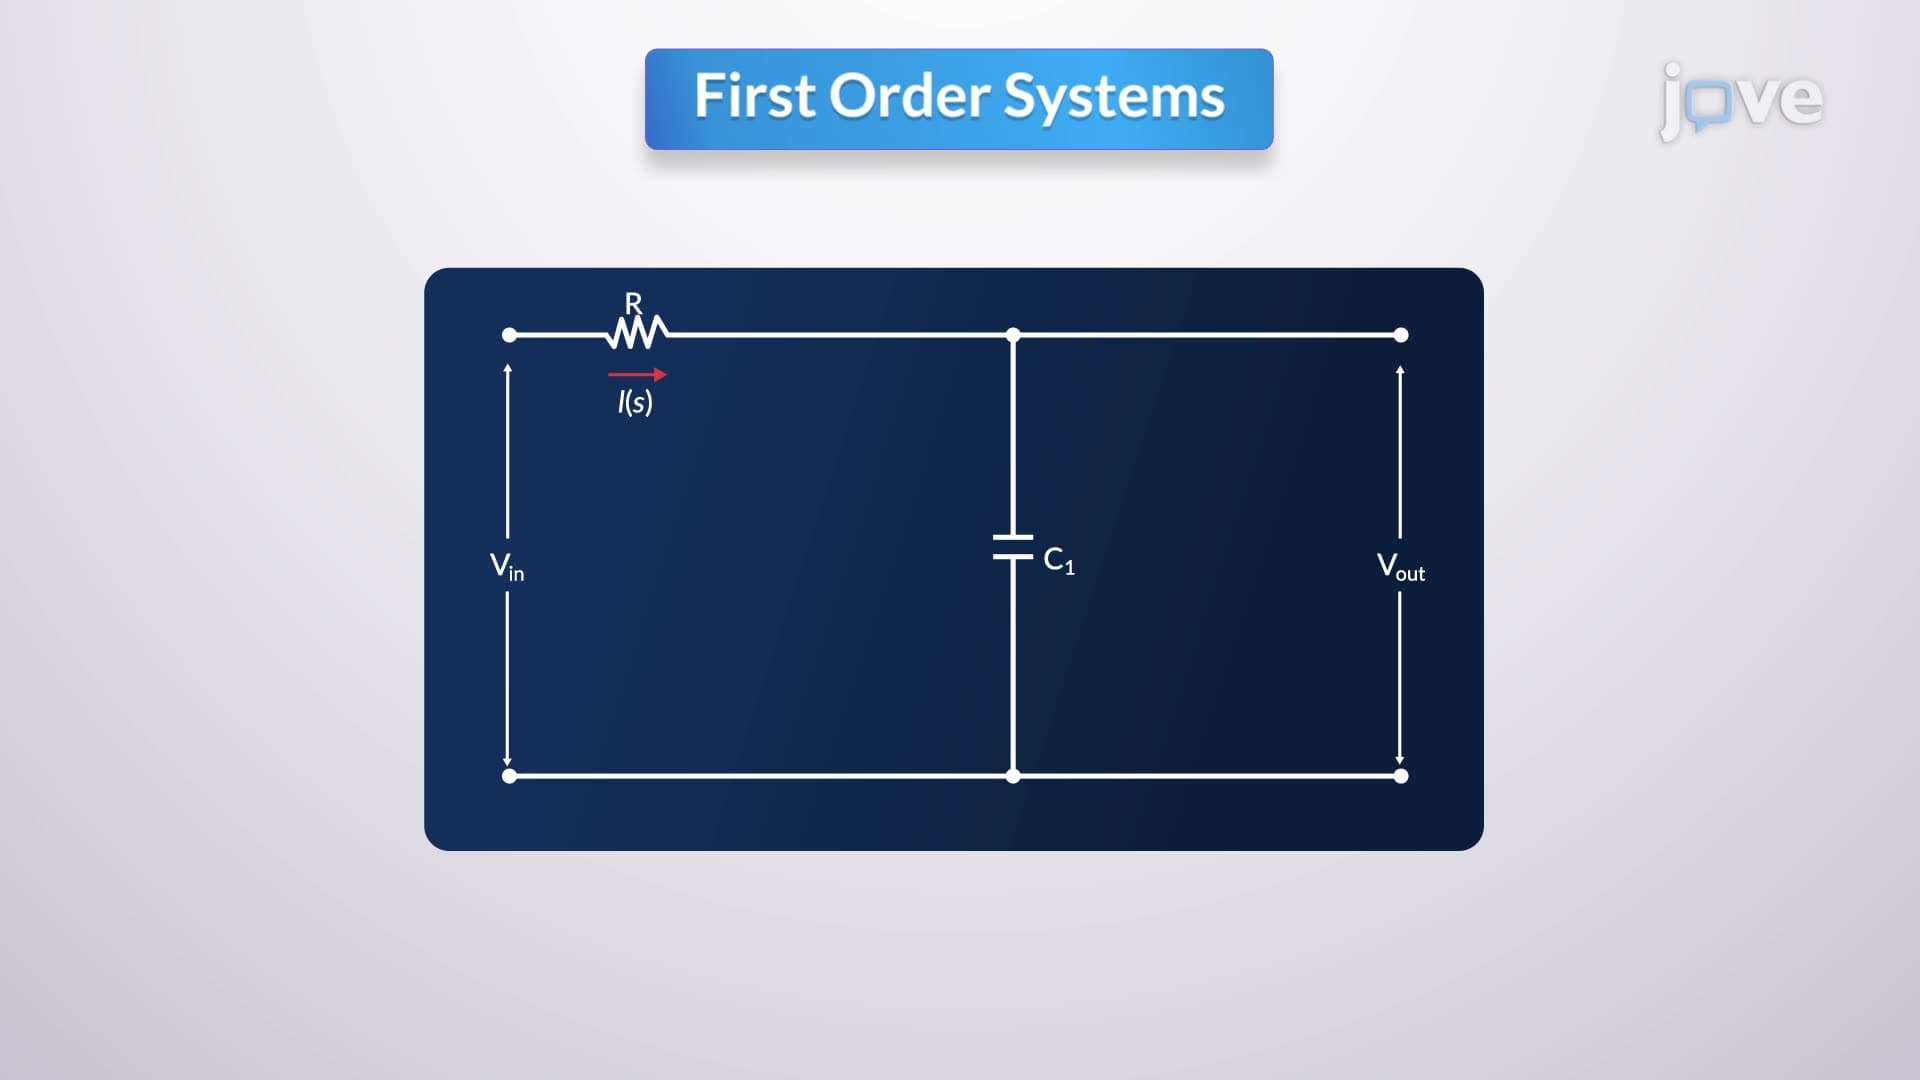 01:21
First Order Systems
When a first-order system is subjected to a unit-step input, its response is characterized by its transfer function. By applying the Laplace transform of the unit-step input to the transfer function, expanding the...
 01:20
Second Order systems I
By reinterpreting the system, one can derive the closed-loop transfer function, which...