Related Experiment Video
Updated: Jan 24, 2026

Development of an Audio-based Virtual Gaming Environment to Assist with Navigation Skills in the Blind
Published on: March 27, 2013
Reinforcement Learning-Based Intelligent Path Planning for Optimal Navigation in Dynamic Environments
Anil Kumar Yadav1, Purushottam Sharma2, Xiaochun Cheng3
1VIT Bhopal University, Bhopal-Indore Highway, Bhopal, India.

Abstract:
Path selection and planning are crucial for autonomous mobile robots (AMRs) to navigate efficiently and avoid obstacles. Traditional methods rely on analytical search to identify the shortest distance. However, Reinforcement learning enhances performance by optimizing a sequence of actions efficiently. It is an iterative approach used for computational sequence modeling and dynamic programming. RL received sensory input from the environment in the form of observation or state. The agent interpreted every reward or penalty through trial-and-error interaction. Policy maximizes the rewards and selects the optimal action among all possible actions. A challenging problem in traditional reinforcement learning is environment generalization for dynamic systems. Q-learning faces challenges in dynamic environments because it relies on rewards or penalties based on the entire sequence of actions from the start to the end state. This approach often fails to produce optimal results when the environment changes unexpectedly due to state transitions, iterations, or blocked routes. Such limitations make Q-learning less effective for dynamic path planning. To overcome these challenges, this study focuses on optimizing reward functions for efficient navigation in RL-based path planning, aiming to enhance navigation efficiency and obstacle avoidance. The proposed method evaluates the shortest decision path by considering total steps, counted steps, and discount rates in dynamic environments. By implementing this RL with an optimized reward mechanism, the study analyzes state reward values across different environments, and it evaluates the effect on state-action pair-based Q-Learning and neural networks using Deep Q-Learning algorithms. Here, results demonstrate that the optimized reward function effectively decreases the number of iterations and episodes while achieving a 30% to 70% reduction in overall trajectory distance. These results highlight the effectiveness of reward-based reinforcement learning, demonstrating its potential to improve path optimization, learning rate, episode completion, and decision accuracy in intelligent navigation systems. Q-learning-based reinforcement learning becomes more effective by combining multiple agents and utilizing decision-making techniques such as federated and transfer learning on larger maps to ensure convergence.
Related Concept Videos
 01:22
Mean free path and Mean free time
 01:21
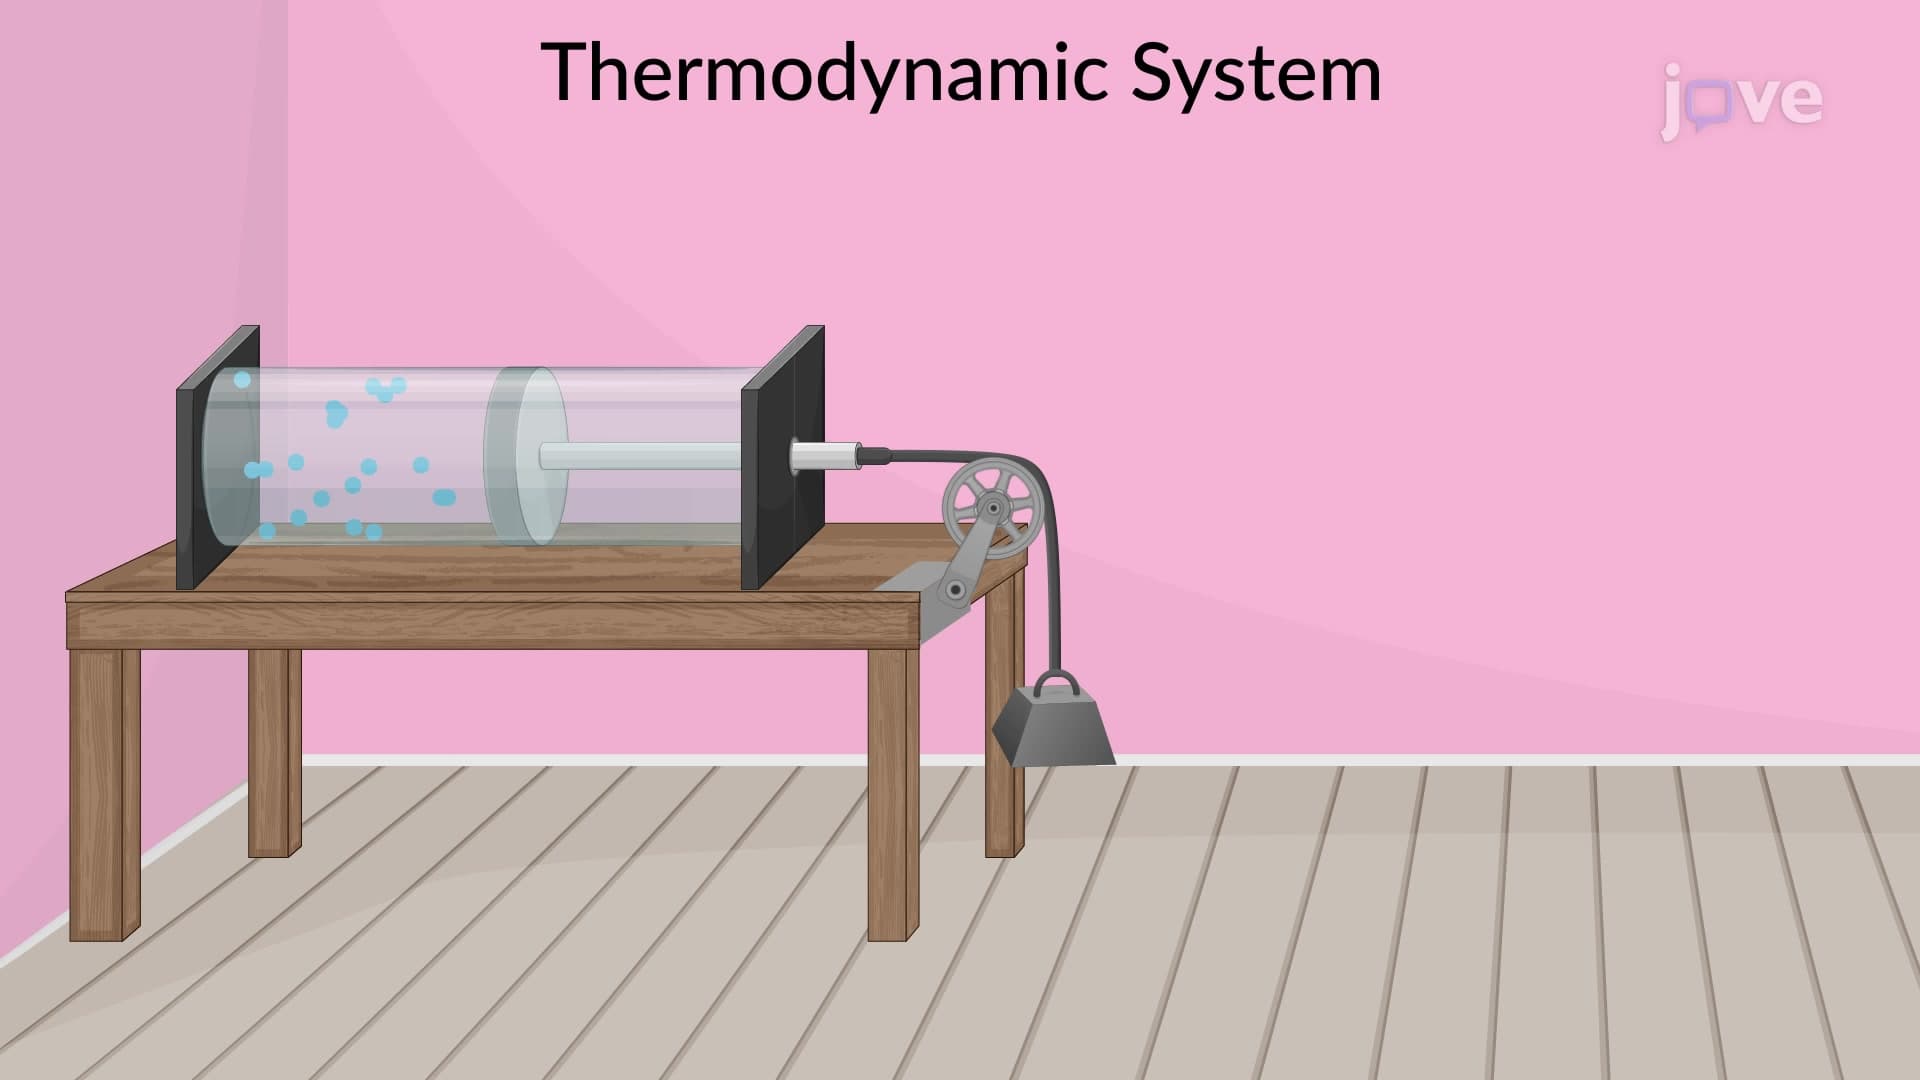
Path Between Thermodynamics States
 01:10
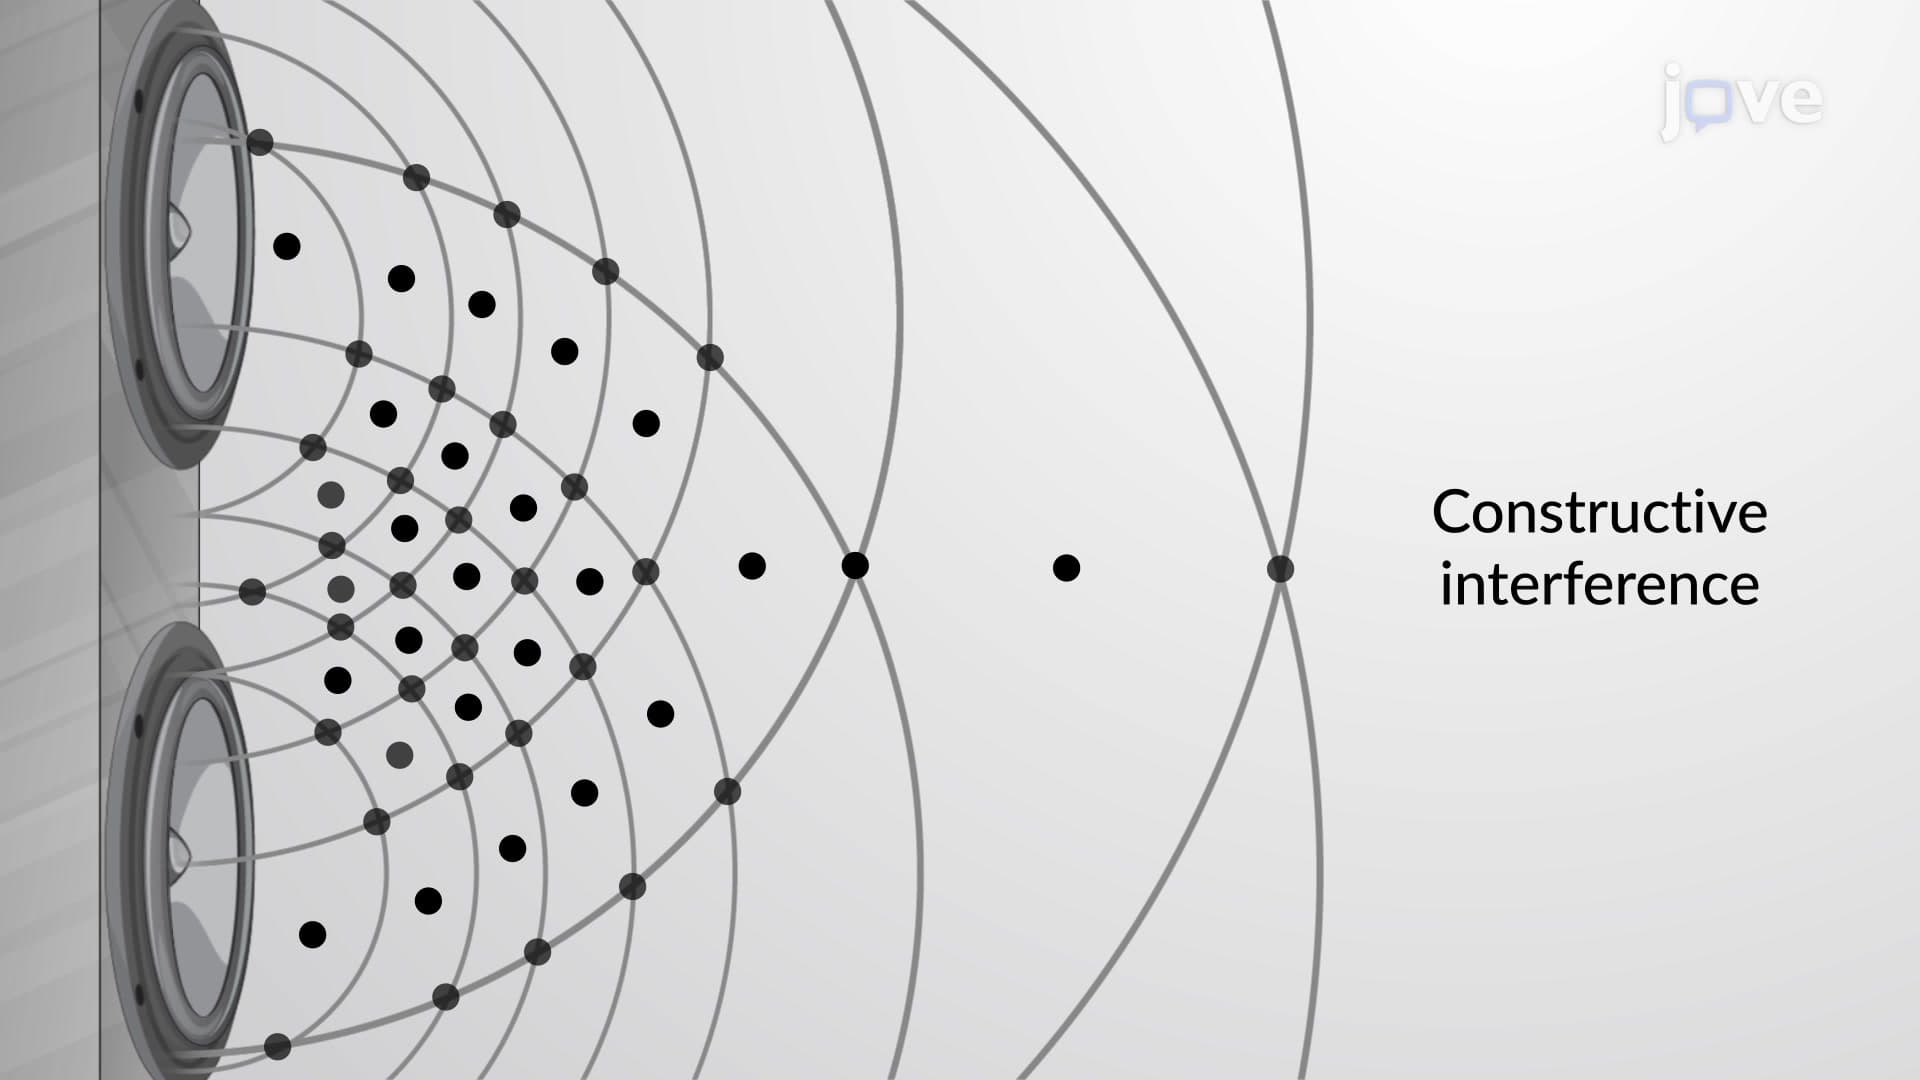
Interference: Path Lengths
Two special sources may be considered when they are in phase. This can be easily achieved by feeding the two sources from the same source. An example would be synchronizing the two speakers by feeding them with the same source, such as the sound waves produced by a tuning fork. This setup ensures that the two sources have the same frequency and are...
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:27
Intelligence
 03:48
Behavior of Gas Molecules: Molecular Diffusion, Mean Free Path, and Effusion