Related Experiment Video
Updated: May 5, 2026
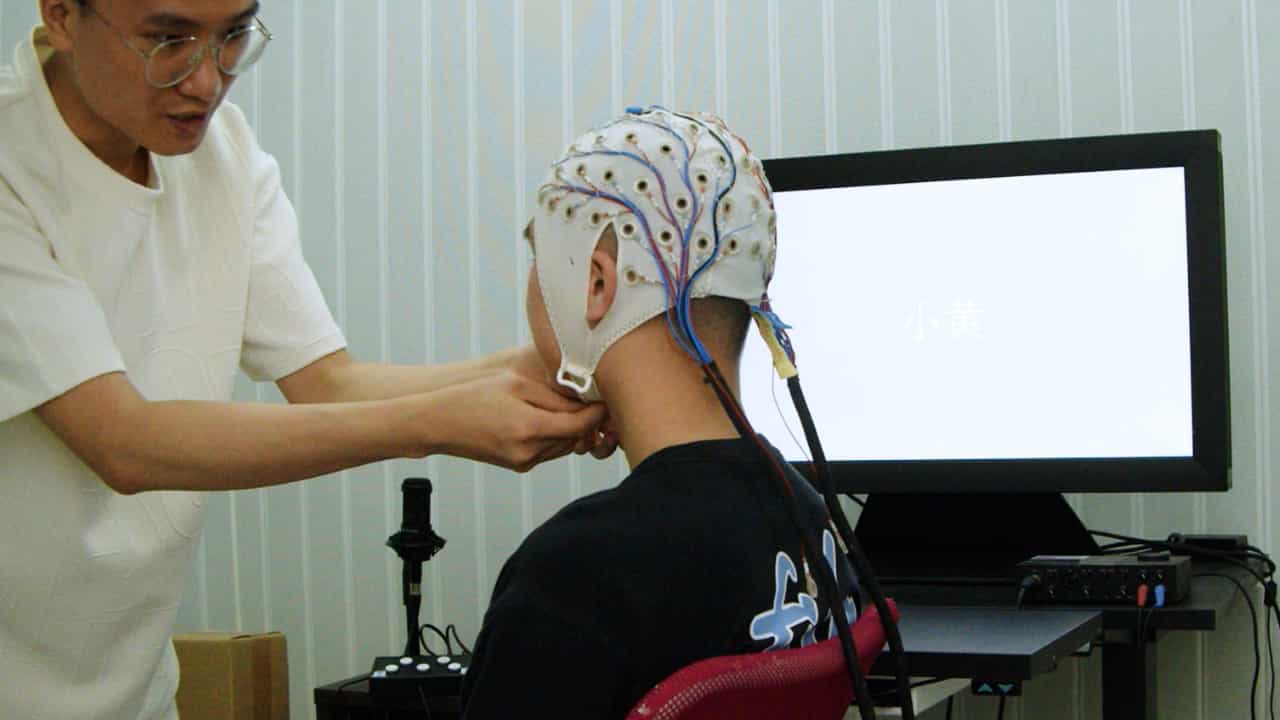

Author Spotlight: Investigating the Impact of Emotional Prosodies on Voice Recognition and Perception
Published on: August 9, 2024
Reprogramming Automatic Speech Recognition Models for Neonatal Chest Sound Separation

Abstract:
Stethoscope-recorded chest sounds are invaluable for providing a non-invasive, real-time assessment of heart and lung sounds. However, noisy chest sounds can affect the dependability of various algorithms that rely on clean chest sounds, making additional preprocessing necessary to isolate the desired sources and remove noise, interference, and artifacts. This paper is the first to explore the reprogramming of automatic speech recognition (ASR) models to perform neonatal chest sound separation. In particular, we reprogrammed the Whisper ASR model to perform chest sound separation. We proposed two approaches: reprogramming just Whisper's audio encoder and reprogramming the full Whisper model. Using only simple linear layers and learnable parameters, we showed that this parameter-efficient method of reprogramming Whisper effectively separates heart and lung sounds from noise on the artificial dataset. We also demonstrate the effectiveness of using the proposed method as a preprocessing step for various heart and lung sound algorithms, yielding results comparable to state-of-the-art performance. Applying the pre-trained ASR model to perform sound separation demonstrates the feasibility of efficient cross-domain model reprogramming, demonstrating the feasibility of using frozen cross-domain foundational models from a different domain on biomedical data.
More Related Videos
 04:04
Asthma Detection Research Based on Voice Signal Processing and Machine Learning
Published on: July 22, 2025
 06:22
Machine Learning-Based Cough Tone Classification: Diagnostic Exploration of Chronic Obstructive Pulmonary Disease and Respiratory Tract Infections
Published on: September 19, 2025
